# Ivan Misic
> Product leadership, digital transformation, and lessons from 20 years of building things that sometimes work.
## About
Ivan Misic is Director, New Growth at Deutsche Telekom, based in Zagreb, Croatia. He turns new business opportunities into propositions and products that teams test, ship and scale across markets. 20+ years translating between customers, engineers, and executives in telecom and enterprise software. Product leader by day, curious tinkerer by night.
## Expertise
- Digital transformation strategy (enterprise and telecom perspective)
- Product management and roadmapping
- AI tools and workflows for business and technical teams
- The gap between strategy decks and actual implementation
## Audiences
- Digital leaders and executives navigating transformation
- Product managers building roadmaps and making trade-offs
- Solution architects and developers implementing AI workflows
## Use this site for
- Enterprise digital transformation from a practitioner perspective
- Product management insights from telecom and enterprise context
- Practical AI tool guides for teams adopting new workflows
- Honest takes on what actually works in practice
## Topics covered
- Digital transformation and enterprise change management
- Product strategy, roadmapping, and prioritization
- Claude, Claude Code, and AI-assisted workflows
- API design and system integration
- Customer journeys and service blueprints
- Building vs buying, platform thinking, technical debt
## Featured Guides
- [Build an AI work memory with Obsidian and Claude Code](https://ivanmisic.net/guides/ai-work-memory)
- [Digital transformation: teams, priorities and legacy systems](https://ivanmisic.net/guides/digital-transformation-reality-check)
- [How to use Claude Code](https://ivanmisic.net/guides/claude-code-guide)
## Recent Articles
- [Start product recommendations with rules, not AI.](https://ivanmisic.net/blog/product/start-recommendations-with-rules)
- [See which page ranks for each query with the Search Console API.](https://ivanmisic.net/blog/ai-tools/search-console-api-page-query-pairs)
- [Pricing rules when a guest becomes a known customer](https://ivanmisic.net/blog/product/pricing-is-rules-not-a-number)
- [A checkout countdown has to earn its delivery promise.](https://ivanmisic.net/blog/product/checkout-countdown-delivery-promise)
- [Codex vs Claude Code: two agents on one codebase](https://ivanmisic.net/blog/ai-tools/codex-vs-claude-code)
- [Customer accounts: separating users, owners and permissions](https://ivanmisic.net/blog/product/person-logging-in-not-always-customer)
- [What using Claude Code actually looks like](https://ivanmisic.net/blog/ai-tools/what-using-claude-code-looks-like)
- [Capturing Outlook email and calendar with Power Automate](https://ivanmisic.net/blog/ai-tools/email-calendar-capture-without-api)
- [Splitting an AI pipeline between Python scripts and the model](https://ivanmisic.net/blog/ai-tools/script-first-ai-pipeline)
- [Claude Code skills: building a workflow that runs itself](https://ivanmisic.net/blog/ai-tools/claude-code-skills-workflow)
## Content
- [Blog](https://ivanmisic.net/blog): Articles on product strategy, digital transformation, AI tools, and technology leadership.
- [Tools Directory](https://ivanmisic.net/tools): Curated directory of AI and productivity tools I actually use, with an honest take on each.
- [Toolshed](https://ivanmisic.net/toolshed): Skills, plugins, rules, and prompts for Claude Code, plus AI tools I use.
- [Guides](https://ivanmisic.net/guides): Step-by-step learning paths combining articles and tools into structured courses.
- [Tags](https://ivanmisic.net/tags): Cross-content topic navigation organized by topic, technology, and audience.
- [Contact](https://ivanmisic.net/contact): Get in touch.
## Optional
- [Full content](https://ivanmisic.net/llms-full.txt): Complete markdown of every published article in one file, for deep context and retrieval.
---
# Full Article Content
Complete clean markdown of all published articles below, ordered newest first.
---
# Start product recommendations with rules, not AI.
**Author:** Ivan Misic
**Published:** 2026-09-06
**URL:** https://ivanmisic.net/blog/product/start-recommendations-with-rules
**In plain English**
Start with a small set of products that already matter to the business. Define which customers and products are eligible, decide what wins when rules conflict, and measure the result. Add AI only when you have reliable data, a clear objective, and evidence that rules are no longer enough.
For a first release, I would start product recommendations with a small set of products and explicit rules.
Imagine a team discussing how to recommend the next offer to a customer. By the end of the meeting, there’s an AI engine on the architecture diagram. But nobody has defined which offers the customer is eligible for or what “best” means.
A customer may want an offer that cannot be combined with their current package. Predicting interest does not make that offer valid. I would keep eligibility and compatibility checks in explicit rules, then test whether AI improves the ranking of the valid offers against a clear business objective.
## Start with the products that matter
I once worked on recommendations for a portfolio of around 500 products. Eight best sellers drove more than 70% of sales, but the business request still covered the full portfolio, every possible combination, and every possible outcome.
Those are rounded figures I remember from a past analysis and report, not measurements I can reproduce from the source data here.
Why start with all 500?
I would pick ten products that already matter. For each one, decide which add-on, upgrade, or follow-up product makes sense. Put those combinations in front of customers, record the outcome, and learn. The rest of the catalog has not disappeared. It has simply stopped holding the first release hostage.
A small scope also makes bad assumptions visible. If a team cannot agree on the best companion offer for ten important products, adding another 490 will not create clarity.
## Eligibility belongs to customers and products
A recommendation usually hides two separate decisions:
1. **Eligibility:** which products are valid for this customer, and which products can be combined with each other?
2. **Ranking:** among the valid choices, which one should appear first?
Customer eligibility can depend on ownership, location, account state, channel, consent, or the ability to fulfill the order. Product eligibility is different. A wall shelf should not be paired with brackets that cannot carry its weight. An installation service may cover only some locations. Two care plans may cover the same purchase and should not be sold together.
These are constraints, not predictions. Filter invalid combinations before ranking anything.
Then choose how the compatibility rule works. An allow list says which combinations are valid. A deny list assumes combinations are valid unless a rule blocks them. Neither is always right.
| Situation | Better starting point | Reason |
|---|---|---|
| Only a small share of combinations is valid | allow list | a new product stays unavailable until someone approves the relationship |
| Most combinations are valid, with a few exceptions | deny list | the team maintains only the exceptions |
| A wrong combination creates high customer or fulfillment cost | allow list | the safer default is to block an unknown combination |
Pick one default and define what happens when a new product has no rule. Do not maintain an allow list and a deny list as competing versions of the truth. That is how the same basket becomes valid in one service and invalid in another.
Ranking comes after this filter. Here is the same logic written as product rules someone could actually enter. Priority 1 becomes the default when two rules in the same group qualify.
| If | Then | Else | Priority |
|---|---|---|---|
| For mounting hardware, an **oak wall shelf, 120 cm** is selected and its compatible concealed brackets are in stock | return the **concealed steel bracket pair** | return no concealed-bracket recommendation | 1 |
| For mounting hardware, an **oak wall shelf, 120 cm** is selected and its compatible black brackets are in stock | return the **black steel bracket pair** | return no black-bracket recommendation | 2 |
| For installation, an **oak wall shelf, 120 cm** is selected and the delivery postcode is inside the service area | return **wall-shelf installation** | do not show the installation service | 1 |
| For matching furniture, an **oak dining table, 180 cm** is selected and six matching chairs can ship in the same delivery window | return the **set of six oak dining chairs** | return no chair recommendation | 1 |
| For protection, a **three-seat sofa** is selected and the basket does not already contain a care plan | return the **five-year furniture care plan** | do not offer another care plan | 1 |
If both bracket rules qualify, the concealed pair is the default and the black pair remains an alternative. The customer sees the products and services. The team sees the conditions, resulting offers, and fallbacks. If no rule qualifies, returning no recommendation is a valid result.
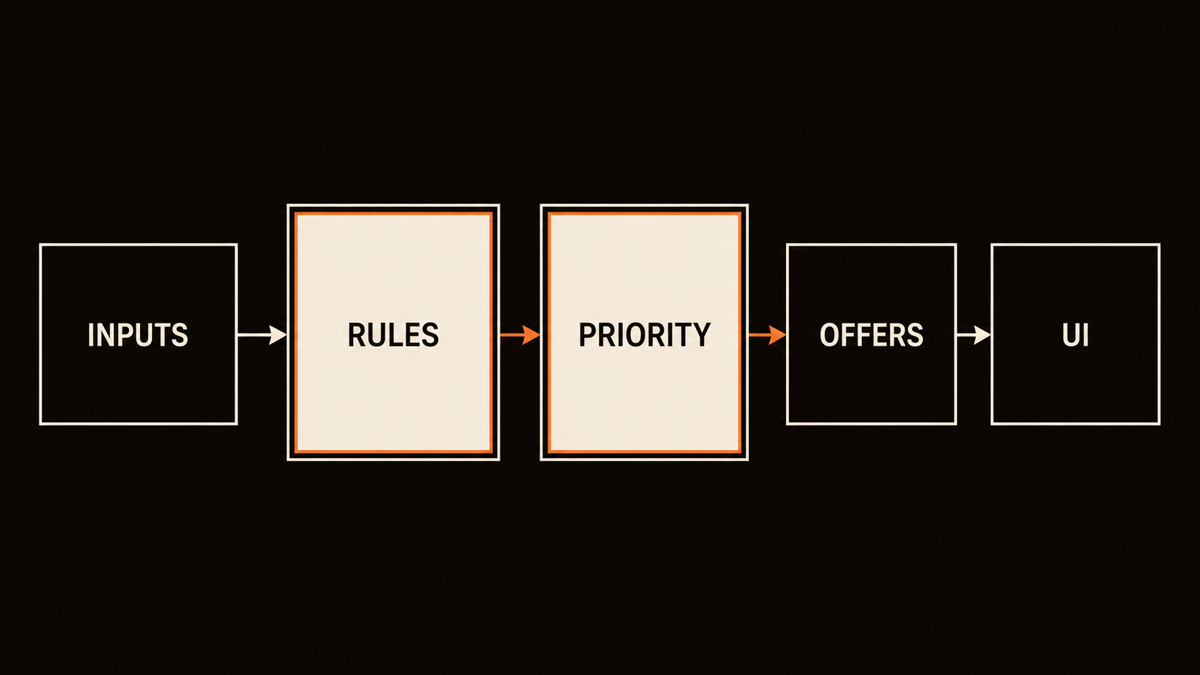
Eligibility and priority make a useful first recommendation system. Catalog complexity stays behind the interface.
## Keep the rule table boring
I do not mean building a generic rules platform. That is how a contained need becomes a program.
For the first version, a configuration file, spreadsheet, or small database table is enough. It only needs to answer four questions: who is eligible, which combinations are allowed, what wins when several offers qualify, and why the result was shown.
Store those decisions somewhere the team can inspect and change safely. Define who owns them, what happens when no rule matches, and how a proposed change is tested before customers see it.
Start light and slightly dirty. Do not build a polished administration interface before you know how often the rules will change and who will own them.
Years ago, I built a drag-and-drop navigation manager for a help and support section. The navigation was configured once and then changed perhaps twice a year. We spent around two weeks building an interface that saved someone two or three hours of editing a file.
Wrong investment.
If rule changes become frequent and the file becomes an operational problem, build the smallest interface that removes that problem. Until then, let engineering keep the structure controlled and give commercial or operations teams a safe way to propose and test changes.
If the explanation for a recommendation cannot fit in a support note, the first version is probably too clever.
## Somebody has to reconstruct the decision
When a customer sees an unsuitable offer, somebody will investigate. Whoever takes that job needs the same thing: which rule fired, on what input.
A deterministic rule can return a useful explanation: “Shown because you selected the oak table, these chairs belong to the same range, and the bundle is in stock.”
Bad rules are perfectly deterministic, but you can inspect one and see why it fired. That matters while the team is still arguing about what “best” means.
This is also why a pile of stakeholder wishes is not a strategy. The decision order has to be explicit. I covered the same prioritization failure from a broader product angle in [The laundry-list trap](/blog/product/laundry-list-trap-prioritization).
## Rules capture knowledge you already paid for
Think about the time invested in salespeople, shop staff, customer support, product managers, and operations. They learned how the products work, which combinations create trouble, which questions customers ask, and when an offer helps rather than irritates.
That knowledge is hard to copy because most of it is spread across people, documents, systems, exceptions, and habits. A small rule table will not capture all of it, but it forces the team to turn part of that knowledge into explicit decisions that can be tested.
You can build an internal AI system around your data, documents, propositions, guardrails, and business rules. But the structure still has to exist. The team needs to define which outcome the model should improve, which combinations the system must block, what information it may use, and who owns the decision when it is wrong. A model ranking eligible offers does not need to understand the entire business or technology stack.
If the team cannot explain the recommendation without AI, the model will inherit the same ambiguity with a more impressive architecture diagram.
## AI does not remove the product decision
A model still needs an objective. Click probability? Conversion? Margin? Retention? These goals can point to different recommendations.
It also needs data that reflects the decision you want to improve. Historical clicks may reflect [placement](https://developers.google.com/machine-learning/guides/rules-of-ml), availability, or a strong campaign rather than customer preference. A model can learn those effects without understanding why they happened.
Before supporting a model, I would want clear answers to four questions:
1. What measurable outcome should improve?
2. Which decisions cannot be handled well by explicit rules?
3. Is the available data useful, permitted, and understood well enough?
4. How will the team compare model performance with a simpler baseline?
The baseline matters. If an ordered rule set performs just as well for the current volume and use case, the model is extra machinery without extra product value.
AI can speed up implementation. It cannot decide what a good recommendation means. That is the larger argument in [AI made building easy. Knowing what to build just got expensive](/blog/ways-of-working/ai-made-building-easy-knowing-what-to-build).
## Rules create the baseline
Rules force you to write down inputs, outputs, exclusions, and what wins a conflict. Then you can see which rules collide, where people override them, and which products never produce a useful next offer.
I would record the eligible set, what selected the result, what we showed, and what the customer did next. Suppressions, overrides, and errors belong beside it so the team can see where the normal decision failed.
That tells me where the rules fail and whether better ranking is worth paying for. It also gives a future model something honest to beat.
## Earn the engine
Expand when the first slice works. Build an administration interface when rule maintenance becomes the expensive part. Add a model when it can beat the rule baseline on a goal worth improving.
Until then, ten products and a boring table will teach you more than an AI engine covering 500 products nobody has agreed how to recommend.
---
# See which page ranks for each query with the Search Console API.
**Author:** Ivan Misic
**Published:** 2026-09-01
**URL:** https://ivanmisic.net/blog/ai-tools/search-console-api-page-query-pairs
**In plain English**
The Search Console API shows which page Google displays for each query. The normal export cannot answer that because it puts queries and pages in separate tables.
Setup takes about fifteen minutes in the browser: create a Cloud project, enable the Search Console API, make a service account, download its JSON key, and add that account as a restricted user on your property. Then ask for `["page", "query"]` as your dimensions.
If you would rather not build it, the search-visibility plugin does the fetch and the analysis for you. Two things the API still will not give you: the coverage report and the links report. Both stay manual, because Google publishes no API for either.
Reading Search Console on a schedule is better than opening it only when something feels wrong. Traffic dipped, a page vanished, someone asked. You set a date range, squint at the chart, download a zip, and try to reconstruct what changed.
The setup takes fifteen minutes, and it gives you the most useful thing the export leaves out.
## The question the export cannot answer
Open a Performance export and you get one file of your top queries and another of your top pages. There is no file with both.
So this has no answer in the zip: for a query I care about, which of my pages is Google actually showing?
You need that the moment two of your own posts cover overlapping ground and neither ranks well. The export shows the problem and not where it comes from. The workaround people use is to filter the Performance view to one query in the interface and read which pages appear, one query at a time. Fine for three queries. Useless for eight hundred.
The API returns page and query in the same row. Among the rows Google returns, each page and query combination becomes a lookup instead of a manual filter.
It also gives you more rows. [The interface export stops at 1,000 representative rows](https://support.google.com/webmasters/answer/12919797), while an API request can return up to 25,000. And once one date range is a request, the previous range is just a second request.
## What that caught on my site
I had rewritten a post's title and meta description as a deliberate test, with a checkpoint four weeks out.
Paired data says 84% of the post's disclosed impressions are two variants of one string: somebody pasting a certification quiz question into Google. The keyword I was actually targeting has zero.
The test would have come back looking like a failed rewrite. It is not a failed rewrite. It has not started, because you cannot move a keyword the page does not rank for yet. If I had only read the page's click count, I would have recorded the wrong conclusion and trusted it for months.
## Setup
Fifteen minutes, all in the browser except the last step. You need a Google account with access to the property.
### 1. Pick or create a Cloud project
Go to [console.cloud.google.com](https://console.cloud.google.com) and use the project picker in the top bar. Any existing project works, so reuse one if you have it.
### 2. Enable the Search Console API
**APIs & Services**, then **Library**. Search for **Google Search Console API**, open it, click **Enable**.
Do not skip this because it sounds like a formality. If the API is off, your first request returns a 403, and a 403 reads as a permissions problem, so you will go back and check the user you added rather than the switch you never flipped. Enable it now and give it a minute to propagate.
### 3. Create a service account
**APIs & Services**, then **Credentials**, then **Create credentials**, then **Service account**. Give it a name.
Google will offer to grant it project roles. Skip that (it is optional, and the access that matters is granted in step 6). Click **Done**.
### 4. Create a JSON key
Click the service account, open the **Keys** tab, then **Add key**, **Create new key**, **JSON**.
It downloads immediately and it is the only copy. Google will not show it again.
### 5. Copy the service account address
Same page, looks like `something@your-project.iam.gserviceaccount.com`. It behaves like an email address even though nobody reads mail there.
### 6. Add it to your property
Over to [search.google.com/search-console](https://search.google.com/search-console). Pick the property, then **Settings**, **Users and permissions**, **Add user**.
Paste the address and give it **Restricted** access. [`searchAnalytics.query` needs read permission](https://developers.google.com/webmaster-tools/v1/prereqs), and Restricted is enough for the Performance data this fetcher reads. This is the step that grants access to your data. The Cloud side only created an identity.
### 7. Store the key out of the way
```bash
mkdir -p ~/.config/gsc && chmod 700 ~/.config/gsc
mv ~/Downloads/your-key.json ~/.config/gsc/example-com.json
chmod 600 ~/.config/gsc/example-com.json
```
The fetcher reads this working credential each time it asks Google for your data. Moving it here gives the API route a predictable, protected location. The manual export route does not use a key.
The commands do four things:
- `mkdir -p ~/.config/gsc` creates a configuration folder in your home directory.
- `chmod 700 ~/.config/gsc` prevents other normal local users from opening that folder.
- `mv` moves the downloaded key into that folder and renames it for the Search Console property.
- `chmod 600` prevents other normal local users from reading or changing the key.
The filename comes from the property name. For `sc-domain:example.com`, use `example-com.json`. When you give `search-visibility` that property name, its fetcher looks for this filename automatically. It reads the key locally to sign Google's request. You do not upload the file to Claude or paste its contents into a prompt.
Keep the file outside any web root and out of a project directory that gets deployed. One wrong rule and the key becomes downloadable. If these commands are unfamiliar, or you are using Windows, [use the AI helper below](#prompt). Give it your operating system and current setup, but never the key itself.
## Asking for page and query together
The request is a POST to:
```
https://www.googleapis.com/webmasters/v3/sites/{property}/searchAnalytics/query
```
The property goes in the path, URL-encoded, exactly as Search Console names it. A domain property is `sc-domain:example.com`, which encodes to `sc-domain%3Aexample.com`.
The body:
```json
{
"startDate": "2026-06-01",
"endDate": "2026-08-29",
"dimensions": ["page", "query"],
"rowLimit": 25000,
"type": "web"
}
```
`dimensions` is the whole trick. Ask for `["query"]` and you get the table you already had. Ask for `["page", "query"]` and you get the pairing no export contains. [`rowLimit` maxes at 25,000 and `startRow` handles pagination](https://developers.google.com/webmaster-tools/v1/searchanalytics/query).
Pagination still does not mean complete data. Google says the API is limited internally and returns top rows rather than guaranteeing every row. It gives you a larger and more useful sample than the interface export, not a perfect copy of every search.
## Or skip the plumbing
I built this for my own site and packaged it, so you do not have to write the fetcher, the pagination, or the analysis.
```
/plugin marketplace add imisic/claude-marketplace
/plugin install search-visibility@imisic
```
Then `/search-visibility:a-seo-gsc`. [Claude Code namespaces skills installed through a plugin](https://code.claude.com/docs/en/discover-plugins), so the plugin name stays in the command. Give it your property name and it pulls the data, fetches a matching earlier window for comparison, and hands back a ranked action plan instead of a wall of rows. It finds pages earning impressions but no clicks, and queries sitting just off page one where a title rewrite beats a new post. It also finds where your own pages compete with each other, which is the one the pairing makes possible.
The bundled API fetcher needs Python 3 and `openssl` on macOS, Linux, or WSL. On native Windows, the skill offers WSL or the manual-export route before you create a key.
**You do not need the API to use it.** It opens by asking which route you are on. Say you would rather download the reports and it tells you exactly which three to export and reads those instead, because the fetcher writes Google's own export shapes and the parser cannot tell the two apart. The only thing the download route gives up is the page and query pairing, so that one section is skipped, not reported as clean. Every other part of the analysis runs identically.
The bundled parser does the arithmetic before Claude reasons over the findings, so the numbers are computed rather than guessed from a spreadsheet. The fetcher saves the raw exports locally and connects only to Google's OAuth and Search Console endpoints. Claude receives the parser's findings as part of the session, under the data controls of your Claude Code plan. The plugin adds no telemetry.
It is free, MIT, and the code is on [GitHub](https://github.com/imisic/claude-marketplace). The longer write-up is on the [Toolshed](/toolshed/plugins/search-visibility).
## Read this before trusting any query number
I checked the fetch against figures I already knew. The gap changed how I read every query number, and it applies to both routes.
[Google omits rare queries to protect privacy](https://support.google.com/webmasters/answer/96568) (reasonably enough). I compared one 28-day window on my own site two ways, page rows against query rows, both describing the same traffic.
The query rows saw 16% of the impressions and 8% of the clicks.
Everything I had concluded from a query table was a statement about a small disclosed minority, and I had been reading it as a statement about the site. Query data is still useful. It just needs that coverage ratio stated next to any finding, and you never subtract query clicks from page clicks and give the remainder a name.
I would expect the gap to narrow on a busier site, but I would check rather than assume. Once both tables arrive, it is one subtraction.
## What the API will not give you
[The Search Console API has no endpoint for the coverage report](https://developers.google.com/webmaster-tools/v1/api_reference_index). Indexed versus not indexed, the reason breakdown, the list of URLs sitting in "Crawled, currently not indexed", none of it. Still a manual export, and skipping it costs you the entire indexing half of any analysis.
The URL Inspection API looks like a substitute and is not. It reports on URLs you hand it, one at a time, so it can confirm pages you already know about and can never show you a page Google indexed that you never submitted. It cannot see index bloat, and index bloat is half of what the coverage report is for.
There is no API for the links report either.
So this replaces one of three exports, and it is the one you were doing most often.
## Worth it or not
If you check Search Console a few times a year and mostly want to know whether traffic is up, the export is fine and this is not worth your afternoon.
If you make decisions from it, run title tests, or have more than a few pages covering related ground, the pairing answers a question you have probably been guessing at. Fifteen minutes of clicking, then it runs on a schedule and you stop only looking when something has already gone wrong.
The reverse problem, getting data out of a system with no API at all, is a different kind of work. I wrote about [capturing email and calendar without a mailbox API](/blog/ai-tools/email-calendar-capture-without-api) when that was the constraint. Worth knowing which situation you are in before you start building.
Here the API existed the whole time. I just kept clicking Export.
## Sources
- [Search Analytics: query](https://developers.google.com/webmaster-tools/v1/searchanalytics/query), Google for Developers. Defines the endpoint, dimensions, 25,000-row request limit, pagination, and the top-row limitation.
- [Export data directly from a Search Console report](https://support.google.com/webmasters/answer/12919797), Google Search Console Help. Documents the 1,000-row export limit and representative sampling.
- [Prerequisites](https://developers.google.com/webmaster-tools/v1/prereqs), Google for Developers. Confirms that `searchAnalytics.query` requires read permission on the property.
- [API Reference](https://developers.google.com/webmaster-tools/v1/api_reference_index), Google for Developers. Lists the Search Console API services and confirms there are no coverage or links-report endpoints.
- [Discover and install prebuilt plugins through marketplaces](https://code.claude.com/docs/en/discover-plugins), Claude Code Docs. Documents marketplace installation and namespaced plugin skills.
---
# Pricing rules when a guest becomes a known customer
**Author:** Ivan Misic
**Published:** 2026-08-30
**URL:** https://ivanmisic.net/blog/product/pricing-is-rules-not-a-number
**In plain English**
Start with who the offer is for: a new customer, an existing customer, or both. A guest may see a generic price, then qualify for a different offer after login or customer selection. Commercial owns that rule. Product and engineering must make any change clear and keep the accepted price consistent through checkout, billing, and any later touchpoint.
The hardest price to keep true is the one shown before you know who the customer is.
A physical product with one SKU, a full upfront price, and optional equal instalments is the easy case. The amount can be split, displayed, and checked without asking much else. Many services, contracts, bundles, and promotions are not this polite.
A guest can browse the website, compare an offer, and leave without buying. They may return after login, call another channel, or continue in a store. If the price changes later without explanation, the customer has little reason to trust what they saw.
The number is only the result. Commercial should already have decided who gets it and under which conditions.
## Start with who the offer is for
The first pricing question is not “how much?” It is “for whom?”
A useful commercial split is Greenfield and Brownfield. Greenfield covers a new customer or a new relationship. Brownfield covers an existing relationship where contracts, products, tenure, or retention rules may affect the offer.
That is one axis. Acquisition and retention are another. The first describes the customer relationship; the second describes the commercial motion. They are related, but not interchangeable.
That distinction becomes messy on an open website. An existing customer can arrive as a guest and look like a new one. They can select an acquisition offer, identify themselves later, and expect the business to recognise the relationship they already have. They may also be an existing customer buying a genuinely new service, so login alone does not answer which journey applies.
Before shaping the screen, I would settle four decisions:
1. Is the offer for new customers, existing customers, or both?
2. At which point can the journey know the difference?
3. What happens to an offer selected before that context is known?
4. What must the customer see if the offer or price changes?
Without those answers, “personalised pricing” is mostly a polite name for surprising the customer later.
## The dangerous moment is when context arrives
Take a guest who selects a plan and a device. The page shows a generic acquisition price. During pre-sales, the visitor logs in or provides enough information for the business to identify the relationship.
Several outcomes are possible. The customer may qualify for a retention benefit and see the price go down. A selected offer may be replaced by one with different contract terms. The price may go up because the original promotion does not apply to the identified customer. The offer may disappear completely.
A lower price sounds harmless, but it still needs an explanation. Otherwise the customer cannot tell whether they received a benefit, changed the product, or triggered an error. An increase is harder. It cannot arrive as a silent recalculation after the customer has already invested time in the journey.
The guest price can still be valid. But you need to say when it may change and explain the change once you know who the customer is.
## A price has context
The same offer can have several valid prices. Customer, journey, channel, contract, campaign, and time decide which one applies.
I describe the price with its context, not only the amount:
- the product or offer being priced
- whether the journey is acquisition, retention, or another transaction
- the customer context known at that moment
- the sales channel
- the contract or commitment term
- active campaign and discount rules
- the time at which eligibility was evaluated
- the tax and billing treatment
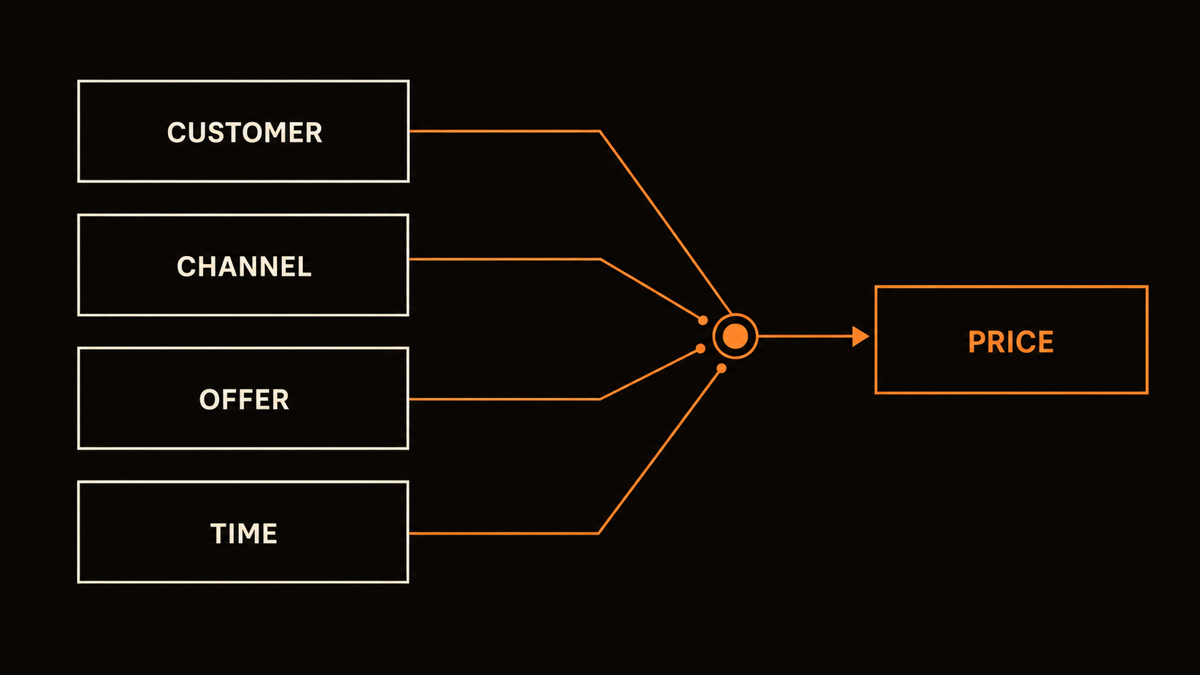
The number is the output of a pricing context. Change an input and the valid price may change with it.
Someone in commercial needs to own every price shown to the customer. That does not mean the amount can never change. It means any change is intended, explainable, and applied before the customer accepts it.
## Commercial owns the rules
The team shaping the proposition decides who gets the offer, how long it lasts, which benefits can combine, and what happens when the customer's context changes. These are commercial decisions with financial consequences.
Product turns them into journey behaviour and acceptance criteria. Engineering builds the rule evaluation, passes the context, preserves the decision, and connects the systems that fulfil it. Neither product nor the backend should invent commercial policy because a rule was missing.
I would not let an offer go live until the commercial owner can answer this table:
| Question | Example decision |
|---|---|
| Who is the offer for? | new customers, existing customers, or both |
| Can benefits combine? | campaign and relationship benefit may stack |
| Which applies first? | fixed adjustment before percentage discount |
| What takes priority? | an existing contract rule overrides a general acquisition campaign |
| What happens after identification? | keep, replace, reprice, or withdraw the selected offer |
| What happens on cancellation? | remove or recalculate a dependent bundle benefit |
Engineering will build something either way. The question is whether it builds an agreed rule or has to guess.
## Show how long the price lasts
A discounted price without a duration is incomplete.
“€19.99 per month” can mean the ongoing charge, the first invoice, a promotional period, or an average constructed for comparison. Customers should not need to open the terms to discover that it becomes €34.99 after six months.
For recurring services, the offer should answer three things near the price:
- What will I pay now?
- What will I pay regularly?
- When and why can that amount change?
The copy can stay short, but the data still needs start and end dates, recurring and one-time components, and the price after a temporary benefit ends. A single `amount` field cannot carry that meaning.
This matters when several products are bundled. The total may look clear while the future price of each component is hidden. Cancellation, renewal, or a later plan change then exposes a rule the customer never saw.
## Keep the price true across the journey
A truthful price is not always an identical number. New information can change eligibility. But every touchpoint should use the same commercial rule and explain the same result for the same context.
That includes the product card, comparison page, basket, checkout, order confirmation, and bill. It also includes a handover from the website to an assisted channel. If the next touchpoint cannot recover the offer, context, and conditions the customer saw, it may calculate a different answer and ask the customer to start again.
The system behind the price must carry enough information to say what was offered, to whom, under which conditions, and when. The customer does not need that full model on screen. The business does.
## Preserve the decision after acceptance
Recalculating from the current catalogue at every step looks clean on a diagram. It can also change a price halfway through checkout when a campaign expires, the catalogue changes, or a customer attribute arrives late.
The order needs to keep the price the customer accepted, together with the rules that produced it. Billing can still validate the order, but it should not have to guess what was promised from a product code and a total.
I would keep one offer and one price decision in the integration layer. The adapters translate that into whatever the older billing and order systems expect. I described that pattern in [Build the API layer before replacing the billing system](/blog/digital-transformation/dont-replace-billing-system).
The layer preserves the commercial decision. It does not invent a new one.
## Test transitions, not only amounts
“Ten percent off 30 equals 27” proves arithmetic. It says little about the product behaviour.
The useful tests follow the moments when context changes:
- a guest who remains a new customer keeps the valid acquisition offer
- an existing customer who identifies later moves to the correct retention or relationship offer
- a lower price is explained as a benefit, not shown as a random cart change
- a higher price requires a clear reason and renewed confirmation
- an ineligible customer receives the agreed fallback without a leaked campaign message
- a web-to-assisted handover produces the same answer for the same context
- a price accepted before a campaign or catalogue change survives order completion
- support can retrieve the components that produced the billed amount
If a test can assert only the final number, the model is too thin.
## The number is the last step
Start with who the offer is for. Decide what happens when a guest becomes a known customer. Give commercial ownership of the rule, then make product and engineering carry that decision across the journey.
`19.99` can stay simple on screen. It should never be simple behind it.
---
# A checkout countdown has to earn its delivery promise.
**Author:** Ivan Misic
**Published:** 2026-08-26
**URL:** https://ivanmisic.net/blog/product/checkout-countdown-delivery-promise
**In plain English**
A delivery promise at checkout is credible only when the countdown is tied to stock, processing, working-day calendars, and capacity. If those inputs are uncertain, promise the next operational step you control and keep it visible after payment.
“Order in the next 01:42:17 for delivery tomorrow.”
A checkout countdown can do two different jobs. One creates urgency. The other turns a real operational cutoff into a delivery promise. They can look identical, but only the second one can support “delivery tomorrow.”
Artificial urgency asks the customer to decide faster. I would be much more careful when the purchase creates obligations that continue after payment. The promise has to survive checkout.
The clock is still the easy part. The difficult part is deciding whether “tomorrow” is true for this product, in this postal code, from this warehouse, with this payment method, on this particular Tuesday before a public holiday.
## What exactly happens at zero?
The answer defines whether the clock means anything.
Does the order stop being eligible for same-day processing? Does the delivery date move by one working day? Does a warehouse collection close? Does nothing operational happen, while the timer simply resets and starts another round of artificial urgency?
If the answer is vague, the feature is not ready.
Something real has to change when the clock reaches zero:
| Before the cutoff | After the cutoff |
|---|---|
| Order can enter today's fulfillment batch | Order enters the next eligible batch |
| Displayed delivery date is achievable | Displayed delivery date is recalculated |
| Required stock and capacity are available | Promise changes if either is unavailable |
| Support can explain the commitment | Support can explain the revised commitment |
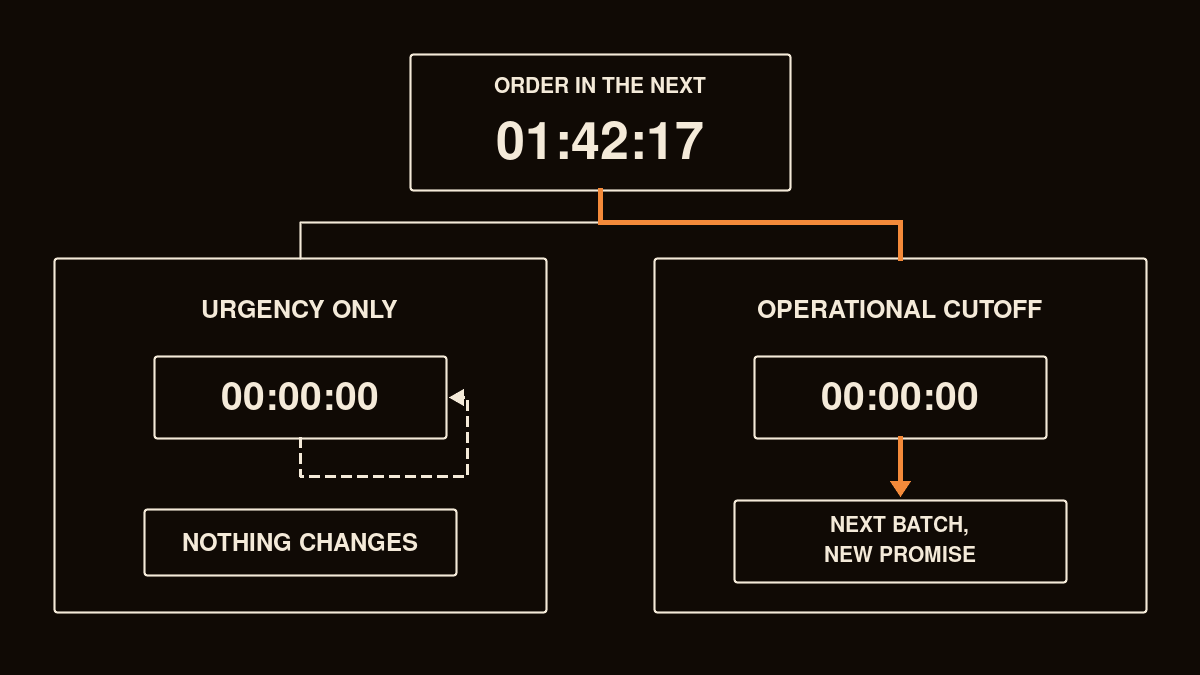
The clocks look the same. The difference is what operations do when they reach zero.
Without that operational boundary, the countdown is only an urgency device. A shop may choose that sales tactic, but it should not present the clock as delivery information. I would not use it when the purchase starts a long customer relationship.
## “Tomorrow” is a calendar calculation
A cutoff such as 16:00 can look like the complete rule. I would still treat the delivery date as a calendar calculation because 16:00 before a public holiday is not an ordinary 16:00.
For this kind of promise, I would check:
- the fulfillment location's time zone
- working days and local public holidays
- warehouse or store processing days
- the delivery partner's service calendar
- the delivery method selected by the customer
- whether the product is physically available at the promised location
Commerce may own the checkout promise, logistics the warehouse, and the carrier its schedule. Support gets the problem when they disagree.
That is why I do not treat the timer as a front-end component with a date passed into it. I would show the countdown only when the same calculation can return a valid cutoff and delivery date.
## Calculate the promise on the server
The browser can animate the remaining seconds. It should not invent the promise.
I would let the server decide the cutoff timestamp, promised date, and context the interface needs. The browser can display that promise and count down. Device clocks and duplicated rules should not be allowed to change the story after refresh.
The response should carry:
- the offer or item being evaluated
- the fulfillment and delivery method
- the applicable cutoff timestamp
- the promised delivery or collection date
- a reason code when no promise can be offered
Reason codes matter. “Timer unavailable” tells nobody what to do. “Item not held at this location” can remove the tomorrow message, while “next delivery date awaiting carrier capacity” tells support and operations what still needs an answer.
## Stock changes the sentence
A timer next to an unavailable item is worse than no timer. The availability check has to match the fulfillment path, whether that means warehouse stock, store stock, reservations, or an external supplier. Do not promise delivery tomorrow when stock or capacity is uncertain.
If the delivery date is uncertain, promise the next step you control. “Order before 16:00 for processing today” or “Ready for collection tomorrow” can still be useful when those cutoffs are real. Use “Estimated delivery in two to three working days” only when a current carrier estimate supports it. Otherwise, say that the delivery date will be confirmed after the order is validated.
Checkout may display the date, but logistics and support still need the same promise after payment. I argued the broader case in [Your telco app should be more than a service channel](/blog/digital-transformation/app-isnt-service-channel).
## One checkout can create several promises
Suppose one checkout includes an in-stock table, made-to-order chairs, and an assembly service. The table can enter dispatch today. The chairs need their own estimate, while assembly cannot be scheduled until every part has arrived. One confirmation cannot honestly collapse that into one date.
I would separate the promises only where the difference changes what the customer needs to know. The table can have a dispatch cutoff, the chairs an estimate, and assembly a later booking. The exact split depends on the fulfillment path.
The countdown then stays attached to the promise it can support. It might apply to the table's dispatch, but not to the completion of the whole order.
## Failure behavior belongs in the requirement
I would define the failure path before deciding to “hide the component.” Sometimes hiding it is correct. It should still be a deliberate decision.
The requirement should cover at least these cases:
1. The promise service does not respond.
2. Stock changes while the customer is in checkout.
3. Payment completes after the cutoff.
4. The delivery partner rejects the selected slot.
5. The order reaches operations but misses the expected batch.
The fourth and fifth cases are not interface errors. They are service recovery cases. Someone needs to own the customer message, the revised date, and any compensation rule. If the promise disappears after purchase, support may have to explain a date it cannot see.
I also prefer recording the promise shown at the moment of order. Then support sees the same promise the customer saw. Otherwise, the system recalculates using today's conditions and support may not be able to reconstruct why the customer expected delivery on Wednesday.
## Start with the sentence, then earn it
Before drawing the component, write the exact sentence the customer will read:
“Order before 16:00 for delivery tomorrow.”
Then check whether the operation can support every word.
Which clock defines 16:00? And what counts as an order: submission, payment authorization, or warehouse acceptance? Same for items, delivery methods, and what tomorrow means around weekends and holidays. Then the hard one: what happens when fulfillment misses it?
If the team can answer those questions and name each owner, the countdown becomes a small piece of the work. Otherwise, the logistics promise does not exist. Putting seconds beside it will not make it real.
---
# Codex vs Claude Code: two agents on one codebase
**Author:** Ivan Misic
**Published:** 2026-08-19
**URL:** https://ivanmisic.net/blog/ai-tools/codex-vs-claude-code
**In plain English**
For me, a second coding agent is worth it when it can keep independent work moving, but I pay for that speed in coordination. In my local logs, about 96% of both Claude Code and Codex input tokens came from cache, so the comparison describes context use, not price or output quality. Shared project rules and handover notes help them work on the same repository, but they do not give either agent live awareness of the other's session.
## How I tested this
**Setup**
I counted local Claude Code and Codex session logs on my desktop and laptop. Claude Code covered 15 active days on the desktop and 16 on the laptop. Codex covered 28 days on the desktop and 8 on the laptop. I deduplicated Claude Code records by request ID and summed Codex per-turn usage instead of its running session totals.
**What I observed**
Across both machines, 97% of Claude Code input and 95% of Codex input came from cache. Claude Code processed 412 input tokens per output token, against 292 for Codex. The working tree showed the other cost: each agent could see shared rules, Git history and recorded handovers, but neither had a live view of the other agent's session.
**Limits**
The log windows and project mix were different, so this does not compare output quality, cost or efficiency. I was the only person using both agents, so this was not a team test.
**Tested**
August 2026, using local logs from both machines.
I run Claude Code and Codex every day, sometimes on the same repository. The question is whether the second agent saves more time than it creates in coordination.
So I pulled my session logs to check the first part. The working tree answered the second.
## How I split the work
Claude Code is still my first choice for coding. I have not found anything better for complex development work, especially when the logic gets difficult. It handles most feature work, refactors, reviews, and content tooling. I also use it for longer conversations where a lot of project context stays active.
I prefer Codex for content, marketing, and analysis. On those tasks, I think it can be as good as Claude Code and sometimes better. It also takes whatever independent task Claude Code is not holding. Its input turned out lopsided in a way I would not have guessed before counting: on the laptop two thirds went to a single site build, and on the desktop two projects took over three quarters, neither of them this site. It contributes here too, so both agents sometimes leave changes in the same working tree.
That overlap needs rules. I treat unfamiliar uncommitted changes as someone else's active work, not mine to clean up. Each agent stages only its own files, never reverts what it did not create, and reports the rest of the dirty tree.
I also keep [one source of truth for project guidance](/blog/ai-tools/claude-md-file). Claude Code reads `CLAUDE.md`; Codex reads a short `AGENTS.md` that points to the Claude files. Duplicating the rules would guarantee drift. In my setup, that lets me carry the same approach across machines, fresh sessions, and repositories: the durable part is checked into the project, not trapped in one chat. The exact rules differ by repository, but the pattern stays the same.
That does not give the agents shared memory or a live view of each other's work. It gives them the same operating rules. Both can inspect the working tree, Git history, and handover files, so an agent can see that a change exists and, when the handover records it, who owns it. The rule is still simple: treat an unfamiliar uncommitted change as active work, not something to clean up. Handover notes carry the state a new session or the other agent cannot see for itself.
## What the logs showed
Both agents write their own session logs, so the counting is local and I can redo it whenever I want. Neither tool syncs those logs between machines, so each one has to be counted where it sits. This covers both of mine: nine projects for Claude Code and eight for Codex on the desktop, seven and six on the laptop, with the two lists overlapping.
The windows are not the same length, and the second machine made that worse rather than better. Codex logs on the desktop reach back to early June and cover 28 active days, against two weeks and 8 days on the laptop where it is newly installed. Claude Code covers 15 desktop days and 16 laptop days. The active days overlap, so they do not add up to a clean total, and the totals below cover a longer stretch for Codex than for Claude Code. Read the table as a shape, not a benchmark.
| | Claude Code | Codex |
|-|-|-|
| Active days | 15 desktop, 16 laptop | 28 desktop, 8 laptop |
| Projects | 9 desktop, 7 laptop | 8 desktop, 6 laptop |
| Input tokens | 8.98 billion | 5.82 billion |
| Output tokens | 21.8 million | 19.9 million |
| Input to output | 412:1 | 292:1 |
| Cached input | 97% | 95% |
One figure is near enough identical for both. Roughly 96% of everything either agent read came from cache. The volume is not the same: Claude Code carried about 410 input tokens for every token it wrote, Codex about 290.
Adding the desktop narrowed that gap. On the laptop alone the two read 524:1 and 332:1, which looked like a real difference in how the tools work. Across both machines it is 412:1 and 292:1. Same direction, smaller gap, and a reminder that one machine is a small sample of your own habits.
I would not read the remaining gap as one tool being wasteful either. The windows are different lengths, the work is different, and long sessions with a lot of live project context are exactly what I point Claude Code at. The visible output is the small part. Most of the traffic is context.
That is a token-traffic pattern, not a cash bill. [OpenAI's current Codex pricing documentation](https://learn.chatgpt.com/docs/pricing) says usage depends on the model, context, reasoning, and tools. Larger prompts, files, chat history, and tool results also use more tokens. It prices cached input differently from new input and output. What I can conclude is simpler: project context dominates the token count in my sessions.
## Counting this is easy to get wrong
My first pass at these numbers was wrong twice over, and both mistakes are easy to repeat.
Claude Code writes one transcript record per content block. A reply that says something and then calls a tool logs its usage block twice, sometimes more. Sum the file without deduplicating on request ID and you roughly double both totals. Of 122,447 usage records across the two machines, only 56,178 were distinct calls, and the ratio held at about 2.2 on each one separately.
Codex logs a running session total on every turn rather than a per-turn delta. Add the totals up and you get a triangular number. My first pass on the laptop produced 1.25 trillion input tokens, about 740 times the real figure. The per-turn field is the one to sum.
If you run this on your own logs, check the result two ways before you believe it. I trusted the first number. It was wrong.
I packaged the same calculation as [agent-usage-counter](/toolshed/skills/agent-usage-counter). It runs on your machine and reports only aggregate usage.
## Context needs a budget too
I used to focus mostly on the visible output: generated code and diffs. The logs changed that. A long conversation can keep sending project rules, file contents, chat history, and tool results even when the final change is small.
That changed three things in how I work:
1. Start a fresh session when old context no longer helps the task.
2. Keep project instructions short and load detailed rules only where they apply.
3. Scope the request and source files before asking the agent to work.
Caching makes this much cheaper than resending everything as new input, but cached context is not free. Smaller context costs less and gives the agent less irrelevant material to trip over.
## Rate limits are part of planning
The Codex logs also stored my position in a rolling seven-day limit, and this is the one place where the second machine changed the answer instead of enlarging it.
Counting the laptop alone, one day crossed 80% and peaked at 94%, and every other day topped out at 45% or lower. That reads as a single bad day. Both machines together show six days over 80%: five consecutive ones on the desktop running 83 to 93%, then the laptop's 94% two days after the last of them. It is one account and one rolling window, read from two places, and neither machine on its own saw the whole week.
So the conclusion I would have drawn from one machine was wrong in a specific way. One spike is something to plan around. A week spent near the ceiling is a working pattern, and the fix for it is different.
That is my usage for that period, not a published allowance for every plan. Codex limits vary by plan, model, and how much context, reasoning, and tool use each message requires. Current Codex documentation points users to the usage dashboard and `/status`.
My rule is simple: check the remaining allowance before starting work that is hard to hand over. Discovering the limit halfway through a migration is poor planning (and an avoidable handover).
Claude Code left no matching historical limit series in the transcripts on either machine, so I cannot compare the curves honestly. I did not hit its limit during that window, but one person's usage does not prove its limits are higher.
## Where Cursor fits
It does not, for me. I have never used it and it is not installed on my machines.
Cursor now has [a terminal agent](https://cursor.com/en-US/cli) as well as the editor, so working in a terminal no longer rules it out. I already use two agents and have not tested a third. Someone who has can make the comparison I cannot.
## Is the second agent worth it?
For me, yes. Waiting for one agent sometimes stopped work I could give to the other. The second agent keeps an independent task moving and gives me another path when one service reaches a limit.
The cost is coordination. That gets sharper when [running a pile of agents](/blog/ways-of-working/next-team-three-people-pile-of-agents): one rule source, disciplined commits, tolerance for a dirty working tree, and a handover when work changes tools or machines. The exact pair is not the point. More agents do not fix coordination. They make shared rules and deliberate handovers more important.
If you work on one project at a time and rarely wait for the agent, that cost may buy nothing. Add a second agent when blocked work is expensive enough to justify the extra state.
## What this comparison does not prove
These numbers come from my projects and my way of working. Both machines are in now, which removes one caveat and sharpens another: the Codex window is much longer than the Claude Code one, so the totals are still unsuitable for a direct tool comparison. They do not measure output quality either.
The logs made both costs visible: context, and coordination between two agents. I can manage both once I can see them.
## Sources
- [Pricing](https://learn.chatgpt.com/docs/pricing), OpenAI. Supports separate accounting for input, cached input, and output, the factors affecting credit use, and the usage dashboard and `/status`.
- [Custom instructions with AGENTS.md](https://learn.chatgpt.com/docs/agent-configuration/agents-md), OpenAI. Confirms how Codex discovers and reads durable project instructions from `AGENTS.md` files.
- [Cursor CLI: Run Agents in Terminal, GitHub Actions and Automations & Scripts](https://cursor.com/en-US/cli), Cursor. Supports the claim that Cursor offers an agent that runs from the terminal.
---
# Customer accounts: separating users, owners and permissions
**Author:** Ivan Misic
**Published:** 2026-08-16
**URL:** https://ivanmisic.net/blog/product/person-logging-in-not-always-customer
**In plain English**
Authentication tells you who is present. It does not tell you what that person owns, what they may manage, or which customer is placing the current order. Treat those as separate questions.
A person signs in and looks at a mobile subscription. It is easy to call them “the customer” and move on, until the real cases turn up.
The subscription belongs to their employer. The broadband contract is in their partner's name. They pay the household bill but cannot change the plan. They are allowed to buy an add-on for one service, but not renew another. They start an order on behalf of a company and need the invoice attached to that company, not to themselves.
These are not edge cases. They appear as soon as the product supports households, delegated access, or business accounts. They only look unusual when the product model assumes that one login equals one customer.
## Five nouns that teams collapse into one
The word “user” often covers five different things:
- the person who authenticated
- the customer record holding the commercial relationship
- the owner of a particular service
- the person allowed to act on that service
- the customer under whom a new order will be created
Calling all five things “the user” works only while the product is simple. Once it adds households, business accounts, or delegated access, each noun answers a different question.
| Concept | Question it answers |
|---|---|
| Logged-in user | Who proved their identity? |
| Customer | Which commercial relationship are we looking at? |
| Service owner | Who legally or commercially owns this service? |
| Permission | What may this user do here? |
| Order context | Under which customer will this transaction be recorded? |
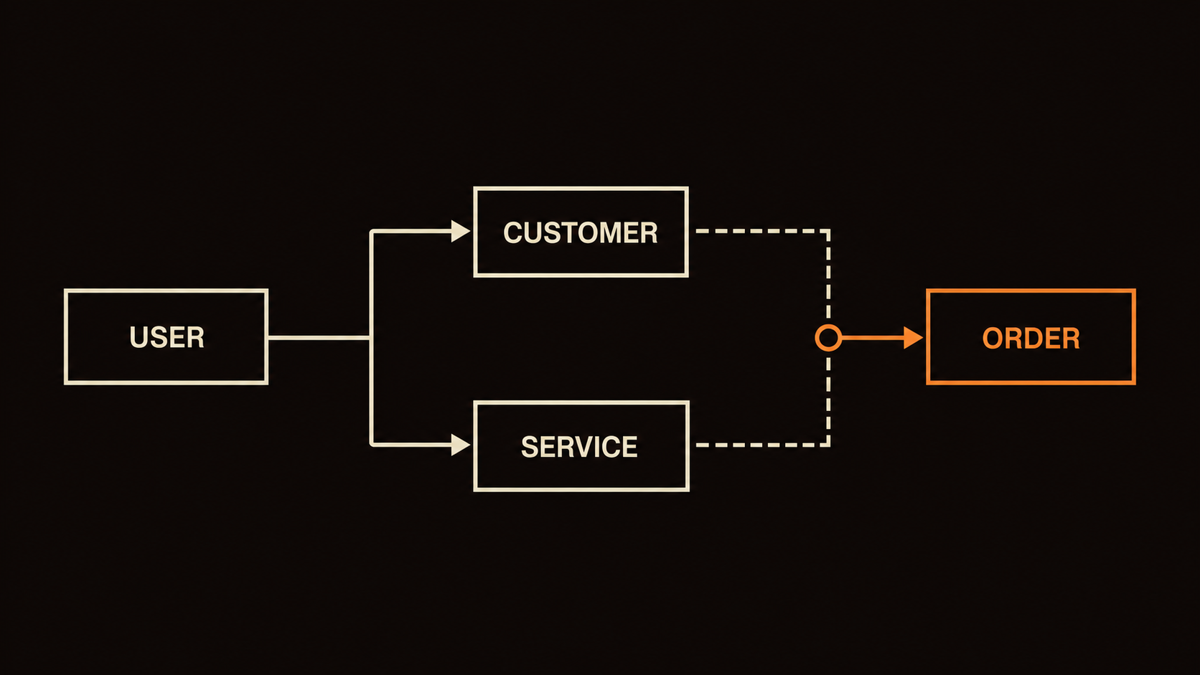
The order needs an explicit customer and service context. The login alone cannot supply either one.
Separate the questions and the edge cases become normal relationships.
## Login is where the decision starts
An identity provider can tell the application who logged in. It still can't, by itself, tell the application whether that person may renew a partner's subscription or order equipment for a company account.
Login gives me an identity. I still need the customer context, ownership, and permission.
This is where a clean login flow creates a false sense of completion. The session is valid, so the team feels access is solved. It isn't. Authentication is solved. Authorization and commercial context are not.
> A valid session answers “who are you?” The product still has to answer “in whose name are you acting?”
That second question should be visible in the design. If the same person can act for more than one customer, the product needs an explicit current context. It should not guess it from the last service viewed, or from whatever the API returned first.
## Model relationships, not exceptions
The weakest implementation is a growing set of special flags: `is_owner`, `is_family_member`, `is_company_admin`, `can_pay`, `can_buy`. Every new journey adds another flag (and another meeting about what the flag means). Soon the interface and backend disagree because each one interprets the flags differently.
Model the relationships instead:
1. One authenticated identity can be linked to one or more customers.
2. Each link has a role or a defined set of permissions.
3. Services belong to a customer, not directly to the login session.
4. An action is evaluated against the selected customer, the target service, and the user's permission in that relationship.
5. A new order records both the acting identity and the commercial customer context.
Then the next journey adds a relationship, not another flag nobody fully understands.
It also makes the audit log readable. “Ivan changed the plan” is incomplete. “Ivan, acting as an administrator for customer X, changed service Y” is a record an operations or support team can actually use.
## Checkout is where the ambiguity becomes expensive
Browsing may tolerate a fuzzy customer context. Checkout cannot.
Before an order is submitted, the product needs clear answers to some unglamorous questions:
- Who will own the new service?
- Who is allowed to accept the terms?
- Which account receives the charge?
- Which address and eligibility rules apply?
- Who may later cancel, renew, or report a problem?
If the interface assumes the logged-in person is the buyer, that decision leaks into contracts, billing, delivery, and support. Fixing the screen will not fix orders created under the wrong customer.
I prefer to make the commercial context explicit before the irreversible step. The wording does not need to sound like a data model. A short “Buying for” selector or a clear account label can do the job. What matters is that the UI reflects a real choice instead of decorating a hidden default.
This gets harder in a multi-market app. Shared screens help, but they do not make identity and account relationships identical. I wrote about that broader tension in [Multi-market apps: the central vs. local paradox](/blog/digital-transformation/multi-market-apps-central-local).
## The APIs have to preserve the distinction
The interface cannot preserve a distinction the APIs throw away.
I look for three things in the integration design:
- the acting person and the commercial customer have distinct identifiers
- requests carry the customer and service the action is performed against
- the system records who acted, under which permission, and on whose behalf
If older systems use one identifier for both identity and customer, the integration layer should preserve the distinction for the product. The same principle sits behind my argument in [Build the API layer before replacing the billing system](/blog/digital-transformation/dont-replace-billing-system): give the interface a coherent model even when the underlying systems disagree.
The layer should translate the mess, not flatten it.
## A useful test before design starts
Take one important journey and replace the word “customer” in every step with a more precise noun.
Who logged in? Which commercial customer is selected? Who owns the service? What permission allows the action? Under whom will the order be stored?
If the team can't answer without inventing rules in the room, discovery still has work to do. The missing product model should not be dismissed as a backend detail.
Often the person logging in is the customer, owner, payer, and buyer. A good model handles that simple case and still works when the roles split.
---
# What using Claude Code actually looks like
**Author:** Ivan Misic
**Published:** 2026-08-13
**URL:** https://ivanmisic.net/blog/ai-tools/what-using-claude-code-looks-like
**In plain English**
Using Claude Code is a four-step loop: ask in plain English, let it make the change, check what changed, decide the next step. The rest is detail on one of those steps.
- Name the file and the visible problem, because a vague request is what produces a wrong change
- Six commands worth learning first: `/context`, `/clear`, `/compact`, `/diff`, `/rewind`, `/plan`
- Check the diff and test the result before building anything on top of it
- Keep two recovery layers: checkpoints for recent direct file edits in the session, and Git for durable file history
Using Claude Code is a loop, not a prompt. You say what you want in plain English, it changes something, you check the change, and you decide what happens next.
An install command and one clever example do not show that loop. Here is what a normal hour looks like, including what to do when Claude changes the wrong file.
I built this site with it. Early on I asked it to clean up the footer, and it read that as "remove the unnecessary parts". My links, social icons and copyright notice went with them. Nothing there was a bug. I gave a vague instruction to something that edits real files, and it did what I asked.
## What it is, in one paragraph
This article covers the terminal version of Claude Code: Claude working inside a folder on your computer. It can read your files, edit them, run commands, and tell you what it did. You talk to it in normal sentences, and it does the typing. There's no code to write to get started, which is why people with no development background can use it at all. [Chapter 1 covers what that actually means](/blog/ai-tools/meet-your-ai-assistant) if the idea is new to you.
The consequence that matters: it changes real files. How often it asks first depends on the permission mode, your settings and where you run it. You still need to understand what the tool is doing, which is why so much of this guide is about checking and recovering.
## Getting it running
Two steps. Opening the terminal is the unfamiliar one if you've never used it before.
You open a terminal. On a Mac that's the Terminal app, on Windows it's PowerShell or Windows Terminal. If you've never used one, it's a window where you type commands instead of clicking. That's the whole concept. [Opening the terminal](/blog/ai-tools/opening-the-terminal) walks through it slowly.
Then you install Claude Code and sign in. [The install chapter](/blog/ai-tools/installing-claude-code-five-minutes) has the current commands for Mac, Windows, and Linux.
One thing worth deciding before you start: which folder you point it at. Claude Code uses the folder you open as its working directory, so a new empty folder narrows what is in scope. It is not a security sandbox.
## Your first session
Start it in your project folder, then type what you want. Plain English. No special syntax.
The easy mistake at the start is being too vague. "Fix the header" is a reasonable thing to say to a colleague who can see your screen, and a bad thing to say to something that has fifty files and no eyes. Name the file and name the visible problem:
```text
In pages/contact.html, fix the header spacing. The heading is
too close to the navigation bar.
```
That one habit gives Claude Code less room to guess. [Giving better instructions](/blog/ai-tools/giving-better-instructions) is the chapter on it, and [your first conversation](/blog/ai-tools/first-conversation-with-claude-code) walks through a full session from the first line.
You'll also need to choose how much Claude Code can do without asking. `Shift+Tab` cycles the common permission modes in the terminal. Start in Manual mode while you're learning, because reviewing each edit and command shows you what the tool is doing. Looser modes are useful later, but approving on reflex defeats the point.
## The commands that matter
There are many. These are the six worth learning first:
| Command | What it is for |
|---|---|
| `/context` | See what is filling the context window |
| `/clear` | Start fresh when the task changes; your files stay untouched |
| `/compact` | Shorten a long session you still need to continue |
| `/diff` | See exactly what changed |
| `/rewind` | Undo back to a point before it went wrong |
| `/plan` | Get the approach proposed before anything is edited |
Use `/plan` before a task touches several files. Asking for the approach first catches a wrong direction while it's still free to change.
## Working on something real
The safe pattern on an actual project is boring, and boring is the point. Break the thing into steps small enough to check, then do one at a time.
"Add a blog to my site" is a project. A task is "create a blog listing page that shows post titles and dates, in the same style as the rest of the site". You review that, then ask for the next piece. If something goes wrong you know which step did it, and you lose one step instead of a day.
As the project grows, two habits start to matter. Write your project's rules into a `CLAUDE.md` file so you're not repeating them every session. And [plan before you build](/blog/ai-tools/claude-code-plan-mode) anything structural. [The CLAUDE.md chapter](/blog/ai-tools/claude-md-file) covers the first part.
Module 4 takes this from an empty folder to [a live site](/blog/ai-tools/saving-work-going-live).
## When it goes wrong
It will. Plan the time for it.
The recovery order is worth knowing before you need it. Run `/diff` and test the behaviour you asked for. The summary tells you where to look. Only the diff tells you what happened. If the change is wrong, press `Esc` twice or use `/rewind` and go back to the prompt before the mistake. Checkpoints keep snapshots for the 100 most recent points in a session and are cleaned up with the session after 30 days. They cover Claude's direct file edits. They do not cover shell-command changes, database or deployment side effects, or most subagent edits. For durable file history outside checkpoint coverage, use Git.
The failure that costs real time is quieter than a deleted footer. You ask for a fix, it doesn't work, you ask again, it still doesn't work, and five speculative changes later nobody can tell which one broke what. One change, one check. When a fix fails twice in a row, restore the last good state and start again with what you learned by then. [When things go wrong](/blog/ai-tools/when-things-go-wrong) is the full chapter, and [staying safe](/blog/ai-tools/claude-code-permissions) covers permissions, secrets, and the recovery layers.
## What this will not do
It won't read your mind about a project it has never seen, which is what the `CLAUDE.md` file is for. It won't stop you approving something you didn't read. And it doesn't remove the need to test, because a change that looks right in a diff can still be wrong in a browser.
## Where to go from here
If you've never opened a terminal, start at [chapter 1](/blog/ai-tools/meet-your-ai-assistant) and go in order. If you're already installed and want the habits that make it stick, jump to the fundamentals module. If your project is bigger than a handful of files, [working on bigger projects](/blog/ai-tools/claude-code-context-window) is where the one-task-per-session rule starts to pay off.
The loop does not change: ask, check, decide. With practice, you can let it do more before checking.
## Sources
- [Commands](https://code.claude.com/docs/en/commands), Anthropic. Documents `/context`, `/clear`, `/compact`, `/diff`, `/rewind`, and `/plan`, including platform and version-dependent availability.
- [Choose a permission mode](https://code.claude.com/docs/en/permission-modes), Anthropic. Documents Manual mode, the `Shift+Tab` cycle, and the actions each mode allows without asking.
- [Checkpointing](https://code.claude.com/docs/en/checkpointing), Anthropic. Supports the 100-checkpoint limit, 30-day default retention, rewind controls, and exclusions for shell-command and most subagent edits.
- [How Claude Code works](https://code.claude.com/docs/en/how-claude-code-works), Anthropic. Explains the file, command, permission, and checkpoint loop described in the article.
---
# Capturing Outlook email and calendar with Power Automate
**Author:** Ivan Misic
**Published:** 2026-07-22
**URL:** https://ivanmisic.net/blog/ai-tools/email-calendar-capture-without-api
**In plain English**
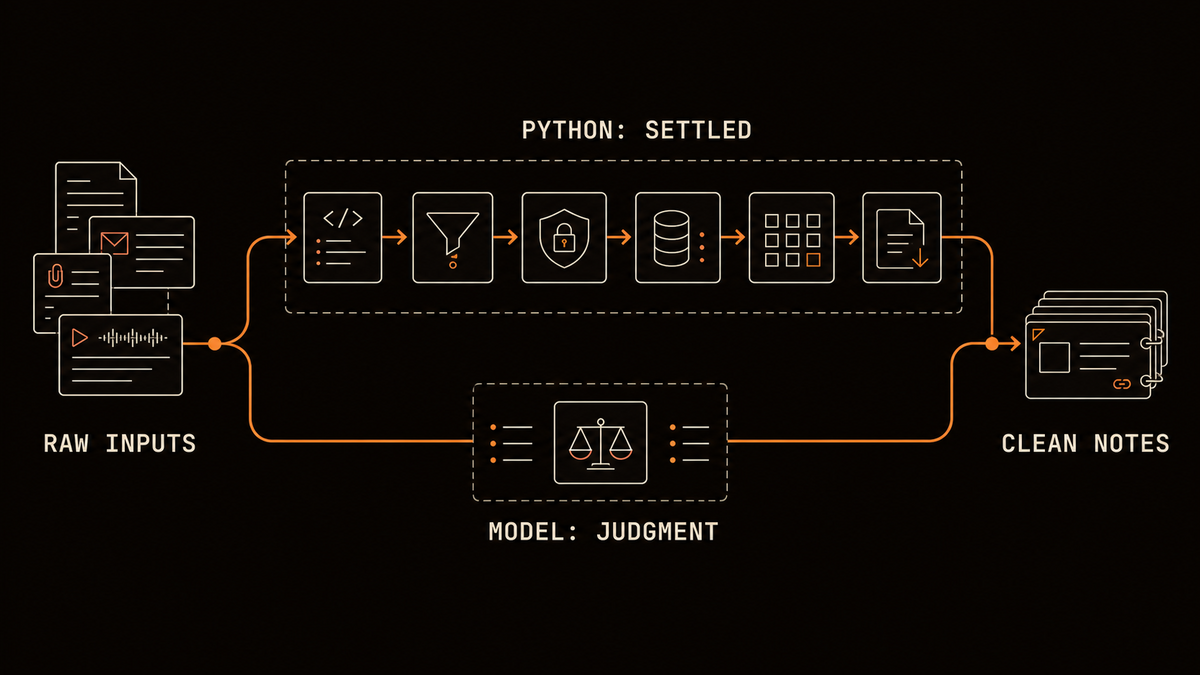
Without mailbox API access, I use the approved route already available: Power Automate writes selected mail and today's calendar to OneDrive, then a 15-minute Windows task moves the files into my local vault. The task marks processed mail and keeps sent and received messages distinct. The files still contain real names, addresses, and work content at this stage; masking happens later. Connectors can delay or skip messages, so check company policy and do not treat this as a complete archive or live assistant.
Your email and calendar are the richest record of your work week, and usually the most locked down. In [the overview of my Obsidian and Claude setup](/blog/ai-tools/claude-obsidian-second-brain) I mentioned getting both into a local inbox with no API access at all. This is how, in enough detail to copy.
## The obvious routes are closed
The clean way to read a corporate mailbox from a script is an API: Microsoft Graph, or plain old IMAP. In this workplace, a Graph app registration and mailbox permission approval were unavailable, and IMAP was disabled. The front door was locked, and it was locked for good reasons.
Power Automate gives me another route. My company already provides it, and its approved connectors can read the mailbox and calendar and write files to OneDrive. OneDrive syncs those files to my laptop. From there, a small scheduled task drops them into the vault.
## The shape of it
The whole path runs one direction, mailbox to local folder:
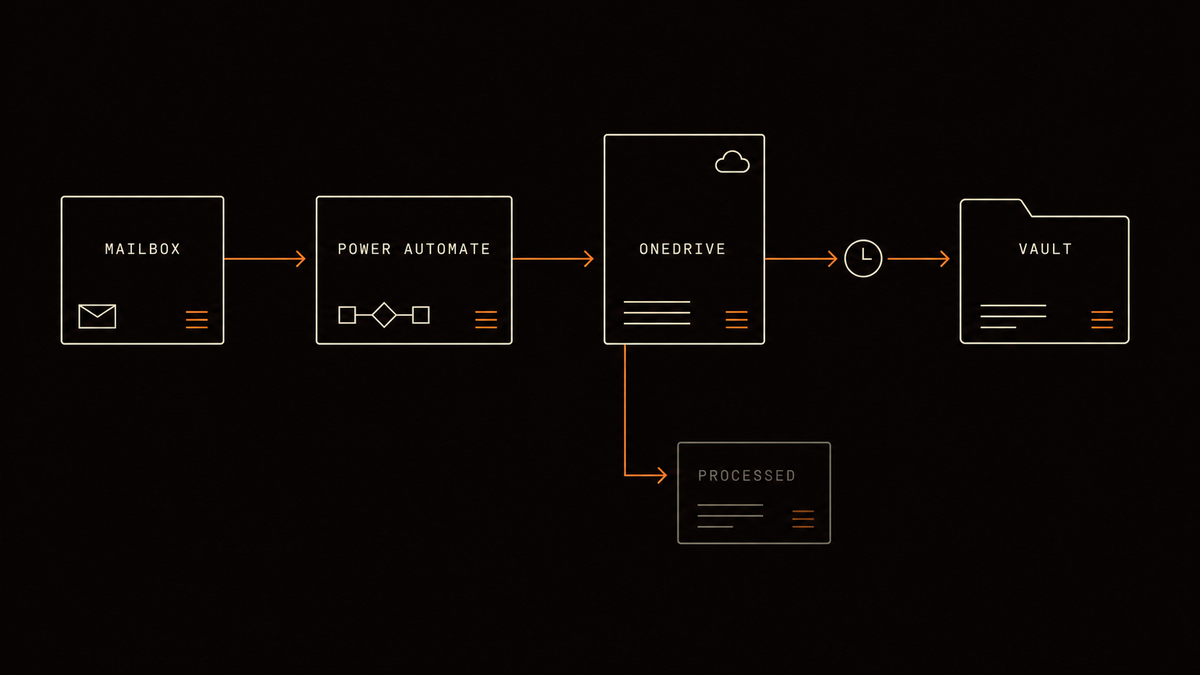
Every hop is dumb and independent. If OneDrive is slow, the flow still runs. If the laptop is off, the files wait in the cloud. Nothing holds a connection open, so nothing has a connection to lose. I prefer this to a proper integration because each step can fail without stopping the others.
## Flow 1: capture the mail you care about
Received mail is captured by flag, not by firehose. I don't want every email in the vault, I want the ones that matter, so the flow triggers on **When an email is flagged (V3)** in the Inbox. I flag a message in Outlook, the flow fires, fetches the email, converts the HTML body to plain text, and writes a `.txt` into `EmailCapture/Vault`. Then it unflags the message to reduce repeat runs. That is not a guarantee: [Microsoft says a flagged-email trigger can fire again when an already flagged message changes](https://learn.microsoft.com/en-us/connectors/office365connector/), so the filenames still need collision handling. Any attachments go alongside it in `EmailCapture/Vault/Attachments`, numbered so two files called `report.pdf` can't collide. If I tag the email with an Outlook category first (VIP, Follow Up, Waiting), the flow captures that too, and falls back to `Uncategorized` when I haven't.
The file the Compose step assembles comes out like this:
```
Type Category: VIP
Type From: sender@example.com
Type To: you@example.com
Type CC:
Type Subject: RE: Q2 Budget Review
Type Date: 2026-03-06T14:30:00Z
Type ConversationId: AAQkAGI2...
Could you review the attached budget before Thursday...
```
That [`ConversationId`](https://learn.microsoft.com/en-us/connectors/office365connector/) is Outlook's thread identifier, captured so the vault can group a reply chain with certainty instead of guessing from the subject line. The `Type ` prefix on every header is a Power Automate quirk, and I'll come back to it.
## Flow 2: capture everything you send
Sent mail is the opposite. I want all of it with no effort, so that flow triggers automatically on every new item in **Sent Items**. A condition filters out the automatic meeting accept and decline replies so they don't become noise, then it converts the body to text and writes a `.txt` into `EmailCapture/Sent`. No flag, no thought.
That condition matches on the subject prefix, so it needs every language your calendar replies arrive in. Mine checks eleven prefixes across English, German, and Croatian, because a `Declined:` filter does nothing about an `Abgelehnt:` or an `Odbijeno:`. If your work spans more than a couple of countries, that list only grows, and every language you miss is a category of noise you'll be deleting by hand later. Check your own sent folder before you assume one covers it.
The sent file uses plain headers, and the `From` field comes out empty:
```
From:
To: colleague@example.com
CC:
Subject: RE: Some Subject Here
Date: 2026-03-06T14:30:00Z
ConversationId: AAQkAGI2...
Email body in plain text...
```
## The two-formats gotcha
Look at the two examples. Received mail prefixes every header with `Type `, sent mail doesn't, and sent mail has an empty `From`. That isn't a format I designed; it is what these two flows produced in my tenant. Instead of fighting Power Automate into agreement, I let the parser downstream read both shapes. The capture layer has exactly one job: get each file into the right folder. That empty `From` on sent mail is the reason the bridge script matters later.
## Flow 3: the senders you can't afford to miss
Flagging works on the days I'm reading my inbox. It fails on the days I'm not, and those are exactly the days something from the wrong person sits unread until Thursday. So the third flow watches people instead of messages.
The tagging half isn't Power Automate at all. An ordinary Outlook rule puts a `VIP` category on anything from the senders I list, the moment it arrives. Then the flow wakes up every 15 minutes and asks the mailbox for `category:VIP NOT category:VIP-Captured`, takes up to ten at a time, writes each one out the way Flow 1 does, and stamps the message with a second category, `VIP-Captured`.
That second category is the trick. Flow 1 can unflag a message to stop it firing twice, but this one can't clear the `VIP` tag, because I still want it there when I go looking. So it adds a marker instead, and the search query filters on it. There's no list of processed IDs anywhere, and if I ever want a message recaptured I delete one category by hand.
One difference from Flow 1 that matters downstream: VIP mail lands in its own `EmailCapture/VIP/Vault` folder, so the bridge script treats it as a separate source. Otherwise it behaves the same, attachments included.
## And the calendar
The calendar is one more flow, scheduled to run every 30 minutes through the workday. It uses **Get calendar view of events (V3)** for today's range and a **Select** to keep the fields I care about (subject, start, end, organizer, attendees, online meeting link). The target is `yyyy-MM-dd-calendar.json` in `EmailCapture/Calendar`.
Do not rely on **Create file** to replace that file. [Microsoft's OneDrive for Business reference](https://learn.microsoft.com/en-us/connectors/onedriveforbusinessconnector/) does not document an overwrite option for that action. Make the replacement explicit: list the files in `EmailCapture/Calendar`, match the exact daily filename, and use **Update file** with its ID when it exists. Use **Create file** only when there is no match. Test the second run. The result should be one fresh snapshot, not a failed flow or a pile of duplicates.
## The bridge: one scheduled task
The files are now in OneDrive, which syncs to the laptop. The last hop is a small PowerShell script on a 15-minute timer. It walks each capture folder in turn: received mail into the inbox as-is, VIP mail the same way from its own folder, sent mail with a `SENT-` prefix, and the calendar snapshot refreshed. The core of it, trimmed to three of the four:
```powershell
$ErrorActionPreference = "Stop"
$Sent = "$env:USERPROFILE\OneDrive\EmailCapture\Sent"
$Received = "$env:USERPROFILE\OneDrive\EmailCapture\Vault"
$Calendar = "$env:USERPROFILE\OneDrive\EmailCapture\Calendar"
$Inbox = "$env:USERPROFILE\Obsidian\WorkVault\00-Inbox"
$SentProcessed = Join-Path $Sent "Processed"
$ReceivedProcessed = Join-Path $Received "Processed"
New-Item -ItemType Directory -Path $SentProcessed -Force | Out-Null
New-Item -ItemType Directory -Path $ReceivedProcessed -Force | Out-Null
# Sent mail -> inbox, tagged so the direction survives
Get-ChildItem -LiteralPath $Sent -Filter *.txt | ForEach-Object {
Copy-Item -LiteralPath $_.FullName -Destination (Join-Path $Inbox "SENT-$($_.Name)")
Move-Item -LiteralPath $_.FullName -Destination (Join-Path $SentProcessed $_.Name)
}
# Received mail -> inbox as-is
Get-ChildItem -LiteralPath $Received -Filter *.txt | ForEach-Object {
Copy-Item -LiteralPath $_.FullName -Destination (Join-Path $Inbox $_.Name)
Move-Item -LiteralPath $_.FullName -Destination (Join-Path $ReceivedProcessed $_.Name)
}
# Calendar -> overwrite today's snapshot
Get-ChildItem -LiteralPath $Calendar -Filter *-calendar.json | ForEach-Object {
Copy-Item -LiteralPath $_.FullName -Destination (Join-Path $Inbox $_.Name) -Force
}
```
The full version adds a `-2` suffix when a filename already exists and rotates its own log. The important line in the trimmed version is `$ErrorActionPreference = "Stop"`. [PowerShell's default for non-terminating errors is to report the error and continue](https://learn.microsoft.com/en-us/powershell/module/microsoft.powershell.core/about/about_preference_variables). Without that stop, a failed copy can still reach `Move-Item`, which marks a file as processed before it reaches the inbox. The safe order is copy, stop on failure, then move.
The `Move-Item` into `Processed` is doing more work than it looks like. After a successful copy and move, the next run has nothing to reconsider and the capture folder does not grow forever. Copy and move are separate steps, though: if the copy succeeds and the move fails, the next run can create a suffixed duplicate. The original remains in `Processed` after a successful move.
That `SENT-` prefix is the dumbest and most useful line in the file. Power Automate hands me sent mail with an empty `From`, so the content alone can't tell me which way a message went. Four characters added at copy time settle it for good, and every step downstream just reads the filename.
## Put it on a timer
Register the script as a scheduled task that fires every 15 minutes while you're logged in:
```powershell
$Action = New-ScheduledTaskAction -Execute "powershell.exe" `
-Argument '-NoProfile -WindowStyle Hidden -File "C:\path\to\Pull-Emails.ps1"'
$Trigger = New-ScheduledTaskTrigger -Once -At (Get-Date).AddMinutes(1) `
-RepetitionInterval (New-TimeSpan -Minutes 15)
Register-ScheduledTask -TaskName "PullEmails" -Action $Action -Trigger $Trigger `
-Description "Copies captured mail and calendar into the vault inbox"
```
Do not override the machine's execution policy here. If a managed laptop blocks the script, that is a policy decision to resolve with IT, not a switch to bypass in the task definition.
If the console window flashing every fifteen minutes bothers you, and it will, wrap the call in a one-line `.vbs` launched with `wscript.exe` so it runs fully hidden. Tiny thing, real quality-of-life gain.
### If your vault already lives in OneDrive
Then you can skip most of this. Point the Power Automate **Create file** step straight at the vault's inbox folder and the files arrive on their own, no scheduled task anywhere.
I kept the task, and the reason is the three small things it does on the way past: the `SENT-` prefix, the `Processed` move, and the duplicate-name suffix. Write directly into the inbox and you lose all three, which means sent and received mail become indistinguishable and nothing ever gets swept out of the capture folder. If you don't need that distinction, take the shorter path. I did need it, so I pay one scheduled task for it.
## What the AI actually sees
Worth being exact here, because "my work email goes into a folder an AI reads" deserves a straight answer.
Everything described so far moves your real mail. The file that lands in your inbox has real names and real addresses in it, and nothing is masked on this leg. Before the model step, the route is mailbox to corporate OneDrive to your laptop. It does not send mail to a model yet, but it does create new copies. Those copies can change who can access the data, how long it is kept, and which backups contain it. That needs the same policy check as the flow itself.
The masking happens one step later, before anything reaches a model. A script swaps addresses, phone numbers, and the other patterns that scan as private for tokens, and keeps the real values in a local map the model never gets handed. I went through that in [the overview of the setup](/blog/ai-tools/claude-obsidian-second-brain). It lowers what gets sent rather than pretending to eliminate it, and it's honest about the gap: subject lines and meeting titles still go out roughly as written.
So the capture layer is not the privacy layer, and this post only covers the first one.
## Why text files instead of a real integration
This looks primitive next to a proper API client, and that is the point. A token-based integration is a thing that breaks. Tokens expire, scopes change, rate limits bite, a refresh quietly fails overnight and the sync is down until you happen to notice. A folder of text files avoids those token and API failure modes. Each email is one file, so failures are visible and retriable. The bridge still needs its log because a copy can succeed before the move fails. Keeping the transport alive is OneDrive's job, and OneDrive is very good at its job.
## What this won't do
A few honest limits:
- It needs Power Automate access, and [the license assigned to your account sets request limits](https://learn.microsoft.com/en-us/power-platform/admin/api-request-limits-allocations).
- It isn't real-time. The VIP route can wait almost 15 minutes for the mailbox flow and another 15 for the local task, plus OneDrive sync. Flagged and sent mail can also wait on the connector, and [Microsoft says rare trigger delays can reach one hour](https://learn.microsoft.com/en-us/connectors/office365connector/). Fine for a once-a-day review, not fine for a live assistant.
- The **When a new email arrives (V3)** trigger used for sent mail can skip messages above the tenant limit or 50 MB, whichever is lower. [Microsoft also says it may skip protected mail or messages with invalid bodies or attachments](https://learn.microsoft.com/en-us/connectors/office365connector/). This is useful capture, not a complete archive.
- The scheduled task is Windows. The same pattern runs on a Mac or Linux box with `cron` and a OneDrive-compatible sync client; the script is just shell instead of PowerShell.
- Check your own policy. Exporting mail to files, even your own mail, may or may not be allowed where you work. This is a know-the-rules situation, not an ask-forgiveness one.
## The boring part is the important part
None of this is clever. It is a flow, a sync folder, a timer, and a four-character prefix. But the rest of the pipeline only works when the data arrives. Make the capture reliable first. The interesting parts depend on it.
I don't think this is the permanent shape of it. My guess is that within a few years the assistant just has a sanctioned connector to your mailbox, IT is comfortable switching it on, and none of this plumbing is anyone's problem. That's a prediction, not a roadmap, and I've been wrong about timelines before. What I am confident about is the current gap. These tools could do much more with work context than most IT departments allow them to access. A flow and a sync folder is what half-automation looks like while you wait. I'd rather run the boring version today than wait for the clean one to get approved.
Next: what happens to all of this once it lands, and why [most of that pipeline isn't AI at all](/blog/ai-tools/script-first-ai-pipeline).
## Sources
- [Office 365 Outlook connector](https://learn.microsoft.com/en-us/connectors/office365connector/), Microsoft. Documents the flagged-email and calendar triggers, their limitations, and the `ConversationId` field.
- [OneDrive for Business connector](https://learn.microsoft.com/en-us/connectors/onedriveforbusinessconnector/), Microsoft. Shows why create-or-update behavior needs an explicit lookup and update path.
- [about_Preference_Variables](https://learn.microsoft.com/en-us/powershell/module/microsoft.powershell.core/about/about_preference_variables), Microsoft. Documents the default handling of non-terminating PowerShell errors.
- [Requests limits and allocations](https://learn.microsoft.com/en-us/power-platform/admin/api-request-limits-allocations), Microsoft. Explains that Power Platform request allowances depend on the license and are enforced over daily periods.
---
# Splitting an AI pipeline between Python scripts and the model
**Author:** Ivan Misic
**Published:** 2026-07-22
**URL:** https://ivanmisic.net/blog/ai-tools/script-first-ai-pipeline
**In plain English**
Most of this pipeline is ordinary Python, not AI. Code handles repeatable work such as parsing, matching records, and removing duplicates before a language model summarizes messages, identifies actions, and handles the few judgment calls. That makes the result easier to test and keeps the model work smaller.
Most of my "AI pipeline" isn't AI. By share of the code, and by share of the actual work, the part that turns a messy inbox into clean, linked notes is plain Python. The language model is one small, expensive component I call as rarely as I can manage. It didn't start that way. I built the expensive version first.
## The expensive first draft
The first version let the model do everything. It read each email and parsed the `From:` and `Subject:` lines. It matched names to people. It scored how important the message was. It grouped replies into threads, caught duplicates, and decided what to write to disk. End to end, one long act of language-model judgment.
It worked. It was also slow, costly, and quietly unreliable. Feed it the same inbox twice and you'd get two slightly different results, because a model is a probability machine, not a parser. And an LLM that gets header parsing "mostly right" is worse than five lines of Python that get it exactly right every time, because now you're debugging a hallucinated field instead of a regular expression.
## The line that matters: fuzzy versus settled
It started with one distinction. A pipeline like this is really two kinds of work tangled together:
- **Settled work** has exactly one correct answer. Parsing a header, looking a name up in a table, stripping a signature block, deciding whether two files are duplicates, writing YAML to disk. There is a right answer and a wrong one.
- **Fuzzy work** needs judgment. What is this email actually about? What did someone commit to? Is this borderline message worth a full note?
Code handles settled work well and costs almost nothing. It cannot make the fuzzy calls. A language model is useful for judgment but wasteful and less reliable when you make it do clerical work. So the whole game is to split the task along that line and give each half to the tool that's good at it.
Code handles the settled work. The model only handles the judgment call.
## Let the script settle everything it can
In my pipeline, one Python script does all the settled work in a single pass before the model is ever called. Given a fresh inbox, it:
- detects what each file is (email, transcript, document),
- parses the headers, including the two awkward formats from [the capture flow](/blog/ai-tools/email-calendar-capture-without-api),
- strips the boilerplate (footers, disclaimers, signatures, link wrappers) with plain regex,
- swaps email addresses and phone numbers for tokens, so the model never sees raw contact details,
- resolves every name and address to a person through a registry, not a guess,
- scores each message's relevance by rule,
- groups replies into threads and drops duplicates,
- and pre-writes the filename and metadata for every note.
The output is one clean, structured file describing exactly what is in the inbox. By the time the model wakes up, there are no `From:` lines left to parse, no names left to guess, no duplicates left to catch.
## What's left is judgment
Stripped of the clerical work, the model's job gets small and sharp. For each cleaned message it does four things: write a one-line summary I'll actually read, pull out the real action items, flag any committed decisions, and settle the rare "is this high or medium relevance" call the rules couldn't. That's it. Judgment, and nothing else.
It's better at that job because it isn't also parsing headers. A model asked to do one fuzzy thing on clean input is faster, cheaper, and steadier than the same model asked to do everything on raw input. You didn't make it dumber. You stopped distracting it.
## Two moves that made it cheap
Two less obvious decisions did most of the work on cost and speed.
The first is keeping the heavy data out of the conversation. The preprocessing writes a full manifest, which can run to tens of kilobytes, to a file, and prints only a tiny summary to the part of the system that coordinates everything. That coordinator never reads an email body or the registry. It works from a two-kilobyte overview and hands the detailed file only to the workers that need it. Context you don't load is context you don't pay for.
The second is not making the model repeat itself. The worker agents write their results straight to a file and hand back a one-line pointer, instead of re-emitting thousands of lines of structured output back through the conversation. A plain script reads that file and does the writing. Pushing a big result back through the model costs you twice, in tokens and in wall-clock, for output you already had.
## What it bought
Put together, a normal morning, a dozen emails and a few transcripts, finishes in a few minutes. The Python part takes seconds. The model only ever touches pre-chewed data, so it stays quick and consistent, and the bill stays small because most of the work never became tokens at all.
There is a quieter payoff too. The settled work is deterministic, so when something breaks it breaks the same way every time, and a reproducible bug is a fixable bug. It is also testable in the ordinary way: I have unit tests on the header parser and the dedup logic, and they catch regressions before a single token is spent. Evaluating whether a summary is useful needs a rubric or human judgment, which is less exact than a parser test. That is why you want as much of the pipeline as possible on the deterministic side.
For something I run on my own machine, the money was never really the headline. It rounds to nothing either way. What I wanted was the same inbox producing the same result twice, and something to point at when it doesn't. My scoring rules are not the best possible rules. They're written down, which means when they call a message important and it plainly isn't, I change one line and every run after that is better. A prompt that felt about right last month gives me nothing to grab.
## The smartest part is how little of it is smart
The instinct, when you have a model this capable, is to hand it the whole problem and admire the result. The discipline is to hand it only the part that is actually ambiguous, and to push everything else down into code where it is exact and free. In pipelines like this, many complaints about speed, cost, or reliability come from the same mistake: using a model where a function would do.
Find the seam between the fuzzy and the settled, and put as little as you can on the expensive side of it. Across [the whole pipeline](/blog/ai-tools/claude-obsidian-second-brain), the best design decision was how little of it is the clever part.
Next: [the layer that ties all of this together](/blog/ai-tools/claude-code-skills-workflow), the handful of commands that actually run the thing.
---
# Claude Code skills: building a workflow that runs itself
**Author:** Ivan Misic
**Published:** 2026-07-22
**URL:** https://ivanmisic.net/blog/ai-tools/claude-code-skills-workflow
**In plain English**
The control layer of my work system is Markdown instructions and small scripts, because building an app for a workflow that keeps changing would create more maintenance than value. The scripts handle repeatable work, Claude Code handles judgment, and a small set of commands processes notes, email, and meeting material already saved in a local folder. I can change the workflow by editing plain text, but the model work still uses Anthropic's service and plan quota.
The control layer of [my work system](/blog/ai-tools/claude-obsidian-second-brain), the part that decides what runs and when, is markdown plus a set of small scripts. No web framework of my own. No app server or job queue to maintain. I write what I want in plain English, the scripts handle deterministic work, Claude Code handles judgment, and one command processes my whole morning.
The work itself lives in a vault, which is Obsidian's word for a folder of plain notes sitting on your own disk. Mine holds the email, meetings, and documents from my week.
One command coordinates the work. The small files do the jobs.
## A skill is just a markdown file
In Claude Code, a skill, also called a slash command, is a markdown file full of instructions. You describe what the command should do in the same words you'd use to brief a colleague, and it becomes something you run with a slash. One of mine, stripped down, reads roughly like this:
```markdown
# w-1on1: one-on-one prep
When I run /w-1on1 [name]:
1. Pull this person's last few interactions from the index.
2. List the open action items they own, and the ones I owe them.
3. Draft three talking points from the recent threads.
Keep it to one screen. Link to the source notes instead of restating them.
```
That is the core of the skill. The real version is longer: it builds the indexes, prepares a small data bundle, and hands the synthesis to an Opus worker with limited tools. The procedure itself is still plain instructions rather than application code. I covered the mechanics of writing them in [Creating reusable Claude Code skills](/blog/ai-tools/creating-reusable-recipes). Here I want to show what a real set of them looks like.
Mine all start with `w-`:
| Command | What it does |
|-|-|
| `/w-daily` | Process everything that came in, email, meetings, documents, notes, into one briefing |
| `/w-review` | Roll a week or a month up: what happened, what moved, what's still open |
| `/w-1on1` | Prep a one-on-one: recent history, open items, talking points |
| `/w-project-status` | Summarize where a project stands |
| `/w-prep` | Gather what I need before a conversation, or recap what I did |
| `/w-task-audit` | Sweep the open action items, which pile up fast once an AI is the one adding them |
| `/w-setup` | One-time wizard that configures the vault to you: identity, VIPs, projects, tools |
Seven commands, and the first one does most of the work.
## Skills do, rules define
The other half of the system is rules. Where a skill is a procedure (do this, then this), a rule is a standard the work has to meet: how to turn a name into a link to the right person, what actually counts as an action item, who sits in which tier of seniority. Rules live in their own folder and [load with the project](/blog/ai-tools/claude-code-rule-files), so the skills don't have to restate them.
Keeping those two apart is the part I'd most recommend copying. When I change how names resolve to people, or what counts as a verified action, I change the shared rule rather than every command. The procedures and the policies don't get tangled.
## One front door
I could have a command per source, one for email, one for transcripts, one for documents. I don't. Everything funnels through `/w-daily`, but the sources arrive in different ways. A scheduled Windows task copies captured email into the inbox. I drop documents and loose notes there too. Plaud recordings can be pulled when the command runs. `/w-daily` does not fetch email. It processes whatever is waiting and writes the day's briefing. One command, the whole morning, which is the entire point of building it.
I run one command, then read the resulting briefing.
## It spawns its own workers
`/w-daily` doesn't grind through all of that itself. For larger batches it dispatches general-purpose sub-agents that run [in parallel](/blog/ai-tools/doing-multiple-things-at-once): one prompt handles transcripts, another email, another documents. Smaller email and document batches stay in the main context. The master skill coordinates and composes, while the prompt files keep each worker focused on one kind of note. Splitting the work this way avoids processing everything one by one.
## A cheap brain and a smart brain
Not every job deserves the best model. The high-volume workers, the ones reading an email or condensing a transcript, run on a fast and cheap model that follows clear rules well. The judgment-heavy skills, the weekly review or the one-on-one prep, run on the strongest model I have, because that is where writing quality and real synthesis matter. The command doing the orchestrating mostly just routes each job to the right brain. Most tasks use the cheaper model. I use the expensive one only where the extra quality matters.
## Why not a real app?
A custom application doing the same thing would need a web framework, a job queue, an API client, authentication, somewhere to deploy it, and a pile of code to keep alive. The markdown approach has none of that. The skills and rules are version-controlled text. When the workflow changes, and it changes constantly, I edit a file in plain language instead of refactoring a service. The whole system is small enough that I can read all of it.
There's a blunter version of that argument. Building the app would cost me more hours than the problem is worth. What I need shifts every few weeks, so I'd be maintaining software about my own habits, and the maintenance would outlive most of the habits. Writing down what I want takes minutes, and the writing is the thing that runs.
The files also stay mine in the most literal sense. The vault copies to a new laptop the way any documents folder does, and I don't run my own server for it. Claude Code still sends the note content to Anthropic for the model work and uses my plan quota. Local files do not mean local processing.
## The system is legible
Being able to read the whole system is the real win. The thing running my work is a folder of instructions a careful person could follow by hand. I can read exactly what a command will do before I run it. I can change its behavior by editing a sentence. And because it's all plain language, I can hand a piece of it to the AI itself and ask it to extend the system it runs inside. If you'd like to read the actual skills and rules, a sanitized copy of the whole vault is [public on GitHub](https://github.com/imisic/claude-obsidian-vault).
If you've used Claude Code to knock out a one-off task, this is the same tool with the tasks made permanent. That is the whole series, really. Not one clever trick, but a stack of small, legible, boring parts, each doing a job it's actually good at: the capture, the transcript processing, the script-first preparation, and the handful of commands that tie them together. None of it is the thing from the keynote. All of it is mine, and I can read every line.
---
# The Claude Code plugins I built and run
**Author:** Ivan Misic
**Published:** 2026-07-06
**URL:** https://ivanmisic.net/blog/ai-tools/claude-code-plugins
**In plain English**
I put the Claude Code plugins, rule files, and prompts I reuse into one public toolshed. Some install directly. Others generate project-specific tools such as review instructions, because copying my setup would bring along assumptions from my codebase. Everything is free and available without sign-up.
I put the Claude Code tools I reuse across projects into one public [toolshed](/toolshed): project-specific generators, everyday workflow commands, anti-slop checks, search visibility, rule packs, and prompts. Some tools install as they are. Others generate a version for your codebase, because copying mine would miss the point.
## What's on the shelf
The Claude Code side currently has eight standalone skill pages, six installable plugins, five rule packs, and a growing prompt shelf.
| On the shelf | What it is |
|-|-|
| [Project tooling generators](/toolshed/plugins/dev-workflow-forge) | Three skills that write or improve a review skill, a rules set, and a self-learning loop fitted to your project |
| [Everyday loop](/toolshed/plugins/dev-loop) | `fix`, `commit`, and `ship` commands that run the day-to-day cycle, portable as they are |
| [Anti-slop scanners](/toolshed/plugins/unslop) | Three of them, catching the tells that make prose, code, or UI read as machine-written |
| [Search visibility](/toolshed/plugins/search-visibility) | Two skills: one turns a Search Console export into a ranked action plan, while the other checks whether AI assistants can reach, understand, and cite your site |
| [Role lenses](/toolshed/plugins/role-lenses) | Six senior-review viewpoints that argue from a specific role instead of agreeing with everything |
| [Public-release safety](/toolshed/plugins/sanitize-public) | Checks an artifact for secrets before it ships, and had to be de-leaked itself first |
| [Rule packs](/toolshed/rules/generic-rules) | Downloadable `.claude/rules/` sets: a generic baseline plus [PHP](/toolshed/rules/php-rules), [Python](/toolshed/rules/python-rules), [React](/toolshed/rules/react-ts-rules), and [Flutter](/toolshed/rules/flutter-rules) |
| [Prompts](/toolshed/prompts) | Copyable starting points from the articles, plus `a-make-prompt` for turning a rough request into a finished prompt |
None of this is a product. It's the stuff I use, some of it daily, some only when the job calls for it, cleaned up enough to hand over. The collection keeps changing as I find another repeated job worth packaging or a weak spot in something I already shared.
## The naming system behind it
The list keeps growing, so I needed a naming system.
Anything I use across every project gets an `a-` prefix: `a-review-optimizer`, `a-sanitize-public`, and so on. Two reasons, both boring. The `a` puts my own tools first in any alphabetical listing, and it marks a tool as mine and portable at a glance. When a list of skills scrolls past, I know instantly which ones travel with me.
Anything tied to one project gets a short project prefix instead. For this site that's `im-`, my initials, so the review skill here is `im-code-review`. Overkill for a single repo? Probably. But the setup grows fast: a backend, a frontend, an app, each with its own review skill. A parent-level agent can see them all. That's when the prefixes keep one project's `review` from colliding with another's. Complex setups get there faster than you'd think.
That habit is also what made sharing cheap: when it was time to pick what goes public, the `a-` list was the shortlist. Those tools were built portable from day one. Everything else stayed home.
## Why I share the generator, not my copy
I share the generator, not my finished setup. When I first thought about sharing my review command, I assumed the command was the thing to share. It isn't.
My review command is good because it's specific. It knows my controllers, my service layer, the exact mistakes I've made and told it to stop repeating. That specificity is the whole value, and it's also what makes it useless to you. Your project isn't mine.
So for the project-tuned tools, I share the [generator](/toolshed/plugins/dev-workflow-forge) that produces them. You point it at your repo and get your own review skill, fitted to your code, with none of mine in it. The rules generator works the same way. The portable pieces, the [everyday loop](/toolshed/plugins/dev-loop) and the [role lenses](/toolshed/plugins/role-lenses), ship as they are, because they never knew anything about my projects to begin with.
And this isn't a one-time setup. I've started calling the generators my godfather skills: they set up a project's tooling at the start, then keep showing up to correct it. Every few weeks on a fast-moving codebase, monthly elsewhere, I re-run them, because the code evolves and the review skill and rules drift behind it. A re-run reads the project as it is now and pulls the tooling back in line. If you take the generators, plan for that rhythm; the first run is the smallest part of the value.
The tradeoff is honest. A generator is more work to build than a file you copy, and it's only worth having if it produces something good. When it works, you no longer need to strip my project out of the result. The output was made for your project from the start.
## What rule files buy you
Rule files are the simplest thing in the shed with the biggest payoff.
A rules file is plain language in `.claude/rules/` that tells Claude how your project does things: what to always check, which patterns to follow, what never to touch. Rules without a path scope load when the session starts. Path-scoped rules load when Claude reads a matching file, so a PHP rule does not need to sit in the context while you edit CSS. I use them to keep things in line: security checks that always load, style and architecture rules scoped to the file types they govern. Write them like instructions to a new team member and they work. If you've never set rule files up, I went deeper in [teaching Claude your standards with rule files](/blog/ai-tools/claude-code-rule-files).
[Rule packs](/toolshed/rules/generic-rules) are downloads, not plugins, because they need to live in your repository. The plugin installer copies a plugin into Claude Code's cache; it does not merge a rules pack into your project's `.claude/rules/`. Take the generic pack, add your language pack, drop the files into `.claude/rules/`, adjust the path globs to your layout. If you'd rather not hand-tune anything, that's exactly what the rules generator is for.
## How to actually use this
There are two ways to install the tools covered here.
Plugins install through Claude Code's plugin system. Add the marketplace once and install what you need:
```
/plugin marketplace add imisic/claude-marketplace
/plugin install dev-workflow-forge@imisic
```
Swap the plugin name for whichever one you want. If the install summary says the plugin is already active, continue. If it says `Run /reload-plugins to activate.`, run that command.
Rule packs skip the install entirely: download the pack from its toolshed page, copy the `.md` files into your project's `.claude/rules/`, adjust the globs, done.
Plugin pages show the exact install command and a file-by-file view. Rule-pack pages pair the file view with a download button, so you can read everything before you grab it.
## The scanner that caught itself
The leak scanner found its first real problem in its own files.
Before anything leaves my machine, it runs through a [leak scanner](/toolshed/plugins/sanitize-public) that greps for the usual giveaways: private keys, tokens, internal hostnames, home paths, and my own list of client codenames. I pointed it at the whole batch. Then, on a whim, I pointed it at itself.
It was the worst offender in the set. To catch my private terms, it had them hardcoded. The list of client names it existed to find was sitting right there in its source, so shipping the scanner would have published the exact inventory it was built to protect.
> A tool that handles secrets isn't exempt from leaking them. It's the likeliest thing in your kit to do it, because the secrets are its whole job.
The fix was to split it. The shared version carries only generic patterns anyone would want (key shapes, token formats, private IP ranges), and my actual private terms live in a local file it reads at runtime and never ships. The public scanner catches the general leaks. My private list stays local.
## Take what's useful
It's all on the [toolshed](/toolshed), free, no sign-up, take what's useful and leave the rest. If you improve one of these, send me your version. That trade is how these get good.
This started as one weekend of packaging. Now it is six plugins, eight reusable skills, and a separate prompt shelf. There will still be rough edges, so if something breaks in your setup, send me the case.
## Sources
- [Discover and install prebuilt plugins through marketplaces](https://code.claude.com/docs/en/discover-plugins), Anthropic. Documents marketplace installation, activation summaries, and when `/reload-plugins` is required.
- [Plugins reference](https://code.claude.com/docs/en/plugins-reference), Anthropic. Supports the claim that marketplace plugins are copied into Claude Code's local plugin cache.
- [How Claude remembers your project](https://code.claude.com/docs/en/memory), Anthropic. Supports `.claude/rules/`, unconditional rules, path-scoped rules, and their trigger behaviour.
---
# My AI was smart. It just couldn't see my job.
**Author:** Ivan Misic
**Published:** 2026-06-25
**URL:** https://ivanmisic.net/blog/ai-tools/claude-obsidian-second-brain
**In plain English**
I built a private work memory by putting selected email, meeting transcripts, documents, and notes into one plain-text Obsidian vault that Claude Code can read. It prepares short meeting briefings, tracks decisions and promises, and links each summary back to the full note. I let scripts parse, match, and mask predictable data, then give the model the summaries and judgment. Paying a model to do a regex's job made the first version slower, costlier, and less consistent. It is a personal system with real limits: some data still reaches the model, the recorder is Windows-only, and the setup needs work before it fits another person's job.
I had too much work context scattered everywhere, so I built a private AI-readable work memory.
My problem was not that I needed more notes.
The important parts of work were scattered everywhere: email threads, meeting transcripts, project docs, quick notes, decisions, promises, follow-ups, and half-remembered conversations.
Claude was useful when I pasted the right context into it. But most of the time, the right context was buried somewhere else. It was in an old thread, a meeting transcript, a deck, a note I wrote too quickly, or a decision nobody had turned into a reusable artifact.
So I wired email, meetings, documents, and notes into one plain-text Obsidian vault that Claude Code can read. Not a chatbot with a nicer prompt. A private work memory that gives the model something useful to work with.
That helps with the everyday work that usually burns time in small hidden chunks:
- preparing for meetings without digging through old threads
- remembering who promised what and when
- tracking open action items across email and meetings
- finding the source behind a decision
- building project and people context automatically
- turning messy work artifacts into notes I can actually reuse
The model was already good enough. The missing piece was plumbing: getting the right work context into a place the AI could actually reach.
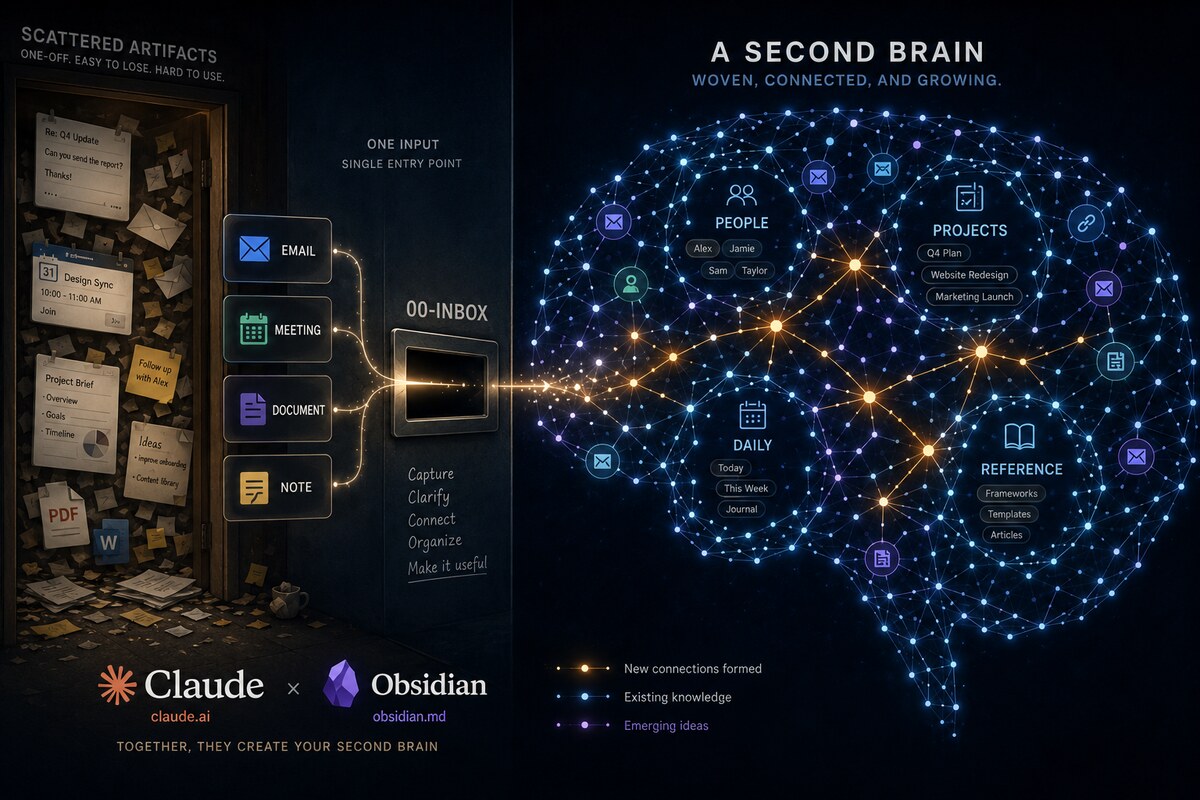
## The connector gap
Every AI keynote shows the same demo. The assistant reads your inbox, pulls up the right document, joins your meeting, and reminds you what you promised someone last Tuesday. It looks like magic. Then you close the tab, go back to your real job, and none of it is real.
The demos skip the boring part. That assistant works because someone wired it into a sandbox where the calendar, the mail, and the documents are one click away. You're watching the one example that was prepared to go smoothly, in an environment built to look simple. Real work is messier than the rehearsal. Plenty of workplaces, for good reasons, won't hand a personal script the keys to your mailbox, and the convenient note-takers want to ship your meeting audio to someone else's cloud. So the moment you care where your data goes, the easy connectors fall away, and you're left with a model that can reason about anything you paste in and reach nothing on its own.
So you get a strange split. The intelligence is racing ahead and getting cheaper by the month. The plumbing that connects it to your real life is barely moving.
> The bottleneck for useful AI is almost always the same: whether your data is somewhere the model can reach, and whether you know how to put it to work once it's there.
## So I started building one
Rather than wait for a vendor to ship the connector, I tried building one myself. No clever agent, no magic prompt, just a pipeline. It started as a weekend experiment and quietly turned into something I run most mornings.
Two tools do the heavy lifting, and both deserve a one-line introduction if they're new to you. **[Obsidian](https://obsidian.md)** is a free note app where every note is a plain markdown file on your own disk, linked to the others. The folder that holds all of them is called a vault, and that vault is my work memory. If you'd rather not start from an empty folder, the [vault template is on GitHub](https://github.com/imisic/claude-obsidian-vault). **Claude Code** is Anthropic's AI assistant that runs in your terminal and can actually read and write files on your machine, which is what lets it run the vault instead of just chatting about it. If you've never touched it, I wrote a [beginner's series on getting started with Claude Code](/blog/ai-tools/installing-claude-code-five-minutes).
The idea is simple. Everything from my work life flows into one folder Claude can read. Emails land there. Meeting transcripts land there. So do the documents I get sent and the half-formed notes I write to myself. Once the data sits somewhere the model can see, it can finally do the thing the keynote promised. The whole trick was getting it into the room.
Plain text matters more than it sounds. A file is the one format a human and an AI can both open, diff, and reason about without anything breaking, which is the same reason I [edit this site's content as files instead of running raw SQL against production](/blog/ai-tools/safe-way-edit-database-content-ai-coding-tools). No proprietary format, no lock-in. If every tool I use disappeared tomorrow, the Obsidian vault is still a folder of readable text.
## One door in, sorted folders out
Everything enters through the same door and leaves sorted. The daily cycle is short:
1. New emails, transcripts, documents, and quick notes all land in one `00-Inbox` folder.
2. Once a day, sometimes every second day when things are quiet, I run a single command. Claude reads the inbox and works out what each file is.
3. It cleans each one up, pulls out the people, projects, and action items, and writes a proper note.
4. The note goes to the folder it belongs in. The source leaves the inbox, which returns to empty.
The vault itself is a handful of numbered folders, each with one job:
| Folder | What lives there |
|-|-|
| `00-Inbox` | The landing zone. Every new file drops here first, then gets sorted out. |
| `01-Daily` | One note per day, topped with an AI-written morning briefing. |
| `03-Projects` | A file per project or workstream I'm tracking. |
| `04-People` | A file per person, created the first time they show up in my mail or a meeting. |
| `05-Interactions` | The processed meeting and email notes. The bulk of the vault. |
| `07-Areas` | Goals and dashboards, like a running list of open tasks. |
| `08-Reference` | Documents turned into markdown, so a slide deck becomes readable text. |
| `09-Archive` | Finished projects and past quarters, moved out of the way. |
My real vault as a graph. Each dot is a note, each line a link. What landed as scattered emails, meetings, and documents pulled itself into one connected web of people, projects, and decisions.
Zoom into any one of those dots and you get a file like this. A project note the pipeline keeps current, where every name and decision is a link back out into the graph:
```markdown
---
name: Self-Serve-Checkout
status: active
owner: "[[Ivan-Misic]]"
type: project
---
# Self-Serve-Checkout
## Key stakeholders
- [[Ivan-Misic]] (owner)
- [[Dana-Holt]] (sponsor)
- [[Marco-Ruiz]] (engineering)
## Open items
- [ ] [[Marco-Ruiz]] confirm the build is feature-complete [due:: 2026-05-16]
- [ ] [[Dana-Holt]] sign off on go/no-go criteria [due:: 2026-05-16]
## Decisions log
| Date | Decision | Owner | Status |
|-|-|-|-|
| 2026-05-15 | Target Monday, May 18 for go-live | [[Dana-Holt]] | confirmed |
```
The folders, the linking conventions, and the Claude Code skills that run them are the part I can hand over, and they're up on GitHub.
Getting the files: on the repo page, click the green Code button, then Download ZIP. If you'd rather use git, copy the clone URL from the same menu.
## Getting data out of a locked box
Two sources were hard, and both for the same reason: the easy path was off the table.
For email, wiring straight into the mailbox API wasn't realistic, so I used plumbing that was already there. One flow exports mail I flag by hand. A second watches messages tagged `VIP` by an Outlook rule. Both write plain text to OneDrive, which syncs to my laptop. A scheduled task moves the files into the vault every 15 minutes.
It felt like a downgrade until I realized plain text was the most reliable interface in the system. No tokens to refresh, no rate limits, no connection to drop at 2am. Each piece can fail on its own without taking the rest down. The fanciest part of the email path is a five-line script that tags messages I sent with a `SENT-` prefix, because the export leaves the `From:` field empty and that's the simplest way to tell which direction a mail went. The unglamorous fix kept winning.
Meetings were the other wall, and here I set myself a rule for the fun of it: capture them without handing the audio to someone else's cloud. Half the experiment was finding out whether that was even possible. It is. A small tray app records the call, transcribes it locally, and drops the text into the inbox. The audio never leaves the machine. On my Windows laptop with an NVIDIA RTX 4050 and 6 GB of VRAM, a one-hour meeting took roughly six minutes to transcribe locally. Speaker labeling and cleanup can add more time. The ones I don't catch that way go through a pocket recorder instead, and its audio does ride up to a cloud to get transcribed, the honest tradeoff for never losing a conversation I needed.
The output is just more text, dropped into the same inbox as everything else. The example below matches the shape of a real transcript, but the names and conversation are illustrative.
```
MeetingSubject: New Feature Kickoff
MeetingDate: 2026-05-15T09:00:00
Attendees: Ivan, Dana Holt, Marco Ruiz
MeetingType: sync
[00:00:12] Dana-Holt: So the whole feature, end to end. Can we have it live Monday morning?
[00:01:47] Marco-Ruiz: Monday's a little tight, but yeah, should be fine.
[00:02:39] Ivan: Let's get that on the record.
```
I have stopped treating Friday optimism as a Monday plan. The pipeline files the promise, links "live Monday morning" to Marco, and waits. A few Mondays later I can pull up the exact second optimism met a calendar. Remembering what everyone agreed to before they forget is one of the more useful things a setup like this does.
It's held together with tape in places. It's Windows-only because of how it grabs system audio, and it wants a decent GPU. But it runs every day, and the recordings stay mine.
> What finally made it work was boring plumbing nobody bothers to demo.
People call this kind of setup a second brain, and fair enough, that's what it is. But the name puts the emphasis in the wrong place. The brain was the part I could already buy; what I had to build was the nervous system connecting it to my actual job. If you're chasing a second brain of your own, spend your effort there.
## The lesson worth stealing: don't pay a model to do a regex's job
If you take one thing from this, take this. My first version had the AI do everything: parse email headers, match names to people, score which messages mattered, group threads, spot duplicates. It worked, sort of. It was also slow, expensive, and weirdly inconsistent from one run to the next.
Then it clicked. A language model does not need to read a `From:` line. Parsing that line is string manipulation, and a small Python function does it perfectly, every time, for free. So I moved all the deterministic work into scripts and left the model only the part it's good at: reading a messy thread and telling me what matters.
| Let a script do it | Let the model do it |
|-|-|
| Parse headers, strip signatures | Read a messy thread and tell me what matters |
| Resolve names and emails to people | Pull the real action items out of the language |
| Score relevance by rules, dedupe | Judge whether a borderline message is a big deal |
| Write files, mask private details | Write the one-line summary I'll actually read |
The result was faster, cheaper, and steadier, because the unpredictable component only touches the unpredictable problem.
> The rule that transfers to any AI project: hand the model the fuzzy, judgment-heavy part, and let plain code do everything else. Most "AI is too expensive" and "AI is too flaky" complaints are really that one mistake in disguise, paying a language model to do a regex's job.
The same idea splits the model's own work in two: a cheap model for volume, a smart one for judgment. The bulk work, like summarizing an email or a transcript, runs on a fast cheap model. The handful of jobs that need real judgment, like a weekly review or one-on-one prep, go to the strongest one. Most tokens run on the cheaper model, and the strongest one only appears when the work needs more judgment. My Claude plan currently costs about EUR 220 a month, roughly EUR 7 per calendar day or EUR 10 per working day, and this pipeline is only part of that usage.
There's a privacy dividend too, with an honest limit. Before the model reads an email, a script swaps email addresses, phone numbers, IPs, and anything else that scans as private in the body for tokens, and keeps the real values in a local map the AI never sees. It lowers what gets sent rather than removing it: the headers and the meeting transcripts still go through. The useful part is that the deterministic layer is also where I get to decide what the model is allowed to see in the first place.
## I decide what it pays attention to
The system only does the work I point it at. I get far too much email to turn all of it into notes, and trying would only bury the handful of things that matter. So I don't process the whole inbox. I point the real work at what I actually need to walk into prepared: a one-on-one, the weekly meeting, a workshop, a project or a person I'm tracking. I control what goes in and what I ask for back. And whatever comes back has to be a scan layer, never a wall of text. The morning briefing takes two minutes to read, and every line links to the full note if I want to dig in. The notes point to people and projects, which point back. I'm not building a novel I'll never reread. I'm building an index I can skim, then drill into when something catches my eye.
Here is what lands in the daily note each morning, names changed. Two minutes to read, and every line is a link into the full note behind it:
```markdown
# Friday, May 15
## Meetings today (1)
- New Feature Kickoff with [[Dana-Holt]] and [[Marco-Ruiz]]; agreed to target a Monday go-live. → [[2026-05-15-new-feature-kickoff|note]]
## Key emails
| | Topic | Summary | Source |
|-|-------|---------|--------|
| **!** | Launch checklist | [[Dana-Holt]] wants the go/no-go criteria locked before Monday; two items still open. | [[2026-05-15-email-launch-checklist|note]] |
## Decisions made
- Target Monday, May 18 for the feature go-live.
## Action items
**Mine**
- **!** Send the rollback plan to [[Marco-Ruiz]] before end of day → [[2026-05-15-new-feature-kickoff|Source]]
**Waiting on others**
- **!** [[Marco-Ruiz]] confirm the build is feature-complete → [[2026-05-15-new-feature-kickoff|Source]]
- **!** [[Dana-Holt]] sign off on the go/no-go criteria → [[2026-05-15-email-launch-checklist|Source]]
```
## What this won't do
Let me be honest about what this is: a personal system, not a product. It took months of nights-and-weekends iteration, and it's tuned to exactly one person's job. The meeting recorder is Windows-only and needs an NVIDIA GPU. I'm not packaging that recorder up to hand out, at least not yet. It's an approach more than a product, and nothing in it is exotic enough to stop you building your own. Speaker identification is good with three or four voices and gets confused in a crowd. Drop the whole thing into your own role and you'd spend a while reshaping the rules before it fit.
None of that bothers me. I wasn't building a company, just testing how far one person could get with off-the-shelf parts. The answer was further than I expected, and now I've got a connector nobody was selling.
## The moat was always the plumbing
The vendors will close this gap. A year or two from now the official connectors will exist, the policies will catch up, and some of what I built will look quaint. I'm fine with that. The work memory is a folder of plain text, so when a better connector shows up I just point it at the same files and keep everything I've already gathered. Waiting would have meant another year of an AI that couldn't see my job, when the data problem was solvable right now with tools I already had.
That's the part worth carrying out of here, and it's bigger than my vault. The intelligence is already here, cheap and getting better on its own schedule. What's missing is almost always the pipe between that intelligence and your actual work. Build the pipe, even out of plain text files and a scheduled task, and you stop waiting for permission to have the thing from the demo.
## Where this goes next
This post is the overview. I'll take the individual pieces apart in follow-ups and link them here as they land:
- **[Capture without an API](/blog/ai-tools/email-calendar-capture-without-api)**: pulling email and calendar out of a corporate mailbox into the local `00-Inbox` folder, with Power Automate and a scheduled task.
- **Private transcription**: how I turn meeting audio into text on my own GPU, with nothing uploaded. Still being written.
- **[Script-first](/blog/ai-tools/script-first-ai-pipeline)**: why the deterministic work runs as plain Python and the model only does the part it's good at.
- **[The skills](/blog/ai-tools/claude-code-skills-workflow)**: how one command a day is wired together as Claude Code skills and rules.
---
# How to organize small teams working with AI agents
**Author:** Ivan Misic
**Published:** 2026-06-17
**URL:** https://ivanmisic.net/blog/ways-of-working/next-team-three-people-pile-of-agents
**In plain English**
AI-assisted teams may need fewer handoffs because capable people can cover more of a workflow. I would not turn three people into a staffing rule. The real test is whether one small team owns the result, can make the necessary decisions, and stays responsible after release. Add shared support only when several teams keep solving the same supporting problem, and do not turn it into another approval step. Smaller senior teams also need a deliberate way to give junior people practical work, review, and progression.
AI-assisted teams can cover more of a delivery workflow with fewer handoffs, but smaller is not the point. Ownership is.
An [AWS re:Invent talk on team structures in an agentic world](https://www.youtube.com/watch?v=O7u6myBRsns) gave me a useful frame for this question. The talk proposes small pods of expert generalists supported by agents. I would not turn its team size into a staffing rule. My test is whether one pod can own a workflow, make the necessary decisions, and stay responsible after release.
## Put one workflow on the table
Imagine a customer onboarding workflow that starts with a completed application and ends with an active account. Product defines the rules, design shapes the screens, engineers build the flow, security reviews it, and operations receives the incidents. That is one customer journey split across several queues.
Specialists bring depth, but every handoff can lose context and make the work wait. We accepted that cost because one person could not cover enough of the workflow.
Agents change how much ground a capable person can cover. An engineer does not become a designer or a security specialist, but first drafts, tests, and supporting analysis no longer need their own queue every time. [Building the thing got cheap](/blog/ways-of-working/ai-made-building-easy-knowing-what-to-build); judgment about what to build and whether the result is any good stayed scarce.
The first question is therefore not how many roles to remove. It is whether a small group can take responsibility for the whole onboarding outcome without hiding the same queues inside a smaller box.
## Give the pod authority before cutting the team
Choose the smallest group that can own the workflow safely. For one workflow that may be three experienced people. For another it may require a specialist or a larger team.
Whatever the number, the pod needs one outcome, authority to change the workflow, access to the systems involved, and responsibility for what happens after release. If it must ask another team to approve every meaningful decision, it does not own the work.
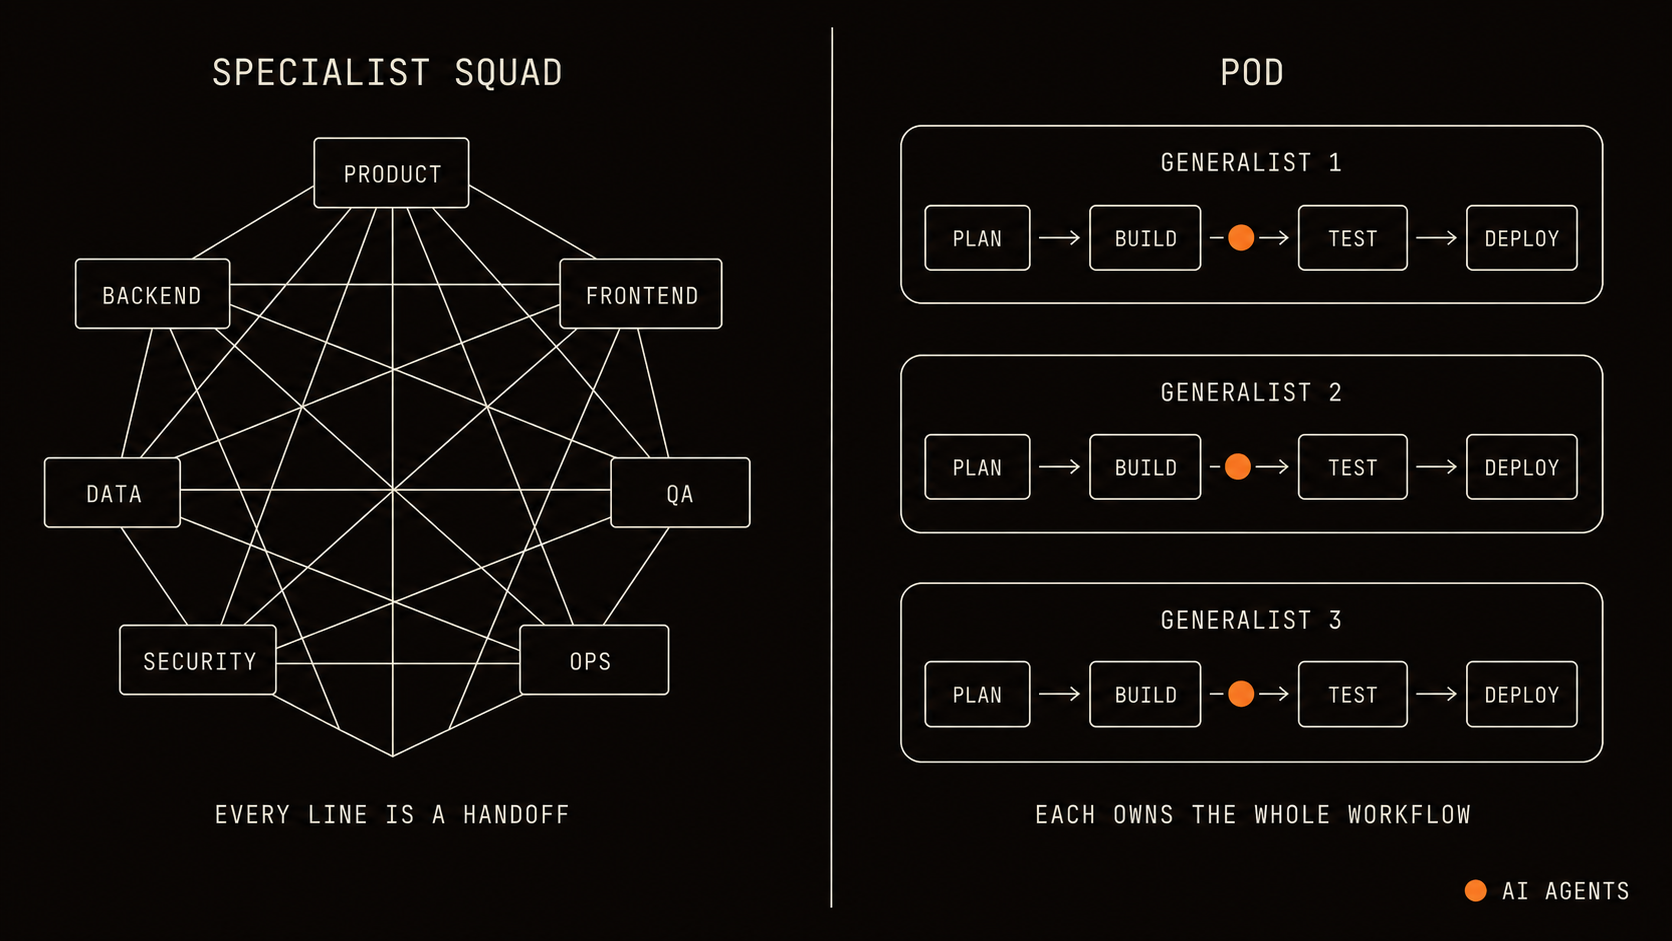
*Adapted from the team-shape comparison in the [AWS re:Invent talk](https://www.youtube.com/watch?v=O7u6myBRsns). I use it as an ownership model, not a fixed headcount.*
Thoughtworks calls the people who can work this way expert generalists. Its [Expert Generalists article](https://martinfowler.com/articles/expert-generalist.html) describes curiosity, customer focus, strong fundamentals, and comfort working outside one specialist area. Agents extend their reach, but the person still has to choose the work, check the output, and know when a specialist is needed.
I would hire for range and judgment, not only experience with the current framework. Agents are useful for the repeated preparation I have [argued they should take off your team](/blog/ways-of-working/ai-isnt-coming-for-your-team), but they do not replace accountability.
## Let operational needs shape the support
The real ownership test starts when onboarding breaks in production. A pod that built the flow already understands its rules, tools, data, and limits. A separate operations team first has to rebuild that context.
I would default to build it, run it for agent systems, then test whether it works. [DORA currently measures](https://dora.dev/guides/dora-metrics/) change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate. A smaller pod is useful only if the delivery and operational results improve.
Separate build and run responsibilities may still be required. Make that boundary explicit and give both sides enough access and context to investigate problems. Add shared support when several pods repeatedly solve the same supporting problem. Keep it as a service to the pods, not another approval gate.
| Model | What it is | Where it fits |
|-|-|-|
| Split build/run | Builders hand off to a separate operations team | Where separate responsibility is required and context can still be shared |
| Build it, run it | The pod operates what it ships | When the pod can own the service safely |
| Pods on shared support | Pods retain ownership while reusing common foundations | When repeated supporting work is slowing several pods |
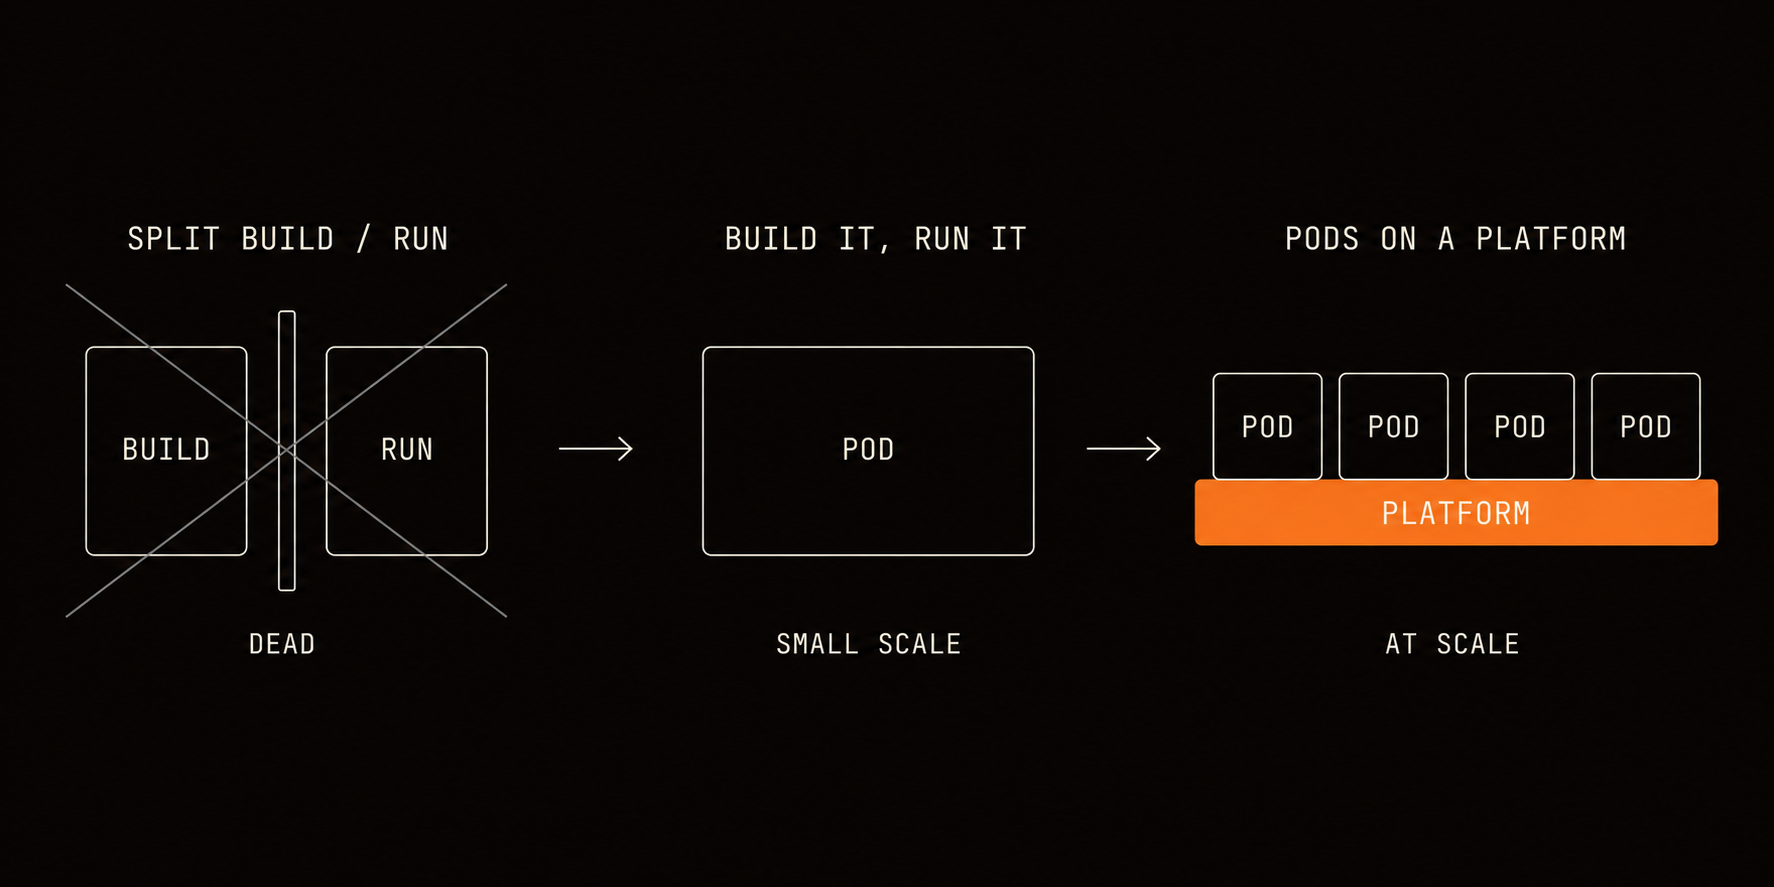
*These operating choices are adapted from the [AWS re:Invent framework](https://www.youtube.com/watch?v=O7u6myBRsns). The right one depends on the responsibility the pod can safely hold.*
## Do not spend the talent pipeline
Small senior pods have one serious limit. They do not develop junior people by themselves.
Senior people built judgment through practical work and review. If agents take over much of the work that used to provide that practice, companies need another route for juniors to gain experience. [Anthropic's labor-market research](https://www.anthropic.com/research/labor-market-impacts) found suggestive evidence of slower hiring for younger workers in highly exposed occupations. AWS CEO Matt Garman has also [argued that companies should keep hiring graduates](https://www.wired.com/story/the-big-interview-podcast-matt-garman-ceo-aws/), as removing junior roles weakens the future senior talent pool.
The pod is one delivery shape, not a template for the whole company. Use senior-heavy pods where they fit, and keep a deliberate path for practical work, review, and progression.
## Use an ownership test, not an org chart
Return to the hypothetical onboarding workflow. Can the pod change the rules and the implementation? Can it resolve an incident without waiting for a new queue? Does it control one customer outcome, rather than a list of steps owned elsewhere?
If the answers are yes, a smaller AI-assisted pod may work. If not, shrinking the team will not remove the handoffs. It will only make them harder to see.
## Sources
- [A leader's guide to advanced team structures in an agentic world](https://www.youtube.com/watch?v=O7u6myBRsns), AWS Events. Provides the attributed starting point for the small-pod and expert-generalist model adapted in this article.
- [Expert Generalists](https://martinfowler.com/articles/expert-generalist.html), Thoughtworks. Defines the breadth, depth, curiosity, and customer focus behind the role.
- [DORA's software delivery performance metrics](https://dora.dev/guides/dora-metrics/), DORA. Defines the five current delivery metrics named in the article.
- [Labor market impacts of AI: A new measure and early evidence](https://www.anthropic.com/research/labor-market-impacts), Anthropic. Reports no systematic rise in unemployment alongside suggestive evidence of slower hiring for younger workers in AI-exposed roles.
- [AWS CEO Matt Garman Doesn't Think AI Should Replace Junior Devs](https://www.wired.com/story/the-big-interview-podcast-matt-garman-ceo-aws/), WIRED. Records Garman's argument that removing junior roles would weaken the future talent pipeline.
---
# Four calendar days, one person, one full redesign
**Author:** Ivan Misic
**Published:** 2026-04-26
**URL:** https://ivanmisic.net/blog/ways-of-working/four-days-one-person-redesign
**In plain English**
I redesigned this site in four calendar days, changing the design system, public styling, admin area, build process, and hundreds of files. I estimated that a conventional team might need six to eight weeks for the same scope, but I did not measure that comparison. The speed depended on constant review and years of product and engineering judgment. Leaders still need to decide whether saved time should buy more output, better work, or work that was previously too expensive.
Anthropic shipped [Claude design](https://www.anthropic.com/news/claude-design-anthropic-labs), and the best way to evaluate a new tool is to put it to work on something real. So I pointed it at this site. Between April 23 and April 26, ivanmisic.net got a full redesign: new design system, new admin stack, new typography, new tokens, and two layout systems rewritten. Hundreds of files changed across the public site, admin, and build pipeline.
The point of this post is the calendar.
Four days. One person. The math is what matters.
## The design happened in two evenings
Before any of those commits existed, I spent two late evenings inside Claude design. Not Claude Code, the coding interface. The other one, where you describe a direction and watch it draw a real layout you can click around in.
> Quick honesty break. This was the launch version of Claude Design. I usually keep a tight cap on token spend, but I burned roughly USD 120 over my limit before I noticed. That amount came from the bill. Claude Design has improved since then and now uses much less of my allowance, so do not treat USD 120 as the current cost of doing this. The novelty got me.
I went in with almost nothing. "Dark theme, warm colors, help me redesign my site." Dropped a few screenshots of the old site. That was the brief. No moodboard, no tokens, no font picks.
For context, this is what I handed it. The v1 brutalist build, black canvas, Electric Lime accent, oversized outlined wordmark, monospace metadata everywhere:
What came back was three full directions, each with a Home, Blog index, Article, Tools, and Guides artboard:
- **A. Signal.** My old black-and-lime palette, evolved. Tighter type, editorial rhythm.
- **B. Atlas.** Swiss-editorial on warm paper. Serif display, library-catalog vibe.
- **C. Index.** Brutalist mono archive. Cool accent, terminal feel.
I told it I liked A and the typography across all three, but the lime green was tired and the palette needed warmth. From there, evening one became "make A warmer, lose the lime, push it toward something that doesn't feel like 2018." Evening two locked the system. Color tokens, typography pairing (Archivo Black plus Inter plus JetBrains Mono), the spacing scale, the component primitives. By the time I shut the PC down, I had a design brief I could hand to a developer. Said developer being, guess what... me. And the brief was about to feed straight into Claude Code.
That's already work I would normally split between a senior product designer and the engineer turning the direction into tokens and primitives. The planning scenario below includes both inside one six-to-eight-week estimate, alongside the rest of the build and QA.
## The four days
The work ran from April 23 to April 26. Thursday started with the design brief, implementation plan, migrations, and token files, then moved into the public redesign. Friday continued the public work. Saturday brought the build-system split and the admin migration, and the work finished Sunday. Four calendar days.
| Metric | Value |
|-|-|
| Days | 4 |
| Major systems rewritten | Public CSS, admin UI, build pipeline, design tokens |
The public site got a new design system end to end. Admin moved off the old patchwork CSS onto a Tailwind stack with its own component library. That admin migration is worth flagging on its own. Nobody sees admin except me, so the calculation was simple: why would I spend evenings hand-crafting a layout no user will ever load? I asked Claude Code, from my phone, what it would do with the admin if I let it pick. It came back with three mock variations. I picked one, we clarified a few specs (sidebar behavior, table density, a few component primitives), and the entire admin shipped in roughly three or four hours of me opening the phone, instructing, and watching it land. No laptop in the room.
The build system split into public and admin pipelines. Tokens were consolidated. Three independent dead-code passes ran. By the end, admin and public were speaking completely different design languages on purpose, so that future public redesigns wouldn't drag admin along.
This is more than a static personal site. It includes a blog, tools directory, guides, RSS-driven news aggregation, marketing calendar, admin notes, authentication, content sync, and a CMS. The full scope is in [How I Built This Site With Claude Code](/blog/ai-tools/how-i-built-this-site-with-claude-code#why-a-personal-site-has-this-much-code).
This is the part where someone usually asks "but is the code any good?" The honest answer is that I don't trust the first output of any AI tool, ever. The amnesia is real. Not full amnesia, just enough that things slip through, and the more you scale a build like this, the more obvious it gets. The mitigation is constant oversight, not a single review at the end.
What that looks like for me is one project-specific review skill with separate security, architecture, and code-quality passes, plus a stricter tech-debt mode. It runs on every meaningful chunk of work, not just at milestones. A separate learning workflow watches findings over time and proposes updates to the review rules, so the checks harden as the codebase changes. The final architecture review found no critical or high issues. I ran the same project-specific checks throughout the redesign, not only at the end.
## The mobile UAT was a screenshot loop
The most interesting part happened away from the PC, on my phone with Claude.
I would sit on the couch in the evening, open the redesigned site on my phone, find something that looked off (text overflowing on the guides hero, card padding wrong on the contact page, a hero animation that played too aggressively on small screens), and screenshot it. Drop the screenshot into Claude on the phone. Type "the breadcrumbs title is breaking mid-word on a narrow Android screen, fix the line wrapping." Send.
Claude would push the fix. I would refresh the page on my phone. Confirm it looked right. Move on.
It's mobile QA done by a single person, in real time, while watching TV. In this build, the screenshot loop cut a small UI fix from a ticket cycle to a few minutes of spotting, prompting, deploying, and checking.
## The math
For comparison, this is my rough estimate for the same scope in a conventional team. It is a planning scenario, not a measured counterfactual. The scope includes discovery and design exploration, a complete design system, three full directions, the public-site rebuild, an admin stack migration, a build pipeline split, and QA on real devices.
| Role | Effort | Covers |
|-|-|-|
| Senior product designer | ~25-35 mandays | Discovery, three direction explorations, design system, handoff |
| Frontend engineer | ~25-35 mandays | Public site rebuild, responsive work, animations |
| Backend / platform engineer | ~5-10 mandays | Admin stack migration, build pipeline split, token consolidation |
| QA engineer | ~5-7 mandays | Cross-device, regression, accessibility |
| Product manager (part-time) | ~5-10 mandays | Coordination, scope, sign-off across phases |
| Calendar time end to end | 6-8 weeks | Handoffs, reviews, sprint cadence |
Roughly 65 to 97 mandays of effort, on a 6-to-8-week calendar. The two evenings I spent inside Claude design alone replaced the discovery-plus-three-explorations chunk that usually eats two to three weeks of a senior designer's calendar. The Claude Code work compressed the rest.
And that's only the work itself. The table doesn't count what comes before any of it: the meetings about whether it should happen at all, the alignment on how, the politics of who owns it, the back-and-forth on when it ships, the steering committee, the prioritisation deck, the slack thread that goes for two weeks. In most organisations that pre-work is where the real calendar disappears, and the math on that side is even worse than the build side.
Plug in your own day rate and you'll land where you land. I'm deliberately not putting a euro figure on it. The cost depends on geography, agency versus internal, seniority mix, and how disciplined the team is. A leaner setup could do this cheaper. This is a personal site, not an enterprise rebuild, and I'm not pretending the risk profile is the same.
The point is the **calendar collapse**, not the invoice. I shipped the equivalent solo, in four days, around a full-time job.
The next conclusion is tempting, and wrong.
## What this isn't saying
This is not "we don't need designers and engineers anymore." I wrote about this in [AI Isn't Coming for Your Team. It's Coming for Their Busywork](/blog/ways-of-working/ai-isnt-coming-for-your-team) and [AI Made Building Easy. Knowing What to Build Just Got Expensive](/blog/ways-of-working/ai-made-building-easy-knowing-what-to-build), and the argument hasn't moved.
Worth saying plainly. Claude Code is a tool. Claude design is a tool. The "AI" label is doing a lot of cultural work right now because it sounds like a category, but in practice these are tools, and tools need an operator. The output is only as good as the person briefing it, reviewing it, and deciding when it's wrong. Without someone who can judge the output, the tool produces bad work faster. My experience helped me spot what was wrong and keep correcting it.
What I just did was possible because of years of product and engineering judgment. Knowing what to design. Knowing what good looks like. Catching when Claude's output is wrong, because it is wrong sometimes, and a constant review loop catches the things you wouldn't catch staring at the code yourself. Knowing the difference between code that ships and code that performs in production.
AI didn't replace those people. AI gave me a way to compress five people's *typing time* into four days. The thinking, the taste, the decisions, the ability to look at a result and know it was wrong before it broke production. All of it was still mine.
The thing AI replaces isn't the skill. It's the friction.
## The leadership question
If a senior practitioner can ship in four days what a team would spend two months on, that's a question about ship velocity, and what your organization does with it.
Before the options, the part organizations keep skipping. None of this lands by handing the team a Claude subscription and a budget for tokens. I would not expect that speed without trust, room to decide, and a workflow built around it. Senior people have to be allowed to make calls without ceremony. Reviewers have to trust that a constant-review loop replaces the gate, not bypasses it. Leaders have to stop measuring activity and start measuring outcomes. Without that shift, the tools just speed up the meeting tax.
With that shift in place, the headroom goes one of three ways. Most teams spend it shipping more: same people, more output, the velocity gain poured back into volume. That's the reflex. A smaller group aims for better instead, holding the scope flat but buying more iteration, more thoughtful design, more user research, fewer rushed compromises. The better bet is work that was always valuable but never worth the calendar cost.
I would not default to more output. Decide whether the saved time should buy more volume, better work, or work that was previously too expensive.
## What I am still figuring out
A few things I haven't fully resolved:
- The quality bar at velocity. The constant review loop caught real issues. Without it, this would have shipped a less honest version of itself. The discipline matters more, not less.
- The decision-making bottleneck. The faster the build, the more obvious it becomes that the slow part is figuring out *what* to build. That part hasn't gotten faster.
- The ergonomics. Four evenings (and one full weekend) in, my brain was tired in a different way than a normal sprint. Different cognitive load. I haven't decided yet what to do with that.
But the calendar is real. The commit count is real. The before and after is on the same domain you're reading this on.
We keep building tools to remove repetitive work. AI is the latest one. The useful question is what your team does with the time it gives back.
So the question isn't whether your team will use these tools. They will. The question is whether your team is set up to be productively, creatively lazy, and to spend the time it just bought on the work that actually moves something forward.
---
# A safe way to edit database content with AI coding tools
**Author:** Ivan Misic
**Published:** 2026-03-17
**URL:** https://ivanmisic.net/blog/ai-tools/safe-way-edit-database-content-ai-coding-tools
**In plain English**
I now edit large database fields through a pull, diff, push tool, after one stale export overwrote a newer admin edit. The tool should copy the current content to a local file, show exactly what changed, refuse to overwrite a newer edit, send the approved version through normal validation, and clear the application's cached copy after a successful save. Keep direct SQL for simple fields only when the application rules allow it.
## The "Just This Once" Trap
You're fixing a typo in a blog post. The word "recieve" is staring at you from the database. You know the fix. One `UPDATE` statement and it's done.
```sql
UPDATE blog_posts SET content = REPLACE(content, 'recieve', 'receive') WHERE id = 42;
```
It is fast, but it skips the controls that make the edit safe. That query skipped cache invalidation, left no audit trail, and if someone else was editing the same post, their changes just got overwritten with no warning.
## How I Learned This the Hard Way
I stopped using quick database edits after one stale export overwrote a newer change. I was editing a blog post through a quick MySQL dump-and-reload workflow. I had updated its meta description through the admin panel earlier that day, then my CLI push silently replaced it with the stale version I had exported hours before. I noticed three days later.
That's when I realized content fields aren't like other columns. A `status` field is a single value. A `published_at` date is simple to reason about. But a `content` field holding 2,000 words of markdown sits at the center of everything that can go wrong with a blind `UPDATE`:
**Your cache doesn't know.** Content fields have rendered HTML cached with a 24-hour TTL. Update the source markdown without clearing the cache, and the old version keeps serving. No error, no warning, just stale content.
**Your other edits don't know.** That admin panel update at 2:15pm? Gone. Your CLI push at 2:30pm replaced the whole record. You won't notice until days later when the wrong meta description is staring at you from Google's search results. Like mine was.
**You don't know.** You're overwriting the entire content of a published article without seeing what changed. Hope you didn't accidentally delete a paragraph.
Designing for AI-assisted editing and designing for safe editing are the same problem. Both want a local file to work with, a diff before committing, and protection against stale overwrites. Building for one gave me the other for free.
## The Pattern Claude Code Taught Me
I use Claude Code for most of the development on this site. And early on, I ran into an obvious friction point: Claude Code is brilliant at editing files. It can read them, do surgical `str_replace` operations on specific paragraphs, rewrite entire sections. But a 2,000-word blog post sitting in a MySQL `TEXT` column? It can't "see" that the way it sees a file.
I asked Claude Code about this, and it gave me the simplest possible advice: **extract, edit as file, write back.**
The quick-and-dirty version looked like this:
```bash
# Dump content to a file
mysql -u root -p mydb -e "SELECT content FROM blog_posts WHERE id=42" \
--raw --skip-column-names > /tmp/post-42.md
# ... let Claude Code edit the file ...
# Push it back
mysql -u root -p mydb -e "UPDATE blog_posts \
SET content=LOAD_FILE('/tmp/post-42.md') WHERE id=42"
```
The hack worked. Claude Code could read the file and edit the post using its normal workflow. The content was a `.md` file now, which is the format it is built for.
**Don't stop here.** I'm showing you this because it illustrates the idea, not because it's a solution. This approach has real problems:
- **No cache invalidation.** Your app is still serving the old rendered HTML.
- **No stale detection.** If someone edited the post while you were working on the file, `LOAD_FILE` just overwrites their changes silently.
- **`LOAD_FILE` needs special MySQL permissions** (`FILE` privilege and `secure_file_priv` configuration). On most setups, it won't even work.
- **No diff preview.** You're writing the entire file back blind.
This is the version that cost me that meta description. So I built a proper one.
## The Pull/Diff/Push Workflow
The concept stayed the same: extract to file, edit, write back. But I wrapped it in a CLI tool (`cli/content.php`) that handles all the things raw SQL can't.
Pull, edit, and review locally. Stale work stops; a safe push clears the cache.
### Pull: Database to File
```bash
php cli/content.php pull blog 42
```
This creates `storage/content/blog-42.md` with YAML frontmatter containing metadata and the raw markdown below it:
```yaml
---
id: 42
type: blog
title: "Your Article Title"
slug: "your-article-slug"
status: "published"
meta_title: "SEO Title Here"
meta_description: "SEO description here."
---
## Your Markdown Content
Starts here, exactly as stored in the database...
```
The tool records a timestamp in `.pulled.json`, tracking when you grabbed this snapshot. That timestamp becomes important later.
### Edit: Your Tool, Your Way
The `.md` file is just a file. Edit it in VS Code, Vim, or hand it to Claude Code. The frontmatter fields are editable too. Change the `meta_description`, update the `title`, fix the content, all in one place.
One design choice worth mentioning: the CLI normalizes `\r\n` line endings to `\n` on both pull and push. That might seem like a minor detail, but when your editing tool runs on WSL and produces Windows-style line endings, every single line shows up as "changed" in the diff without it. Normalizing the line endings keeps the diff limited to the changes I actually made.
### Diff: See Before You Commit
Before pushing anything, preview exactly what changed:
```bash
php cli/content.php diff blog-42.md
```
The output shows metadata changes and a line-by-line content diff, color-coded in the terminal:
```
[meta_description]
- DB: Old description that was too long.
+ File: Concise new description under 160 chars.
[content]
Summary: 3 changed, 1 added, 0 removed line(s)
- The old paragraph with the typo recieve
+ The fixed paragraph with receive
```
No surprises. You see exactly what you're about to change before it touches the database.
### Push: File to Database (With Safety Nets)
```bash
php cli/content.php push blog-42.md --confirm
```
The `--confirm` flag is intentional friction. Without it, the tool just shows the diff and stops. You have to explicitly opt in to the write.
But the real safety feature is **stale edit detection**. Remember that timestamp from the pull step? Before pushing, the CLI compares it against the current `updated_at` in the database. If someone (or something) modified that record since you pulled it, the push fails:
```
[ERROR] Stale edit detected!
Pulled at: 2026-03-15 14:00:00
DB updated: 2026-03-15 14:15:00
Content was modified since you pulled it.
Pull again to get the latest, or use --force to overwrite.
```
This catches the exact scenario that bit me. The `--force` flag exists as an escape hatch, but you have to consciously choose to use it.
After a successful push, the tool clears the relevant caches automatically. Blog posts clear `blog_*` and `home_*` caches. Tools clear `tools_*` and `home_*`. No manual cache busting required.
Simple metadata fields like `status`, `title`, and `published_at` are still fine for direct SQL. The workflow is for large text fields with cached renders and downstream dependencies.
## The Architecture Under the Hood
The CLI is a single PHP file, currently about 650 lines. It handles the file workflow and stale check, then passes the changes to `ContentEditingService`, which routes each content type through its normal mutation service. Validation, publish transitions, generated assets, and cache invalidation stay in the same path as admin edits without requiring an HTTP request.
The content type configuration is declarative. Adding a new content type means adding one entry:
```php
const TYPE_CONFIG = [
'blog' => [
'model' => BlogPost::class,
'content_field' => 'content',
'metadata_fields' => ['title', 'slug', 'excerpt', ...],
'title_field' => 'title',
],
// Add new types here
];
```
Cache invalidation belongs to the content-type services, so the CLI does not maintain a second cache map.
The whole tool took an afternoon to build. The raw MySQL version worked in ten minutes. The difference is stale detection, cache invalidation, and diff preview: three features that prevent every "oh no" moment the hack would eventually cause. The number of "I just need to run a quick UPDATE" moments it's prevented since? Lost count.
## Making Claude Code Enforce It
A CLI tool is only useful if you remember to use it. I kept catching myself reaching for a quick `UPDATE` on a content field. Old habits.
The fix was making Claude Code itself enforce the workflow. In my project, I have a [skill](https://docs.claude.ai/en/docs/claude-code-skills) (a reusable instruction file) that Claude Code loads whenever content editing comes up. The skill says: "When editing large text fields (blog content, tool description, guide description), ALWAYS use `cli/content.php` pull/edit/push workflow. Never use raw SQL UPDATE on content fields."
That same rule lives in the project's `CLAUDE.md` file, the instruction document Claude Code reads at the start of every session. Between the skill and the project rules, Claude Code won't let me take shortcuts even when I ask nicely. It pulls the content to a file, makes the edits there, shows me the diff, and pushes with the safety nets intact.
The useful part is that Claude Code now enforces the same constraint on me. The skill handles the "how" (which CLI commands to run, in what order), and the project rules handle the "when" (any time a content field is involved, no exceptions).
If you're setting up something similar, the key is making the rule absolute. Not "prefer the CLI tool" or "consider using the workflow." Just: these fields are off limits for raw SQL. Period. Claude Code respects hard rules better than suggestions.
---
# Klarna's AI customer service: reading cost and quality together
**Author:** Ivan Misic
**Published:** 2026-03-11
**URL:** https://ivanmisic.net/blog/ways-of-working/klarna-ai-u-turn-isnt-failure-story
**In plain English**
Klarna reported faster support, workload equivalent to hundreds of agents, and stable consumer satisfaction, while its CEO later said its customer-service cost-cutting went too far. Public evidence does not show a satisfaction collapse, complete abandonment of the assistant, or a proven recovery model. Read resolution time, repeat contact, escalation, satisfaction by case type, and cost together. Define high-risk cases and the human handoff before scaling automation, rather than waiting for one public metric to reveal the boundary.
Klarna's contradiction is the useful part: it reported stable satisfaction, then its CEO said its customer-service cost-cutting had gone too far.
The company says its assistant handled most support chats with no drop in consumer satisfaction. The CEO's later admission about cost-cutting makes this more useful than another argument about whether AI won or failed.
## What Klarna reported
When Klarna [launched its OpenAI-powered assistant](https://openai.com/index/klarna/) in 2024, it reported:
- 2.3 million conversations in the first month
- two-thirds of customer-service chats handled by the assistant
- average resolution time reduced from 11 minutes to under 2
- service in 35 languages
- work equivalent to 700 full-time agents
- an estimated USD 40 million profit improvement for 2024
“Work equivalent to 700 agents” does not mean Klarna replaced 700 named people with a chatbot. I would describe it as workload equivalence, not 700 people replaced.
Klarna's [2025 annual report](https://www.sec.gov/Archives/edgar/data/2003292/000162828026038366/annualreport2025.htm) later said the assistant handled 80% of customer-service chats with no drop in consumer satisfaction. The same report linked AI adoption and restructuring to a 49% headcount reduction and a 3.6-fold increase in revenue per employee since 2022.
The efficiency numbers are good, but they are Klarna's own. They show what the company measured and chose to publish.
## Then the CEO said cost-cutting went too far
Sebastian Siemiatkowski [later said](https://www.bloomberg.com/news/articles/2025-05-08/klarna-turns-from-ai-to-real-person-customer-service) that the company's customer-service cost-cutting push had gone too far. Klarna also [started talking about giving customers a clearer option to reach a person](https://techcrunch.com/2025/06/04/klarna-ceo-says-company-will-use-humans-to-offer-vip-customer-service/).
That does not mean Klarna automated support, watched satisfaction collapse, and hired everyone back. The public evidence does not show that.
Klarna did not abandon the assistant. Its filing says usage increased. The public record also does not support precise claims about an NPS collapse, hundreds of agents returning, or a proven recovery under a new three-tier model.
So I would keep the contradiction visible:
> Klarna reported stable consumer satisfaction while its CEO said the customer-service cost-cutting push had gone too far.
Both can be true if the two statements use different measures, periods, customer groups, or definitions of quality. Without the underlying measurement method, we do not know.
## One support metric cannot carry the decision
Resolution time is useful, but it measures speed. It does not tell you whether the customer had to contact support again, whether the issue was solved correctly, or whether a difficult case reached the right person.
The same problem applies to a single satisfaction score. An average can stay stable while a smaller group with complex problems gets a much worse service.
I would not judge support automation on resolution time alone. Can we check repeat contacts, escalation, satisfaction by case type, and cost together?
| Measure | What it tells you |
|---|---|
| Resolution time | How quickly the interaction closes |
| First-contact resolution | Whether one interaction solved the issue |
| Repeat contact | Whether the customer had to come back |
| Escalation rate | How often the system needed a person |
| Satisfaction by case type | Which journeys improved or became worse |
| Cost per resolved case | Whether the financial gain survives rework |
If speed improves while repeat contact and escalations rise, the automation may be moving work rather than removing it.
## Draw the automation boundary before launch
Routine tracking questions and simple status updates are different from disputes, fraud reports, account access, or a payment problem that has already failed twice.
I would not start by automating every case and wait for complaints to show where the boundary belongs. Define the high-risk cases first, send those to people, and use AI to help the agent gather context or prepare an answer.
The handoff must also work in practice. A human option hidden behind repeated bot replies only adds another queue.
## Efficiency still matters
The “AI failed” version ignores Klarna's financial results. The company reported [USD 1.082 billion in Q4 2025 revenue](https://investors.klarna.com/News--Events/news/news-details/2026/Klarna-Accelerates-U-S--Growth-and-Delivers-1bn-Revenue-Driven-by-Rapid-Banking-Service-Adoption/default.aspx), 118 million active consumers, and 966,000 merchants.
Revenue, active consumers, and merchants all increased while the AI programme continued. That rules out the simple story that it was a commercial collapse, but it does not establish which part caused the growth.
Cost reduction and service improvement can overlap, but they are not the same outcome. A product leader needs to know which one a dashboard is showing.
## What I would take from the case
I would make four decisions from this case:
1. Describe workload equivalence as workload equivalence, not jobs replaced.
2. Read speed, satisfaction, repeat contact, escalation, and cost together.
3. Decide which cases require human judgment before scaling the automation.
4. Keep an obvious route to a person when the automated path fails.
My takeaway is simpler: read efficiency and service quality together. A clean public story is not enough.
## Sources
- [Klarna](https://openai.com/index/klarna/), OpenAI. Reports the assistant's first-month volume, share of chats, response-time change, language coverage, and estimated workload.
- [Klarna Group plc 2025 Annual Report](https://www.sec.gov/Archives/edgar/data/2003292/000162828026038366/annualreport2025.htm), Klarna. Reports the assistant's service share, consumer satisfaction, headcount change, revenue per employee, customers, and merchants.
- [Klarna Slows AI-Driven Job Cuts With Call for Real People](https://www.bloomberg.com/news/articles/2025-05-08/klarna-turns-from-ai-to-real-person-customer-service), Bloomberg. Reports Siemiatkowski's view that the customer-service cost-cutting push went too far.
- [Klarna CEO says company will use humans to offer VIP customer service](https://techcrunch.com/2025/06/04/klarna-ceo-says-company-will-use-humans-to-offer-vip-customer-service/), TechCrunch. Records the plan to restore more human support while retaining AI.
- [Klarna Accelerates U.S. Growth and Delivers $1bn Revenue Driven by Rapid Banking Service Adoption](https://investors.klarna.com/News--Events/news/news-details/2026/Klarna-Accelerates-U-S--Growth-and-Delivers-1bn-Revenue-Driven-by-Rapid-Banking-Service-Adoption/default.aspx), Klarna. Supports the reported revenue, customer, merchant, and efficiency figures.
---
# The permission tax: how approvals slow product teams
**Author:** Ivan Misic
**Published:** 2026-02-24
**URL:** https://ivanmisic.net/blog/ways-of-working/permission-tax-growing-teams
**In plain English**
In my FAQ project, the build took one month and approval took another three to four. That is one case, not a universal ratio. Measure the full time from an agreed idea to customer use, remove approvals that cannot name the risk they control, and reduce scope before assuming another hire will make delivery faster. I expect some smaller companies to test AI workflows sooner because they have fewer dependencies, but that is a bet to measure, not proof that small teams always win.
It took me one month to build an FAQ solution for the support pages.
Getting permission to put it live took another three to four months.
The technical work was the short part. The decision took months.
The organization had enough capacity to build the feature. It did not have a short path to approve it.
## The math doesn't work
The coordination cost becomes clearer as the company grows. In a team of 8, you have an idea Monday morning and you're testing it by Wednesday. Maybe you check with one or two people. Maybe you run a small test and show the results.
In a team of 80, the same idea may need a proposal, reviews from three other teams, a planning session, and an executive decision. Each step can be reasonable on its own, but together they can make the original context stale before approval arrives.
In my FAQ case, one month of building was followed by three to four months of approval.
This is what I call the **permission tax**. It grows when more people and teams need to approve the same decision.
My FAQ case, shown at the upper end of the range: one month to build and about four months to approve. The team paths show the 8-person and 80-person comparison above, not an industry benchmark.
## More people create more coordination
The problem is usually not the people. It is the number of dependencies around every decision.
Adding people increases the number of possible communication paths. A team of 5 has 10 possible pairwise links. Add a sixth person, and there are 5 more. Those links do not all need active management, but each real dependency between teams needs an owner and a way to resolve decisions.
Some friction is structural, but some comes from people protecting their ownership and influence.
When a small team starts working in an area owned by another team, the discussion often moves from the customer problem to ownership. People want to understand who will decide and what remains under their control.
This changes who gets to decide, so deal with that concern directly.
The decision then becomes a negotiation about ownership and consultation. The customer outcome can easily become secondary.
> People who were trusted to decide quickly in a small company can struggle when the same decisions later require several approvals. The behaviour stayed the same, but the organization around it changed.
## The hiring trap
When a product team expands into a new area, its first proposal is often to hire more people.
The sequence can look like this: write a hiring plan, get the budget approved, recruit, then spend the first weeks giving new people access, context, and introductions.
The new team can arrive before the work has moved past the proposal. Now you also need to agree who owns what.
By then, onboarding and new dependencies can delay the work the hiring plan was meant to speed up.
I would first reduce the scope and refocus the existing team. I've [written before about why half your roadmap probably doesn't matter](/blog/product/laundry-list-trap-prioritization). Do less with the people you have, but do it with the speed and autonomy that made them effective in the first place. Adding people does not fix a slow decision process. It gives the same process more dependencies to manage.
## The process symptom
You can diagnose the permission tax by looking at what your teams actually spend time on. Warning signs include:
- Documenting how teams should work together
- Creating and reviewing "ways of working" agreements
- Running workshops to align on process before any work starts
- Building elaborate approval chains for things that used to be informal
- Standing up governance forums and steering committees
If this takes more time than customer work, the process is preserving the problem.
Process is supposed to remove ambiguity so teams can move faster. When process becomes the work itself, when teams spend more time negotiating how to work than actually working, something has gone wrong.
> If teams spend more time documenting how to work than building for customers, I would reduce the process before adding another rule.
Process becomes a problem when it delays the decision it was meant to support. Another alignment meeting can add delay without changing the outcome.
## Why this matters right now
My bet is that AI will make the permission tax easier to see. When execution gets faster, each approval step takes a larger share of the timeline.
A large company may need security, legal, vendor, and governance reviews before testing an AI workflow. Those controls can be necessary. The problem is treating every experiment as if it carries the same risk.
I expect some smaller companies to test AI workflows sooner because fewer teams need to approve each experiment. In those cases, the advantage is a shorter decision path, not better technology or smarter people.
## Fighting back
Start by measuring where the time goes.
**Measure time-to-ship, not time-to-build.** I would measure the full time from an agreed idea to customer use, not only development velocity. In my FAQ case, one month of building was followed by three to four months of approval.
When a team wants to expand, challenge the assumption that more people is the answer. What could you stop doing instead? What could you simplify? A focused team doing fewer things well can outperform a larger team spread across too many priorities. **Descope before you hire.**
**Protect team autonomy.** Some approvals are necessary, but each one should have a clear risk it controls because approval steps add time and dependencies. I would default to team autonomy when nobody can name that risk.
My bet is on companies that let a team test a good idea without months of approval. Budget and headcount matter less when the decision process blocks the work.
---
# Multi-market apps: what central and local teams should own
**Author:** Ivan Misic
**Published:** 2026-02-21
**URL:** https://ivanmisic.net/blog/digital-transformation/multi-market-apps-central-local
**In plain English**
Use one shared app codebase, but deploy it separately in each market so local teams can set the language, prices, campaigns, regulatory details, and connections to their own systems. Central owns the shared code, core journeys, design rules and release calendar. It also defines the shared way the app asks billing and other local systems for data. Write down who decides what. Central makes the final call after consulting the markets. A market can deviate when regulation requires it or the shared approach is harming customers.
Multi-market products need one codebase with clear room for local differences. Central needs to control the shared product, while each market needs enough flexibility for its customers and regulations.
Both sides are right about part of the problem. Keep one codebase, then write down what central owns and what local can configure.
## The Three Failure Modes
I would avoid three operating models.
### Total Central Control
Headquarters builds the app, gives local markets limited configuration, and leaves their requests in a backlog that rarely moves.
The risk is that the app works for markets whose needs happen to match what central built, and poorly everywhere else. Local adoption suffers. Workarounds appear. Eventually, a market asks for its own app and the portfolio starts fragmenting again.
### Total Local Autonomy
Each market builds their own app. Central provides guidelines that nobody follows. Local teams optimize for their market and ignore the bigger picture.
The risk is a portfolio of separate codebases, agency relationships, and user experiences. Shared features get built several times, while customers get a different product depending on the market.
### Central Build, Local Fork
Central builds the platform and gives full code access to local teams. This looks workable at first because the markets share a base and can still make local changes. The risk starts when local teams modify core components, add market-specific exceptions, and move away from the original architecture. As the forks drift, each central upgrade becomes an integration project of its own. A market can eventually stop taking central updates and return to building for itself, now with the added complexity of a shared origin.
I would avoid all three. The better model is a negotiated middle with clear boundaries between what stays central and what markets can change.
The first three models fail in different ways: too little local flexibility, duplicated local products, or forks that drift apart. One codebase with local configuration, standardized adapters, and separate deployments keeps the shared core intact while connecting to each market's systems.
## The One Codebase Model
The [app consolidation playbook](/blog/digital-transformation/app-consolidation-playbook) leads to an operating model I would use: one shared codebase with local deployments.
| Responsibility | Central Team | Local Team |
|---------------|--------------|------------|
| App codebase | Owns and builds | Consumes |
| UX patterns & components | Defines and maintains | Uses as-is |
| Core journeys | Designs and implements | Configures content |
| API contracts | Defines specification | Implements against local backends |
| Release management | Controls calendar | Fits requests into calendar |
| Content & translations | Provides framework | Manages locally |
| Campaigns & promotions | Provides CMS | Controls configuration |
| Product/pricing displays | Provides components | Populates data |
The app is built once by a central team. It's deployed separately in each market, with local configuration and backend connections. The customer sees an app that feels local (local language, local pricing, local campaigns) but under the hood, it's the same codebase everywhere.
## The Contract That Makes It Work
This model requires a clear written contract between central and local teams. If the contract stays informal, every disagreement turns into a new debate about whose requirements take priority.
> The critical rule: local teams describe the problem, central teams design the solution. Local teams often arrive with specifications: "we need a button here that does X." Central needs the discipline to ask "what outcome are you trying to achieve?" and the authority to propose a different solution if appropriate.
Local teams agree to:
- Raise demands as business outcomes, not technical specifications
- Accept central's solution design for core journeys
- Not request custom UX that breaks the design system
- Implement the standardized API layer against their backends
In return, central teams agree to:
- Consult local teams before finalizing journey designs
- Provide configuration options for genuine local needs
- Treat reuse across markets as one input alongside regulation, customer harm, revenue, and urgency
- [Maintain backwards compatibility](https://google.aip.dev/180) when rolling out changes
## What Stays Consistent
Some things shouldn't vary by market. A shared baseline can reduce duplicate work and improve quality.
**Navigation and information architecture.** Where things are in the app should be the same everywhere. Customers moving between markets shouldn't get lost.
**Core journeys.** Login, payment, and support flows should work the same way. These are table stakes, not differentiators.
**Visual design system.** Colors, typography, spacing, and component behavior should follow the same rules. Local teams can configure content within components, not redesign the components. When serving multiple brands, this means a theming layer: same components and logic, different brand skins applied through design tokens or configuration.
Error handling, accessibility, and platform compliance also need one shared baseline. Markets should not invent their own error states.
## What Can Vary
Some things need real local flexibility. Trying to force consistency here can hurt adoption.
**Language and locale.** Obviously. But also date formats, number formats, currency displays, and cultural conventions around formality.
**Products and pricing.** Each market has different products with different structures. The app needs to display whatever the local product catalog contains.
**Campaigns and promotions.** Marketing needs to run local campaigns without waiting for central releases. This requires a CMS or configuration system that local teams control.
Regulatory requirements are the clearest case: data consent flows, ID verification, and payment regulations vary by country and require local implementation. And not every feature makes sense in every market, so you need feature flags to enable or disable capabilities per market.
## The API Abstraction Layer
Each market usually has different billing, CRM, and product catalog systems. If the app needs to integrate directly with all of these, you're building multiple apps wearing one skin.
The solution is an [API abstraction layer](/blog/digital-transformation/dont-replace-billing-system). A standardized contract that the app talks to, regardless of what's underneath.
The central team defines the API specification: what endpoints exist, what data they return, what operations they support. Every market implements this specification against their local systems.
The app doesn't know or care whether Market A uses SAP and Market B uses Oracle. It calls the same endpoints. Local teams handle the translation.
This requires governance. The API spec can't change on a whim. It affects every market. Changes need a review process with local input. Breaking changes need migration paths.
Standardized APIs can reduce the integration work for the next platform because the new channel can use the same contracts. Microsoft's [anti-corruption layer guidance](https://learn.microsoft.com/en-us/azure/architecture/patterns/anti-corruption-layer) also lists the cost: extra latency, maintenance, monitoring, and data-consistency work. It pays off when the repeated integration work is larger than that overhead.
## The Governance Model
Someone still needs authority to decide when central and local teams disagree. Feature requests go through a [prioritization process](/blog/product/laundry-list-trap-prioritization). Reuse across markets should increase priority, but it is one input. Regulation, customer harm, revenue, and urgency can still make a single-market need come first. Design decisions sit with central. It owns the UX patterns and journey flows, while local customizes content within them. If there's a dispute, central wins, unless local can show a regulatory or market-specific need.
Timelines follow a similar principle: central controls the release calendar, and local requests fit into that calendar, not the other way around. Emergency local needs get escalation paths, but the default is central's schedule. Central owns the API contract. Affected markets review changes and get a migration path. Central can decide after consultation, but it should not ship a breaking change without a workable transition.
This governance isn't democratic. Central has more authority than local by design. Local teams still get genuine input, and they can block a release when it would violate regulation or create clear harm in their market.
## The Team Structure
This model needs specific team structures to work. The central team owns the product end-to-end: engineering, design, product management, architecture. It makes the roadmap decisions and builds the app. Local teams need product owners who understand the market, technical liaisons who implement the API layer, and content managers who handle localization. They don't build the app, they configure and integrate it.
Connecting the two is shared governance: architects who design the API contract, a product council that prioritizes cross-market features, and regular sync meetings to align on roadmap and technical decisions.
The balance matters. If central is too small, it can't keep up with local demands. If local teams are built to deliver independently, the model invites them to create their own solutions. The central team should be large enough to drive the roadmap, with local teams focused on input, configuration, and integration.
## The Hard Conversations
Even with good models, some conversations stay hard.
"**Our market needs this feature urgently.**" Maybe. Or maybe it's an edge case that doesn't justify central investment. Someone has to make that call, and sometimes the answer is no.
"**The central solution doesn't work for us.**" Sometimes valid (genuine market difference), sometimes not (preference disguised as necessity). Someone has to distinguish.
"**We're launching slower because of central dependencies.**" A shared roadmap can make one market wait longer. The model only earns that delay if reuse across markets reduces duplicate delivery and operating cost. Track both sides of the tradeoff.
"**Central doesn't understand our market.**" Make them understand. The model requires local input to work. If central isn't listening, that's a governance failure to escalate.
## The Results
When the model works, one shared capability can serve several markets without being rebuilt for each one.
The model is designed to reduce duplicate builds, apply shared fixes once, and give a new market an existing product to start from. Track those outcomes directly, because one codebase does not guarantee them on its own.
Measure the time needed to launch a market, the share of capabilities reused without local code changes, the number of local exceptions, and the cost of maintaining the adapters. Those numbers tell you whether the operating model is working better than another reorganization slide.
Customers should not have to care how many markets share the codebase. They should see a product that fits their language, products, prices, and rules. That's the goal.
---
*Write down what local teams can decide and where central has final authority. Trust alone will not settle the next disagreement.*
## Sources
- [Anti-Corruption Layer pattern](https://learn.microsoft.com/en-us/azure/architecture/patterns/anti-corruption-layer), Microsoft. Supports standardized translation boundaries between systems with different semantics and the associated latency, maintenance, monitoring, and consistency costs.
- [AIP-180: Backwards compatibility](https://google.aip.dev/180), Google API Improvement Proposals. Supports treating APIs as contracts and preserving source, wire, and semantic compatibility for existing clients.
---
# Choosing what to build when AI makes prototyping cheaper
**Author:** Ivan Misic
**Published:** 2026-02-19
**URL:** https://ivanmisic.net/blog/ways-of-working/ai-made-building-easy-knowing-what-to-build
**In plain English**
AI made more ideas cheap enough for me to test, but this project does not prove that software costs are approaching zero or that one small team replaces every larger one. The harder skill is defining the user, outcome, constraints, evidence, and stopping condition clearly enough to test whether the work matters. Published productivity results vary by task and worker context. Start with one repeated piece of work, specify the expected result, let AI produce a version, and check whether it met the conditions.
AI makes execution cheaper, but it also exposes weak decisions faster.
I [built this website](/blog/ai-tools/how-i-built-this-site-with-claude-code) with AI as my primary engineering partner. It includes a design system, CMS, content tools, and the normal plumbing behind a working site. Work that I would once have scoped as a small agency project took me weeks.
That proves the change for this project. It does not prove that every three-person team can now replace fifteen people, or that software costs are approaching zero. The task, people, quality bar, and operating model still matter.
What changed for me is simpler: more ideas are now cheap enough to test. That moves the bottleneck from “can we build it?” to “should we build it, and can we explain what good looks like?”
## Cheap prototypes create more demand
I have watched organizations run important processes through spreadsheets because a proper tool was too expensive to justify. Operations teams reconcile data by hand. Product teams copy the same information between systems. A small internal need waits behind a large platform roadmap.
When a prototype becomes cheap enough to test in days, more of those processes become candidates for a small purpose-built tool.
That does not mean every workaround deserves software. Cheap building can also produce more tools nobody needs. The old budget acted as a brake, even if it was a frustrating one. Stakeholders had to align because getting the decision wrong consumed real money and months of work.
AI weakens that brake. You can now be wrong faster.
Anthropic's [2026 agentic coding research](https://resources.anthropic.com/hubfs/2026%20Agentic%20Coding%20Trends%20Report.pdf) found that some AI-assisted engineering work covered tasks that otherwise would not have been done. I think that direction matters more than one headline productivity multiplier. Lower execution cost creates demand for work that previously stayed below the priority line.
## Building got cheaper. Thinking did not.
“Improve onboarding” is not a specification. Neither is “build what our competitor has.” Both leave the important decisions hidden inside a short sentence.
Someone still needs to define:
- which user has the problem
- what should change for that user
- which constraints the solution must respect
- how the team will know whether it worked
- what would make the idea not worth continuing
AI can help explore those questions, but it cannot own the decision. If the brief is vague, the output can look complete while solving the wrong problem.
> The bottleneck is moving from “can we build it?” to “can we define and test the right thing?”
The cost of one bad prototype may be small. The cost grows when teams mistake quick output for evidence, add it to production, and create another thing to support.
## The split I see in teams
One group uses AI to execute the same work a bit faster: better first drafts, quicker analysis, more autocomplete. Useful, but the workflow stays the same.
Another group starts from the system and outcome. They ask which work should disappear, which decision needs better evidence, and which repeated process could become a tool. AI is part of the implementation, not the goal.
There is usually a messy phase between the two. People get access to a capable tool and create everything they can think of. The first prototype feels productive because something exists. But output is not value.
Generating ideas is easy. Choosing which one deserves time is the real work.
This split does not follow seniority. Experience helps with judgment, but only if the person is willing to change the process around that judgment. A senior title does not make a vague instruction clearer.
## Specification is becoming a general work skill
Engineers have spent years turning fuzzy intent into testable work through acceptance criteria, tests, and definitions of done. Other knowledge work can use the same discipline without pretending every job is software development.
A financial model has inputs and assumptions. A market-entry plan has conditions that would make it fail. A contract review has standards and exceptions. A campaign has an audience, a hypothesis, and a result that can be measured.
The skill is making the intent clear enough that someone else can act on it and check the result.
If the output can only be judged by “looks good,” the work is hard to improve and easy to overrate. Vibes do not scale.
## My meeting-budget idea
Large organizations spend a lot of time coordinating themselves. Status decks, alignment calls, approval rounds, and people added to meetings because someone may need them for five minutes.
I have a personal fantasy that meetings should have a visible budget. Thirty minutes with a senior architect would debit the department. Adding a vice president would increase the price. The numbers would be illustrative, but the cost would no longer be invisible.
Would every meeting survive if the organizer had to spend a real budget on it? I doubt it.
AI can reduce some reporting and note-taking, but organization design still sets the amount of coordination needed. If a company becomes leaner, some handoff work disappears. Other work remains because smaller teams still need decisions, context, and accountability.
If a meeting or handoff takes five people's time, it should earn that time.
## What actually helps
### Define the outcome
Replace “make it better” with a result someone can observe. Name the user, current problem, expected change, and constraint.
### Build a way to prove yourself wrong
Engineers write tests. A strategy needs the same kind of honesty: sources, assumptions, checkpoints, and a condition that would make you stop.
Work that can be checked can be trusted. Work that cannot be checked is opinion with a nice font.
### Build systems, not recurring deliverables
A quarterly report consumes time every quarter. A system that collects the inputs and exposes the decision may need your judgment only when something changes.
The report can still exist, but it becomes an output of the system instead of the work itself.
### Check where your value sits
Ask what remains if the routine execution becomes much cheaper. Customer judgment, prioritisation, risk, domain knowledge, and accountability do not disappear because a draft arrives faster.
If most of the role is moving information between people, that is worth examining. Not panicking about. Examining.
## Do not assume one productivity multiplier
Published results are mixed because the work is mixed. The [Stanford AI Index 2026](https://hai.stanford.edu/assets/files/ai_index_report_2026_chapter_4_economy.pdf) summarizes productivity gains, but it also covers [one 2025 study](https://arxiv.org/abs/2507.09089) in which experienced open-source developers were 19% slower with early-2025 AI tools. The report notes that the result was not later replicated.
That is closer to what I see than the idea that every team becomes five times faster. AI helps when the task, context, and verification fit the tool. When they do not, faster output can create more review and rework.
Start with one piece of work you do repeatedly. Specify the outcome more exactly than usual. Let AI produce a version, then test whether it met the conditions you set.
Run that test once. You will learn more from it than from another prediction about the future of work.
## Sources
- [2026 Agentic Coding Trends Report](https://resources.anthropic.com/hubfs/2026%20Agentic%20Coding%20Trends%20Report.pdf), Anthropic. Reports that about 27% of AI-assisted work consists of tasks that would not otherwise have been done.
- [AI Index Report 2026: Economy](https://hai.stanford.edu/assets/files/ai_index_report_2026_chapter_4_economy.pdf), Stanford Institute for Human-Centered Artificial Intelligence. Summarizes measured productivity gains and the limits around one early-2025 developer slowdown result.
- [Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity](https://arxiv.org/abs/2507.09089), METR. Supplies the specific 19% slowdown result and the narrow setting in which it was measured.
---
# The app consolidation playbook
**Author:** Ivan Misic
**Published:** 2026-02-18
**URL:** https://ivanmisic.net/blog/digital-transformation/app-consolidation-playbook
**In plain English**
App sprawl looks like a technical mess, but it is a leadership problem. Consolidating means running every product through three questions: does it need to exist on its own, what do you lose by merging it, and what is the migration path. Then you cut the low-use features and retrain people, which is most of the real work, and you accept it takes years. Platform choice comes last. First you need someone senior enough to make the hard calls.
App consolidation needs authority to close products, not only a new platform. In programs I worked on, the first inventory always found more apps and codebases than expected, often serving the same customer needs.
## The Real Cost of Digital Sprawl
The cost appears in repeated work. One market fixes a bug while the same bug remains in three other apps. Several teams build the same account, billing, or support journey, and customers still move between apps from the same company. Knowledge and maintenance also stay split across codebases. In one simple case, ten teams may each fix the same password-reset problem instead of fixing it once.
I would consolidate the overlapping products, but only after deciding which local differences still matter.
## How Digital Sprawl Happens
The duplicate products usually come from several reasonable decisions made at different times.
Local autonomy comes first. Each country has different products, pricing, regulations, and customer expectations. Local teams want local solutions. "Our market is different" is a powerful argument, and often true.
Acquisitions add to it. When you buy a company, you inherit their digital products. Integrating them is expensive and risky. So you don't. You end up with parallel apps serving similar customers.
Product silos make it worse. The mobile team builds a mobile app. The broadband team builds a broadband app. The TV team builds a TV app. Each team optimizes for their domain. Nobody optimizes for the customer who has all three.
Different agencies may also build separate products for each contract. A new app can look faster than integrating with the existing platform, but the company then owns another codebase and its maintenance.
Leadership changes add another layer. A new leader may fund a replacement instead of improving the existing platform. After several cycles, the company has multiple partly adopted platforms without evidence that the older one failed.
## The Consolidation Decision
The difficult part is closing a product that a team built and a stakeholder funded. Both have valid reasons to protect it, so the decision needs evidence and a clear owner.
Consolidation needs an executive owner who can decide which products will close and support the team when markets disagree. I've seen consolidation work when it had that backing, and watched it stall for years when it was treated as just another [digital team project](/blog/product/digital-team-act-like-startup).
Without that owner, each sunset decision returns for another approval and local teams keep their existing platforms.
## The Three Questions
> For every digital product in your portfolio, there are only three questions that matter: Does it need to exist separately? What do we lose by merging it? And what's the path to get users across? Everything else is noise.
**1. Does this need to exist as a separate app?**
Some digital products exist because they were built separately, not because they need to be separate. If a mobile customer and a broadband customer have the same core needs (check usage, pay bills, get support), they probably don't need different apps.
Other products exist because they serve different use cases. A consumer-facing retail app has different needs than an internal logistics platform. These might stay separate.
**2. If we merge this, what do we lose?**
Local customization matters. An identical app may miss local regulation, pricing, or customer needs. Decide which differences affect the customer outcome and keep those configurable.
Pricing, promotions, and campaigns? Keep them under local control. Core journeys like login, billing, and support? They can be standardized.
**3. What's the migration path?**
Closing an app with active users needs a migration plan. I would move users in stages, measure completion and support demand, then close the old app when the required journeys work.
Use feature parity as the gate: don't sunset the old app until the new one can do everything users actually need. That means what users actually use, which is a much shorter list than everything the old platform could do.
Migration also covers support training, call-centre scripts, marketing material, and every link to the old app. In programs I worked on, this coordination took more effort than the technical switch.
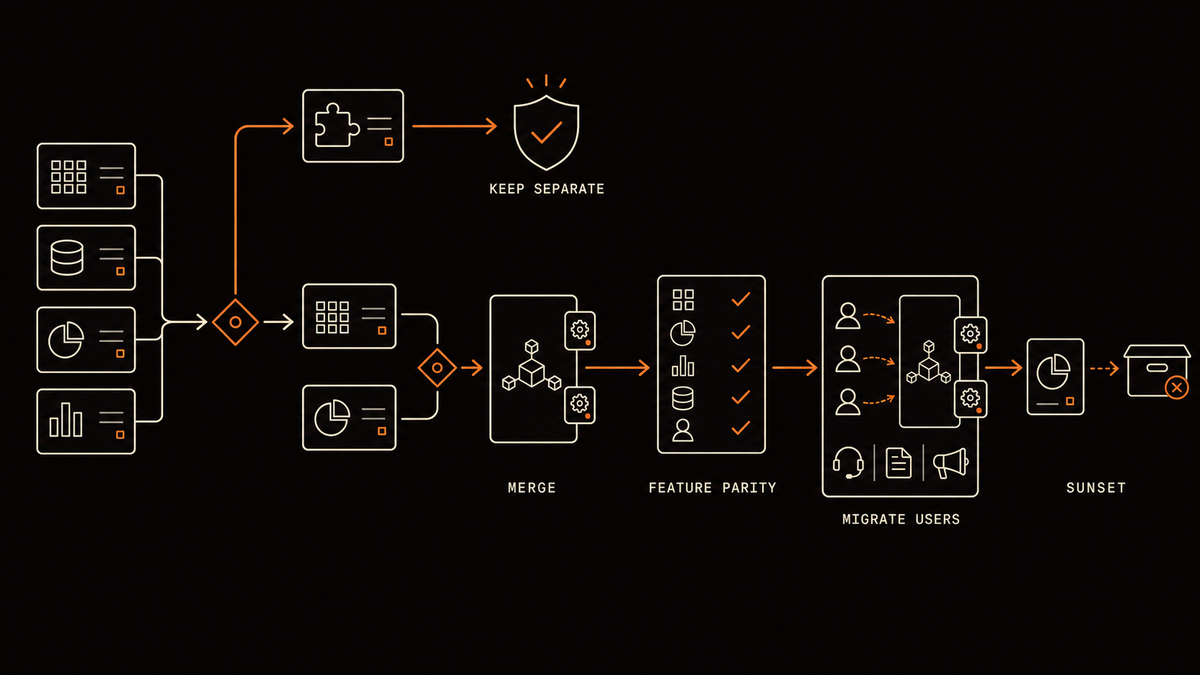
Keep products separate when they serve different use cases. Where core needs overlap, merge while preserving meaningful local configuration. Sunset the old app only after used-feature parity and a managed migration of users, support, documents, and campaign touchpoints. The sequence matters; its duration depends on the portfolio.
## The Central/Local Model
I would use one core codebase with local configuration and integrations, not one identical app for every market.
The central team owns the core: architecture, UX patterns, main journeys, and the component library. They build once.
Local teams own the content: pricing displays, campaign configurations, local features, and market-specific integrations. They customize via CMS and configuration, not code.
This requires a clear contract. Local teams can't demand custom journeys that break the architecture. Central teams can't ignore local needs that affect adoption.
Local teams should describe the business outcome they need, such as reducing billing calls. The central team proposes a solution within the shared architecture, and the local team checks whether it works for that market.
The central process also needs a response time. If local teams wait too long, they will use third-party tools, iframes, or small local apps. That creates another layer of products outside the shared platform.
## The API Abstraction Layer
The backend is usually the largest constraint. Markets may use different billing, CRM, and catalog systems, so replacing all of them as part of the app program adds cost and risk.
I would put a standard API contract between the app and each market's backend, as described in my article on the [abstraction-layer approach](/blog/digital-transformation/dont-replace-billing-system).
The app doesn't know or care if Market A runs SAP and Market B runs Oracle. It calls the same API. Local teams implement that API against whatever backend they have.
Agreeing on that contract is the difficult part. The central product team should propose it, collect input from local teams, and make the final decision when agreement is not possible. Otherwise ten markets can keep the design open indefinitely.
## What Gets Cut
Consolidation should also reduce the feature set. Use product data to identify which features customers still use, applying the same [prioritization approach](/blog/product/laundry-list-trap-prioritization). Keep features that support the agreed customer outcome. Remove unused features and fix local workarounds at their source instead of copying them into the shared app.
Feature removal will be challenged, so the central team needs authority to decide and an executive owner to handle escalations.
## The Timeline Reality
For the portfolio I worked on, the program took over three years. Eighteen months would not have covered the platform, migration, and local rollout.
| Phase | Focus |
|-------|-------|
| Foundation | Build the platform, launch in pilot markets |
| Expansion | Roll out to more markets, build API layer, add core features |
| Maturity | Add engagement features, expand to additional brands, continuous improvement |
## The Results
The expected gain is less repeated work. A shared codebase allows one fix or feature to reach several markets, while new markets start with an existing product and integration contract. The program still needs to measure delivery time and maintenance cost to confirm that gain.
## Name the decision owner
Architecture is not the main blocker. Someone must decide which app closes, which local feature stays, and when a migration is complete. That owner also needs to support the team when a market, agency, or product owner escalates the decision.
Start by naming that person. If nobody has authority to close an app, the consolidation program is not ready.
---
# Start AI adoption with the work slowing your team.
**Author:** Ivan Misic
**Published:** 2026-02-17
**URL:** https://ivanmisic.net/blog/ways-of-working/ai-isnt-coming-for-your-team
**In plain English**
In the work I see, AI is most useful when it removes repetitive preparation and gives experienced people more time for judgment. Test one workflow with a result you can check, let the person who owns the work design and review it, and keep it only if the reviewed result improves. Measure what the expert does with the saved time. Keep practical work and review for junior people so they can build the judgment needed to check AI output.
I do not believe AI's main impact will be replacing whole teams. In the work I see, its immediate value is removing tasks that keep experienced people busy.
Some jobs and tasks will change or disappear. I do not see one answer that applies to every role, company, and industry. The [Stanford AI Index 2026](https://hai.stanford.edu/assets/files/ai_index_report_2026_chapter_4_economy.pdf) includes positive, neutral, and negative productivity results depending on the task and worker context.
So I would ask a narrower question: which repeated work can disappear, and what can your experienced people do with the time?
## What I see in my own work
One change matters to me: a product manager, or anyone close to the problem, can turn an idea into a rough visual prototype before working through it with design and other experts. The idea and decision remain theirs. AI shortens the path from a problem statement to something the team can see and discuss.
I used AI in a team retrospective for the same reason. It clustered and visualised the feedback during the session. Five minutes in, we had a view of the patterns and could spend the remaining time discussing what to change.
Without that step, someone would normally collect the notes, group them, prepare the analysis, and bring it back later. AI did not decide what the team should improve. It shortened the path to the useful conversation.
Product documentation works the same way. A model can draft a PRD, epics, and user stories in minutes. The generated structure is the easy part. Someone who understands the product still has to catch the missing constraint, weak assumption, or user need.
> AI handles parts of the work that consume time. People still decide whether the result is useful and correct.
## Give the quiet expert time
Most organizations have someone who bridges business and technology. They understand the customer problem, know which systems are fragile, and can translate an executive request into something a delivery team can use.
They are often the same person pulled into every meeting, status report, escalation, and “quick question.” Their value is judgment, but much of their day goes into moving context between people.
Giving that person another AI chat subscription changes little. Connecting AI to one real workflow can change a lot.
If meeting notes, issue grouping, first-draft documentation, or repeated analysis becomes faster, the expert can spend more time on the decision. That is the gain I would measure.
Would they use the saved time well? That depends on the priorities and authority around them. Removing busywork without changing what the person is allowed to decide only creates a cleaner queue.
## Scale stops being the only advantage
Take a small legal firm as a hypothetical example. A larger firm can put more people on document review and precedent research. The smaller firm may have excellent lawyers but less capacity for the supporting work.
If AI reduces part of that research and drafting load, the smaller firm can cover more ground. It still needs qualified lawyers to judge relevance, accuracy, confidentiality, and strategy. The tool changes the capacity gap. It does not turn legal work into a button.
I see the same opportunity wherever experts lose time preparing, copying, and sorting information. The point is to get more value from the expertise already there. It does not mean the profession has been transformed.
## Do not remove the path that creates experts
A senior can use AI to work across a wider area because years of practice provide a reference for what looks wrong. A junior does not yet have that reference.
That is an argument for better mentoring and safer review, not for removing junior roles. If a company stops developing people because AI can produce the first draft, it also weakens the future pool of people able to check those drafts.
I cover the team and junior-development tradeoff in [Your next team is three people and a pile of agents](/blog/ways-of-working/next-team-three-people-pile-of-agents).
## AI needs structure around it
A polished output can still be wrong. A useful workflow needs:
- a clear task and expected result
- access to the right data and tools
- boundaries for sensitive data and risky actions
- a person responsible for review
- a way to measure whether the result improved
If the source data is poor and the process is undocumented, AI can produce a confident answer from weak inputs. Faster nonsense is still nonsense.
This is why I would not start an adoption programme with a tool licence or a headcount target. Start with the work.
## What I would do as a leader
1. Ask experienced people which repeated task consumes time without using much judgment.
2. Pick one workflow with a result you can verify.
3. Remove the compliance, access, or data blocker that prevents a safe test.
4. Let the person who owns the work design and review the test.
5. Keep it only if the result is better after review, not merely faster to produce.
Do not begin with “where can we remove people?” That question encourages teams to hide risk and protect work. Ask where expertise is being wasted on preparation, copying, reformatting, or repeated analysis.
The harder part is giving people access to the right context while meeting IT security and compliance requirements. In my experience, those limits prevented us from using much of AI's capability or changing the workflow around it.
## Start with one workflow
Pick one recurring task this week. Test where AI saves time, check the output yourself, and keep the workflow only if the result is better.
One real workflow will teach you more than another prediction about how many jobs AI will replace.
## Sources
- [AI Index Report 2026: Economy](https://hai.stanford.edu/assets/files/ai_index_report_2026_chapter_4_economy.pdf), Stanford Institute for Human-Centered Artificial Intelligence. Shows that measured AI productivity effects vary by task, worker, and study setting.
- [Generative AI at Work](https://academic.oup.com/qje/article/140/2/889/7990658), The Quarterly Journal of Economics. Reports an average productivity gain in a field study of 5,172 customer-support agents, with larger gains for less experienced workers.
- [Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity](https://arxiv.org/abs/2507.09089), METR. Reports a slowdown for experienced open-source developers using early-2025 AI tools in a specific real-world setting.
---
# Build the API layer before replacing the billing system.
**Author:** Ivan Misic
**Published:** 2026-02-15
**URL:** https://ivanmisic.net/blog/digital-transformation/dont-replace-billing-system
**In plain English**
A large core-system transformation should not be the entry ticket for every new digital capability. Put a stable API contract between digital products and the existing billing, CRM, catalog, ordering, and provisioning systems. The contract gives digital teams a clean interface while adapters handle the legacy reality behind it. This adds work around consistency, transactions, latency, monitoring, and ownership, but it lets digital delivery and backend modernization move on separate timelines.
Digital delivery should not wait for a full core-system transformation.
In telecom, that usually means the OSS/BSS estate. In other industries, the names differ, but the problem is the same: a [new app or customer journey](/blog/digital-transformation/app-isnt-service-channel) needs data and actions from billing, CRM, catalog, ordering, provisioning, or another system that was not designed for modern digital products.
The tempting response is to start a large replacement program. I would start with a smaller question: what stable contract does the digital product need?
Build that API layer first. Let it translate between new digital demand and the systems already running the business. Then modernize those systems behind the contract at the pace the backend can handle.
## The Transformation Trap
A core-system replacement can be necessary. It is also a poor dependency for a digital roadmap.
The replacement has to deal with old business rules, integrations, reporting, finance, operations, and customer-service processes. The digital product needs a clear way to read a balance, show an offer, submit an order, or check its status. Those are related problems, but they do not need the same delivery plan.
When they are tied together, every new digital capability inherits the scope and risk of the backend program. The customer waits for the whole estate to become modern instead of [getting a smaller useful scope live](/blog/digital-transformation/stop-trying-to-digitalize-everything).
That is the assumption I would challenge.
## Put a Stable Contract in the Middle
The digital product should talk to a stable API contract, not directly to every core system.
The API layer exposes the capabilities the product needs in a consistent shape. Adapters behind it translate those requests into the data models, protocols, and business rules used by the existing systems. Microsoft describes a similar boundary as an [Anti-Corruption Layer](https://learn.microsoft.com/en-us/azure/architecture/patterns/anti-corruption-layer): the new product keeps its own model instead of copying the legacy system's structure.
The old systems can stay ugly. They just stop setting the shape of every new product.
The first benefit is calendar time. The digital team can build against the contract while the backend teams improve or replace the systems behind it. If a billing platform changes later, the adapter changes. Every app should not have to learn the new billing interface.
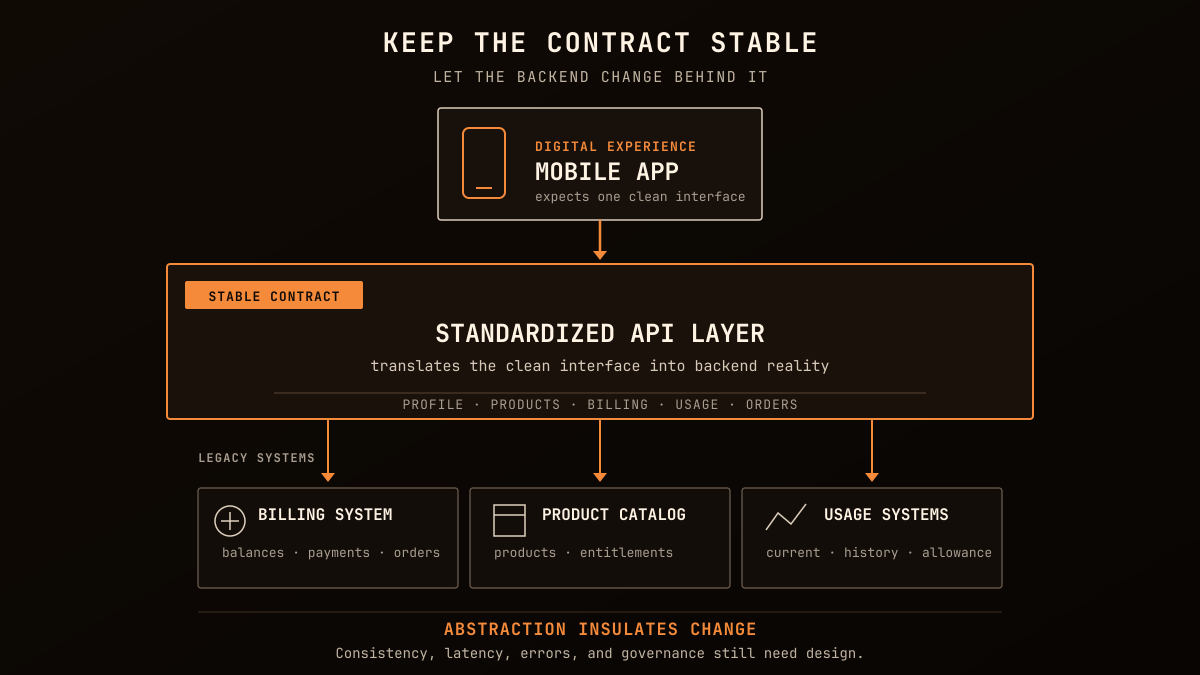
The stable contract separates digital demand from backend change. It does not remove the hard work around consistency, latency, error translation, and ownership.
## Billing Is One Example
Billing makes the problem easy to see because it sits behind balances, invoices, payments, contracts, and product changes. The same approach applies to CRM, product catalog, order management, provisioning, usage, and other core capabilities.
Keep the scope narrow. Start with the capabilities required by a real digital journey. Add another contract when there is another useful demand.
Customers do not need to know how many systems are involved in showing a bill or changing a product. They need a clear result. The abstraction layer is the boundary that keeps the complexity below the surface without pretending it has disappeared.
## What the API Layer Should Expose
The contract should describe what the digital product needs, not reproduce every table and code from the systems behind it.
| Capability | Digital Contract | Where the Complexity Usually Lives |
|------------|------------------|------------------------------------|
| Customer profile | Name, contact details, account status | CRM or customer master |
| Products and entitlements | Active products, prices, allowances | Catalog, billing, and entitlement systems |
| Billing and payment | Balance, invoices, payment options | Billing, finance, and payment services, depending on the current architecture |
| Usage | Current usage, history, remaining allowance | Network and operational systems |
| Orders and changes | Create, track, change, or cancel an order | Ordering and provisioning systems |
This table is only an example. The source of truth and ownership will differ between companies. Design the contract around a real digital need. Let each adapter handle the backend that exists today.
## What This Layer Does Not Solve
An abstraction layer moves the boundary. It does not remove the complexity.
**Data ownership.** The layer needs to know which system owns each field. If it keeps a cache or read model, the team must define how fresh the data needs to be and what happens when synchronization fails.
**Transactions.** A read is usually easier than an order, payment, or plan change. Multi-step operations need clear consistency rules, monitoring, retries, and a way to recover when only part of the work succeeds.
**Error translation.** A legacy error code may be correct for the backend and useless to the app. The API layer has to translate it without hiding the real failure from support and operations.
**Performance and resilience.** The extra layer adds latency and another component that can fail. Caching, timeouts, capacity, observability, and fallback behavior need deliberate design.
**Contract governance.** A stable contract still changes. Versioning and compatibility need one owner, or every digital team will create its own unofficial version.
## Treat It as Infrastructure
I would fund and own the API layer as infrastructure. Give it one accountable team, a budget, and a roadmap tied to real product demand.
Digital and backend teams should shape its priorities, but shared input is not shared accountability. Someone has to own the contract, the production incidents, and the decision about what belongs in the layer.
If every change needs a temporary project and another funding discussion, the operating model has turned the layer into a queue.
## When Replacement Is Still the Right Call
Building around a system is not an argument for keeping it forever.
Replacement still makes sense when the system blocks the business model, vendor support is ending, or the business process must change. It also makes sense when adapters and workarounds cost more than replacing it properly.
Even then, the contract still helps. Replace capabilities behind it in phases while the digital products keep using the same interface. The [Strangler Fig approach](https://martinfowler.com/bliki/StranglerFigApplication.html) uses this kind of gradual replacement to deliver value earlier and reduce the risk of one large cutover. Each phase still needs monitoring, rollback, and a clear exit condition.
## Ask a Better Question
When someone proposes a major OSS/BSS or core-system transformation, ask:
- What digital capability is waiting for it?
- What stable contract would let that capability move now?
- Can the backend change behind that contract without forcing every digital product to change?
- What operational cost and failure modes will the new layer add?
If full replacement is still necessary, do it. If one API contract can separate the timelines, build that first.
The backend does not need to be modern before the digital roadmap can move.
## Sources
- [Anti-Corruption Layer pattern](https://learn.microsoft.com/en-us/azure/architecture/patterns/anti-corruption-layer), Microsoft. Supports placing a translation boundary between new and legacy systems and documents the added latency, maintenance, monitoring, scaling, transaction, and consistency work.
- [Strangler Fig](https://martinfowler.com/bliki/StranglerFigApplication.html), Martin Fowler. Supports gradual legacy modernization through smaller independently replaceable parts, with earlier value and less cutover risk than wholesale replacement.
---
# How we used feature data to cut a telco app's scope
**Author:** Ivan Misic
**Published:** 2026-02-12
**URL:** https://ivanmisic.net/blog/product/laundry-list-trap-prioritization
**In plain English**
In one telco app, more than 40% of the candidate scope accounted for less than 2% of measured engagement. Three core jobs, payment, usage, and onboarding, produced roughly 85% of observed engagement, so we cut the low-value scope and gave the team more time for the core journeys. That is evidence from one product, not a universal ratio. Before cutting a feature, also check compliance, discoverability, strategic value, dependencies, and what actually happens if you do not build it.
> In one telco app, more than 40% of the candidate scope accounted for less than 2% of measured feature engagement.
At a European telco, we had a laundry list of features: the kind that accumulates when you ask stakeholders what they want. Fingerprint login. Detailed call itemization. Loyalty program integration. FAQ knowledge base. Live chat. Store appointment scheduling. The list went on.
Every feature had a champion. Every feature had a business case. Every feature felt important to someone.
## How Laundry Lists Happen
The list grew because every request sounded reasonable on its own. Nobody was looking at the total cost.
Feature parity was the first source of scope. The old system had 47 features, so the new one was expected to carry all 47. Never mind that 30 of them were used by a handful of customers a handful of times.
Stakeholder wish lists pile on top. The marketing team wants campaign integration. The operations team wants fault reporting. The retail team wants store locators. Everyone gets something. Nobody prioritizes.
Competitive benchmarking added more. A competitor had a feature, so it entered our list before anyone checked whether customers used it. Edge cases added more scope: "But what about the customer who needs to do Z?" That customer exists. They're also 0.03% of your base. Should they drive your roadmap?
We ended up with a long list and no agreed way to decide what mattered.
## What the usage showed
We did something that sounds obvious but rarely happens: we measured engagement across every feature before deciding what to build next.
Not "will stakeholders approve this?" Not "does this fill a gap in our competitive matrix?" Actual customer behavior. What do people use? What do they ignore?
The usage did not match the roadmap.
| Feature Category | Expected Value | Actual Engagement |
|-----------------|----------------|-------------------|
| Payment & billing | High | ~35% of all engagement |
| Usage monitoring | High | ~30% of all engagement |
| Onboarding flows | Medium | ~20% of all engagement |
| Loyalty integration | High (stakeholder view) | <3% |
| Live chat | Medium | <2% |
| Store features | Medium | <1% |
| Detailed itemization | Low | <1% |
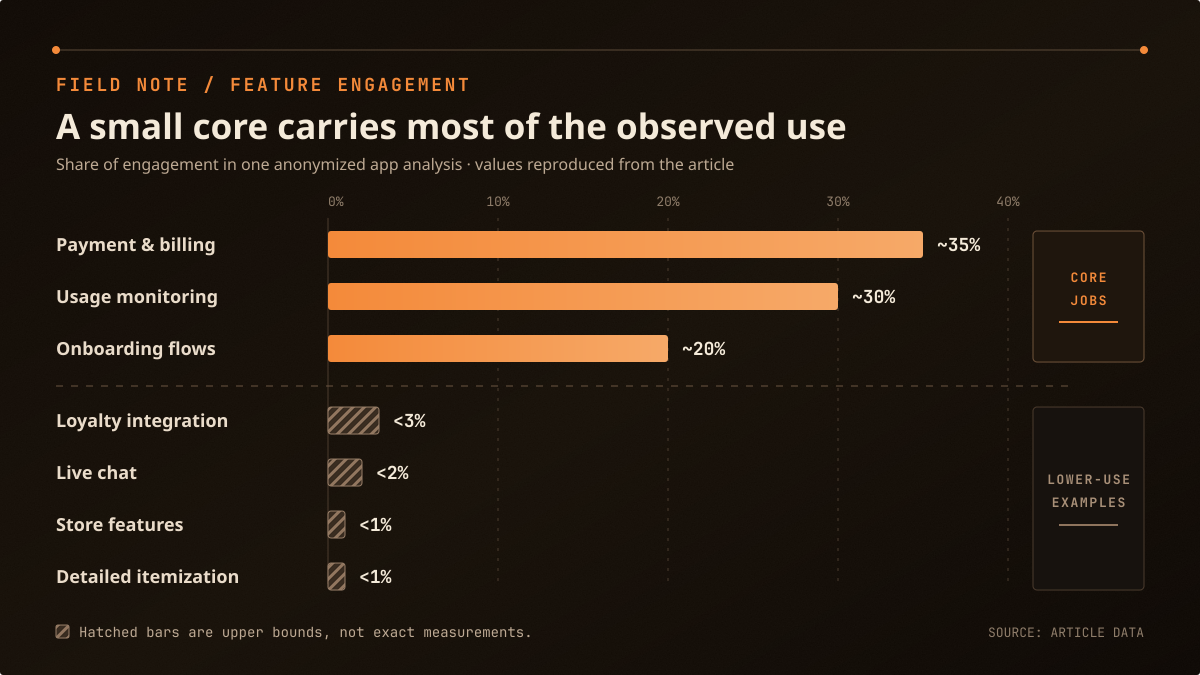
In this product, three core jobs accounted for roughly 85% of observed engagement. The lower-use examples are shown as reported upper bounds, not exact measurements or a universal 80/20 rule.
Features that felt important (live chat, detailed billing breakdowns, fault ticket creation) barely registered. Customers had asked for these things. Stakeholders had fought for them. And when we built them... crickets.
Meanwhile, the boring stuff dominated. Checking usage. Making payments. Viewing bills. The core jobs that brought people to the app in the first place.
## What Actually Matters
In this product, three jobs accounted for most of the measured engagement:
**Payment and billing.** This produced about 35% of the measured engagement. Customers came to check what they owed and pay it, so that journey deserved more attention than the feature list gave it.
**Usage monitoring.** This produced another 30%. Seeing what was used, what remained, and what the plan included was one of the app's main jobs.
**Onboarding.** Yes, this matters, but I list it third deliberately. Most organizations already have something here. It's table stakes, not differentiator. If you're building a digital product without onboarding, you have bigger problems than prioritization.
Everything else? [Evaluate ruthlessly](/blog/digital-transformation/stop-trying-to-digitalize-everything). That loyalty program integration might wait. The live chat might not be as urgent as the chat vendor claims. The detailed call itemization that three customers requested might not be worth the development time.
## The Prioritization Mindset
I would not turn this into another scoring framework. Start with customer behavior, then add compliance, strategy, and delivery cost.
Start with behavior, not requests. What are customers actually doing? Usage data is a better starting point than a stakeholder vote, but it is not the only input. Compliance, poor discoverability, and deliberate strategic bets still need judgment.
A low-use feature still adds maintenance, testing, and another decision to the interface. That cost belongs in the roadmap discussion.
Question "must-haves." When someone says a feature must be there, ask: who needs it? How many customers? How often? What happens if we don't build it?
Some requests will not make the roadmap. That is the result of prioritization, not a failure of it. Measure after launch. Track engagement on what you build. Be willing to sunset features that don't perform. Don't let sunk cost fallacy keep dead features alive.
## The Uncomfortable Conversation
The difficult part starts when a stakeholder's feature does not make the cut.
The Head of Retail really wants that store appointment feature. The data says store locator gets 0.3% engagement. That conversation is awkward.
But the alternative is worse. Build everything everyone wants, and you'll ship late, over budget, with an app so cluttered that the features people actually need get buried.
I use the data to move the discussion away from who requested the feature. The question becomes whether the observed customer value justifies the cost.
Some stakeholders won't accept it. That's a [leadership problem](/blog/product/renaming-it-to-product-didnt-fix-anything), not a product problem. Escalate if needed. But don't compromise the roadmap to avoid difficult conversations.
## When to Break the Rule
Data-driven prioritization isn't absolute. Sometimes you build low-engagement features anyway.
Compliance is the clear one. If a regulation requires a feature, engagement is irrelevant. Build it.
Discoverability is trickier. Sometimes a feature has low engagement because it's buried four clicks deep, not because it's unwanted. Before cutting a feature, check whether the UI is hiding it. A poorly placed feature and an unwanted feature look identical in the data.
Then there are strategic bets. Maybe the loyalty program has low engagement now because the experience isn't good enough. A redesign might change that. But be honest: is this a strategic bet or a stakeholder appeasement? Same with foundation features: some enable other features. Low engagement today might turn into high engagement tomorrow. Track this, don't just assume it.
Low engagement is a reason to check compliance, discoverability, strategic value, and cost before rejecting the feature.
## The Result
When we cut that 40% of scope, the team had more time to build and test the core journeys. We did not measure whether customers noticed the missing features after launch, so I would not claim they did not.
## The Question to Ask
Before adding anything to your roadmap, ask this: "If we don't build this, what happens?"
If the answer is "some customers will be mildly inconvenienced," maybe it can wait. If the answer is "we'll lose customers to competitors," dig deeper, because that's usually a nice-to-have dressed up as a must-have.
If customers cannot complete the core job without it, build it first.
Most features fall into the first two categories. Build the third first, then check the usage data after launch.
---
*A product team needs to say no when the evidence is weak. Stakeholder needs matter, but they do not replace customer outcomes.*
---
# Telco apps: from self-service to sales and retention
**Author:** Ivan Misic
**Published:** 2026-02-08
**URL:** https://ivanmisic.net/blog/digital-transformation/app-isnt-service-channel
**In plain English**
If you run your app only as a cheaper way to deflect calls, you limit what it can be worth. In the European telco programs I saw, the app moved through three phases: service, sales, then retention. The shift became harder when sales and retention began to overlap with channels that already owned those results. The programs that moved beyond self-service had a senior sponsor who treated the app as part of the business, not an IT channel. Ask yourself: if your app vanished tomorrow, would anyone notice beyond the annoyance of having to call?
Self-service is a useful baseline, but I would not stop there. The app should become a main sales and retention channel, not remain a cheaper call centre.
I have seen enterprise apps start as a way to move balance checks, payments, and address changes out of shops and call centres. That can reduce service cost and give customers a faster route.
I have also seen a new product receive its own app while the existing channels stayed in place. The result was another platform doing similar work, with no clear plan for which system should be removed.
Revolut, N26, and Monzo built the app into the business model. Telcos started elsewhere, but the app does not need to remain a display layer.
The question I would ask is: what changes when the app becomes a main business channel?
Compare that to an approach I have seen in enterprises: add a new portfolio to the app while the business model stays the same. Backwards. You're treating digital as a display layer instead of a business driver.
## The Three Phases
In the European telco programs I saw, the app moved through three distinct phases. Phase one was often where progress stopped.
Across the European telco programs I saw, the move from self-service to monetization and retention took years. The ranges below describe that experience, not a timetable every company will follow.
| Phase | Observed timing in programs I saw | Focus | Key Metrics | Main Obstacle |
|-------|----------|-------|-------------|---------------|
| Service & Adoption | Years 1-3 | Get customers using the app instead of calling | MAUs, downloads, call deflection | Legacy integration |
| Monetization | Years 3-5 | Turn the app into a revenue channel | Revenue through app, conversion rates | Channel conflict |
| Engagement & Retention | Years 5+ | Make the app a competitive advantage | Engagement frequency, churn differential, NPS | Data maturity |
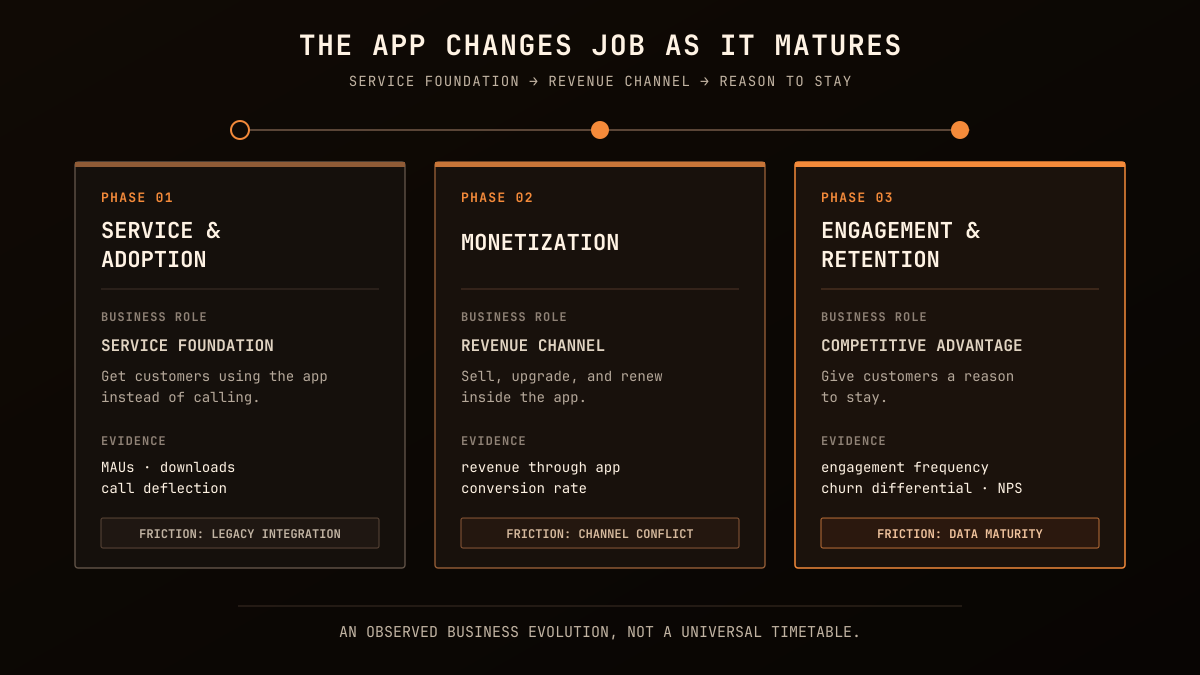
The app changes jobs as the business model evolves: first a service foundation, then a revenue channel, then a reason for customers to stay. The phases summarize an observed path, not a universal timetable.
### Phase 1: Service & Adoption
The programs I saw started with a clear goal: move common service requests from calls and shops into the app.
- Login and authentication
- View bills and payment history
- Make payments
- Check usage and balances
- Basic support and FAQ
I would still build these service journeys first, as sales and retention depend on customers already using the app.
The mistake is treating adoption as the final result. Once enough customers use the app for routine service, the company has a foundation. The next question is what customers and the business can do through it.
### Phase 2: Monetization
Here the app stops being a cost center and starts generating revenue.
- Upsell and cross-sell journeys
- Tariff changes and upgrades
- Add-on purchases (roaming packs, extra data)
- Contract renewals and extensions
- New customer acquisition (yes, through the app)
Once the app starts selling, its team needs commercial targets alongside technical measures. This also creates direct overlap with retail and call-centre sales.
The team now needs commercial product ownership, access to sales data, and a place in go-to-market planning.
In the programs I saw, this phase created conflict with retail and call-centre targets. Moving sales into the app changed which channel received the result.
### Phase 3: Engagement & Retention
In phase 3, the app starts supporting retention through loyalty, useful offers, and proactive service.
- Loyalty programs integrated into the app experience
- Anticipatory service: the app telling you that you're about to exceed your data cap while roaming, and offering a one-tap fix before you even knew there was a problem
- Personalized offers based on usage patterns
- Partner networks (discounts, benefits, integrations)
- Gamification and engagement mechanics
- Content and experiences beyond core services
- Proactive notifications that add value
> In the program I saw, loyalty users returned to the app more often and stayed longer. That correlation supported more investment, but it did not prove the program caused the difference.
## Why Programs Get Stuck
Phase 1 usually has a clear cost-saving case. Phase 2 is harder because app sales affect targets owned by other channels. In practice, retail, call-centre, and app teams may all be measured against the same sale. Senior management needs to decide how that result is credited, as the app team cannot resolve the conflict alone. I would rather move the sale into our own app than leave the customer to a digital competitor.
Phase 3 needs investment in loyalty, partners, and content before the retention effect is clear. I would start with one measurable use case and treat early engagement as a signal, not proof of retention.
## The Board-Level Moment
In the programs I saw, the shift needed a senior sponsor with authority over channel conflict. The app team could make the case, but only that sponsor could settle competing targets and give the team room to make cross-channel decisions.
Without senior sponsorship, I have seen the shift start and then disappear when channel conflict arrived.
## The Engagement Trap
A warning about phase 3: engagement for engagement's sake is vanity.
I would not add gamification only to increase time in the app. The engagement measure needs to connect to a customer benefit or a business outcome.
The telco's loyalty program worked because it delivered actual value. Real discounts from real partners. Exclusive offers that saved customers money. The engagement was a side effect of value delivery, not the goal itself.
If a notification or game mechanic only increases opens or sessions, remove it. It needs to help the customer complete something useful.
## What Changes Organizationally
As the app takes on sales and retention, the team needs commercial, data, and partner skills as well.
A phase 1 team is engineers, designers, maybe a product owner focused on delivery.
Phase 2 adds commercial product managers, data analysts, and integration with marketing. The team needs P&L awareness.
By phase 3, the team also needs people who can manage partners, loyalty offers, and customer communication.
Each phase needs different skills, measures, and decision owners. A service-focused team cannot own partnerships and retention without adding that capability.
## The Self-Service Ceiling
> If the app remains a self-service channel, its value remains limited to service cost and convenience.
Self-service can reduce cost, but that benefit reaches a limit once most suitable calls have moved into the app.
Sales and retention add another source of value after most suitable service calls have moved online. Retention and an additional sale can create more value than another deflected service call, but I would measure that rather than assume it.
The question worth asking: how do we make the app so valuable that customers wouldn't consider leaving?
That question changes which features and measures the team prioritizes.
## Starting the Shift
If you're stuck in phase 1, start here:
**Get commercial metrics into your reporting.** Even if you're not driving revenue yet, start tracking what revenue flows through the app. Make it visible.
**Find one monetization journey.** Pick the simplest upsell or cross-sell that could happen in-app. Build it. Prove it works. Use that proof to get budget for more.
Then build the retention case. Compare churn rates for app users and non-users, but treat the result as correlation until you control for differences between those customers. Use it to frame the next test, not as proof by itself.
Bring the commercial and retention evidence to a senior sponsor who can resolve channel conflict. Without that authority, the app team can identify the problem but cannot settle it.
---
*If customers would only miss the convenience of not calling, your app is still in phase 1.*
---
# Choosing your next project with Claude Code
**Author:** Ivan Misic
**Published:** 2026-02-07
**URL:** https://ivanmisic.net/blog/ai-tools/where-to-go-from-here
**In plain English**
Pick one real project small enough to finish this week. Write down who it is for, what the first version must do, and how you will check that it works. Use Claude Chat to explore a decision, Claude Code for software projects and development tools, or Cowork for multi-step knowledge work, while checking the current product boundaries first. You do not need to write every line yourself, but you still own the result, review, recovery, and decision to ask for help.
You now have a working website and enough Claude Code experience to build the next thing. Pick one real problem, give Claude a narrow task, and review the result before adding more.
The guide covered 24 parts, from opening a terminal to publishing a site. Finishing the course matters less than being able to take one idea and turn it into something that works.
## What you can do now
You can:
- describe a result and give Claude the files and constraints it needs
- review changes instead of accepting a polished answer on trust
- keep work recoverable through versions, copies, and small steps
- publish a project and improve it from real feedback
You do not need to write every line yourself, but you still need to explain what you want, review the result, and know when to ask for help.
That responsibility does not disappear when the tool becomes easier to use.
## Pick the next project
Choose something small enough to finish this week. A finished narrow tool teaches you more than another half-built platform.
You could extend the website with a resources page or a small portfolio. You could automate a repeated spreadsheet cleanup, create a calculator for one work problem, or build a dashboard from a file you already maintain.
For a team project, the first useful improvement may be less visible: add project instructions, document the validation commands, or turn one repeated task into a reusable skill.
My filter would be simple:
1. Is there one person who will use it?
2. Can you explain the problem in two sentences?
3. Can the first version be finished in a week?
4. Can you check the result yourself?
If the answer to the last question is no, make the first version smaller.
## Choose the interface from the work
Claude's product boundaries keep changing, so I would choose the interface from the files and actions the task needs.
| Use | Good starting point |
|---|---|
| Explore an idea, ask questions, or work through a decision | Claude Chat |
| Inspect a software project, run development tools, and review file changes | Claude Code |
| Hand off multi-step knowledge work across documents and connected tools | Claude Cowork |
These overlap. Claude Code is available beyond the terminal, and Cowork can also use files and tools. Choose based on the work you need done. The friendlier screen is secondary.
Cowork is available on desktop. Web and mobile are still in beta for Pro, Max, and Team plans, and for Enterprise when an admin enables it. If you want Cowork to reach local files, use your browser, or control your computer from web or mobile, the Claude Desktop app must stay open. Check Anthropic's [current Cowork guide](https://support.claude.com/en/articles/15520349-use-claude-cowork-on-web-desktop-and-mobile) before choosing it for a workflow.
For software work, check the [current Claude Code interfaces](https://code.claude.com/docs/en/platforms) instead of treating this course's terminal setup as the only option.
## Reuse what worked
When an instruction produces a good result, save the useful context. That may become a project rule, a template, or a small reusable skill.
Do not save every prompt. Keep the part that explains the decision, constraints, and check. Save enough context so you do not need to explain the same decision again next week.
## Build the first part
You still need to decide what should exist, who needs it, and why. Claude can build from that decision, but it cannot make it for you.
Pick one small project you can finish this week. Write down who it is for, what it must do, and how you will check that it works. Then build the first part.
## Sources
- [Use Claude Cowork on web, desktop, and mobile](https://support.claude.com/en/articles/15520349-use-claude-cowork-on-web-desktop-and-mobile), Anthropic. Supports current plan eligibility, beta status, cross-device sessions, and which local capabilities require the desktop app.
- [Platforms and integrations](https://code.claude.com/docs/en/platforms), Anthropic. Lists the current CLI, desktop, IDE, web, mobile, and integration surfaces for Claude Code.
---
# How I built this site with Claude Code.
**Author:** Ivan Misic
**Published:** 2026-02-07
**URL:** https://ivanmisic.net/blog/ai-tools/how-i-built-this-site-with-claude-code
**In plain English**
I built the first version of this site over about three weeks with a custom PHP backend, vanilla JavaScript, custom public CSS, and Claude Code doing most of the typing. The original build used no backend, frontend, or CSS framework; the current admin area later gained a standalone Tailwind build. Claude made implementation fast, but architecture, design, review, security, and documentation stayed with me. Focused sessions, early rules, design tokens, and time to understand the generated code would have made the work cleaner.
I built the first version of this website over about three weeks of actual work. A week during holiday, a handful of weekends, and some late nights in between. I built that version without WordPress, Laravel, React, or Tailwind. The public site still uses PHP, vanilla JavaScript, and custom CSS. The admin area later gained a standalone Tailwind build, so the sections below distinguish the original build from the current repository.
## Why Build From Scratch?
After years of managing products built on frameworks and platforms, I wanted to understand what's actually under the hood, not just the abstraction sitting on top of it.
I wanted to understand AI-assisted development before using it in product work, so I chose a real project with enough complexity to expose its limits.
So I set some rules:
1. **No backend frameworks.** No Laravel, no Symfony. Custom MVC from scratch.
2. **No frontend frameworks.** No React, no Vue, no jQuery.
3. **No CSS frameworks.** No Tailwind, no Bootstrap. Custom design system with tokens.
4. **Build it properly.** Database migrations, service layer, feature flags, deployment pipeline. Not a toy project.
5. **Use Claude Code for implementation.** I'd make all the architecture and design decisions. Claude would write the code.
## The Stack
What powers this site:
| Layer | Technology | Details |
|-------|-----------|---------|
| Backend | PHP 8.2+ | Custom MVC framework with strict typing |
| Frontend | Vanilla ES6+ | Focused scripts without a frontend framework |
| Public CSS | Custom design system | BEM and utility classes |
| Admin CSS | Tailwind | Standalone admin build |
| Database | MySQL | Schema changes tracked with migrations |
| Server | LiteSpeed | With cache integration for production |
| Deployment | Custom pipeline | JSON content sync, PHP build script, Python deploy |
The original build used no npm. Its only build tool was the PHP minifier I wrote. The current admin area now adds a standalone Tailwind CLI.
## Architecture
The request flow is simple:
```
Request → index.php → Bootstrap → Router → Controller → View
↓
Service → Model → Database
```
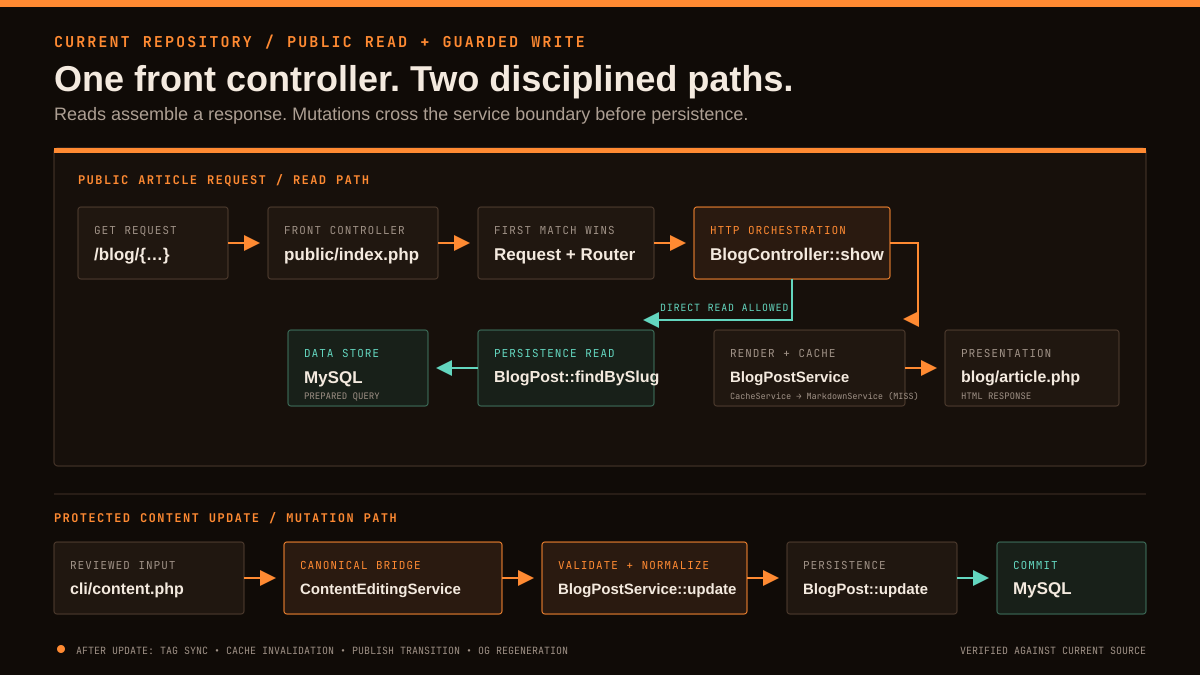
This is the current repository shape, not a generic MVC diagram. Public controllers can read models directly to assemble a response, while reviewed content updates cross ContentEditingService and BlogPostService before persistence. Markdown rendering is cached, with MarkdownService doing the conversion on a cache miss.
I kept the request flow simple, but I was strict about the boundaries between layers.
### Strict Layer Separation
Controllers handle HTTP. That's it. They extract request data, check authentication, and call services or models. They never contain business logic.
Services handle all mutations. Every create, update, and delete goes through a service that validates input, generates slugs, manages cache, and returns a `ServiceResult` object. Controllers never touch models directly for writes.
Models handle normal persistence and define the allowed columns. Application mutations go through services. A few infrastructure services, including migrations and content import, contain documented SQL where that job requires it.
The current create path, trimmed to the hand-off between controller and service, looks like this:
```php
// Admin\BlogController::store()
$result = BlogPostService::create($data);
if ($result->failed()) {
$this->error($result->errorString());
return $this->redirect(url('/admin/blog/create'));
}
// BlogPostService::create()
$data = self::normalizeData($data);
$errors = self::validate($data);
if (!empty($errors)) {
return ServiceResult::failure($errors);
}
```
This pattern made the codebase predictable. When something breaks, I know exactly which layer to look at.
### Feature Flags
The content-related flags currently cover the blog, tools, toolshed, guides, and news. When a flag is disabled, the router shows a "Coming Soon" page for public visitors, but the admin panel still shows everything. This means I can build and populate a new section privately, then flip a switch to launch it.
```ini
FEATURE_BLOG=true
FEATURE_TOOLS=true
FEATURE_GUIDES=true
FEATURE_NEWS=false
```
### Database Migrations
Newer schema changes use migration files with explicit UP and DOWN sections. The runner tracks batches and can roll back the latest one through the CLI or admin UI.
We introduced the migration system a few iterations into the build. Some early migrations predate the current format and need manual reversal, so rollback is a capability, not a guarantee.
### Content Pipeline
Blog posts are written in Markdown, stored in the database, and rendered to HTML at runtime. No pre-rendered cache. The content sync system exports everything to a JSON bundle (slug-based, not ID-based) that can be imported on production. View counts and analytics are never overwritten during sync.
## The Brutalist Design
I went with "Brutalist Bold." Dark backgrounds, 2px borders everywhere, zero border-radius, monospace fonts for labels and metadata, and Electric Lime (#D4FF00) as the accent color.

> **Heads up.** The site you're reading right now isn't this. The v1 brutalist build was replaced by a Station warm-noir design in April 2026. The full redesign story (four calendar days, one person, end-to-end) is in [Four Calendar Days, One Person, One Full Redesign](/blog/ways-of-working/four-days-one-person-redesign). The rest of this post is the original v1 build story, kept as-is.
Why brutalist? Two reasons.
First, constraints make decisions faster. When border-radius is 0, you never debate "should this be 4px or 8px?" When shadows aren't allowed, you use borders. When you only have one accent color, you don't waste time on color palettes. Every rule I added was one fewer decision to make.
Second, it looks distinctive. Most sites lean on rounded corners and soft gradients, so sharp edges stand out. The site doesn't look like a template because it isn't one.
### The Design Token System
Everything lives in `tokens.css`. Colors, spacing, font sizes, border widths, transitions. Components reference tokens only. Never a hardcoded value.
```css
/* tokens.css */
--color-primary: #D4FF00;
--color-bg: #0a0a0a;
--space-4: 1rem;
--space-8: 2rem;
--border-width: 2px;
--font-mono: 'JetBrains Mono', monospace;
```
The system supports dark/light themes and multiple accent colors (lime, cyan, rose) through CSS custom properties. Switching themes means changing token values, not rewriting components.
The v1 build ran to 48 CSS files and over 15,500 lines. Every component in its own file, utilities loading last so they override components. It was more CSS than most people would write for a personal site, but the token system kept it maintainable. The v2 redesign later consolidated a lot of it.

## Working With Claude Code
Everyone asks about this part.
### The Main Difference Was Speed
The clear difference was speed. Work I would estimate at a full day sometimes took one or two hours, including database queries, CSS structure, security controls, and deployment scripts. I still reviewed each result.
I could describe what I wanted in plain language and get working, production-quality code back. "Build me a service layer for blog posts with validation, slug generation, and cache invalidation." Done. "Create a migration system that supports rollback by batch." Done.
It was fast and patient, but I still owned the architecture and checked the code.
### The CLAUDE.md File
Early on, I discovered that Claude would "forget" architectural decisions across sessions. It would create a new button style when one already existed, or use a different pattern for error handling than what we'd established.
The fix was a detailed `CLAUDE.md` file at the project root. Design tokens, naming conventions, architectural rules, component inventory. Claude reads it at the start of every session. I also created 15 rules files in `.claude/rules/` covering everything from CSS standards to database conventions. (I dig into this more in [Claude Code and the context window on bigger projects](/blog/ai-tools/claude-code-context-window).)
The rules reduced repeated corrections and made Claude more consistent across sessions. They did not remove the need to review its work.
### Where Claude Struggled
**Over-engineering.** Claude tends to add more abstraction than needed. "Just a simple function" would come back with an abstract base class, two interfaces, and a factory. I spent a lot of time saying "simpler."
**CSS consistency.** Without strict rules, Claude would create duplicate CSS classes. A new card component when `.card-regular` already existed. New button variants when `.btn--primary` was right there. The rules files fixed this, but only after I'd cleaned up several rounds of duplicate styles.
**Design taste.** Claude doesn't have it. The brutalist aesthetic was entirely my vision. Claude executed it well once I explained what I wanted, but it would never have suggested "let's do 2px borders with no border-radius and lime green accents." Every visual decision was mine.
Two more were subtler. The first was context drift. On long sessions with many changes, Claude would sometimes lose track of earlier decisions. Keeping sessions focused on one task at a time helped. So did the rules files.
The second is harder to explain. I came to call them the stupid sessions. Sometimes Claude would just... stop working. Not crash. Not error out. It would keep responding, but the quality would fall off a cliff. Simple tasks it had handled fine an hour ago would produce nonsense. It ignored rules it had been following all session. It made changes that contradicted what it had just done.
My theory: context overload. After 30-45 minutes of complex work, something breaks down. The fix was surprisingly simple. Close everything. Walk away. Come back a few hours later, start a fresh session, and Claude would pick up exactly where it left off like nothing happened. No explanation. No apology. Just back to being competent.
It turned into a rhythm. Work intensely for 30-45 minutes. If Claude starts struggling with things it should know, don't fight it. Don't retry the same prompt five times hoping for a different result. Just stop. Fresh session later. It's frustrating in the moment, but it's faster than arguing with a confused AI for another hour.
### What Worked Well
**Natural language architecture.** I could say "the controller should only handle HTTP, the service should handle business logic" and Claude would implement that separation consistently across every controller and service it created.
**Refactoring at scale.** "Extract all category CRUD into a shared trait." Claude would read the existing implementations, identify the common patterns, create the trait, and update both services. In one pass.
**Security patterns.** Claude often suggested useful controls such as prepared statements, CSRF checks, and rate limits. I still treated those suggestions as code to review, not proof that the feature was secure.
## Why a personal site has this much code
The blog is only one part of the repository. The same codebase runs the tools directory, guides, search, accounts, a custom admin area, private analytics, content sync, and my publishing workflow. It is closer to a small CMS plus a personal operations layer than a simple blog.
### What Came After
The site kept growing after that initial build sprint. A few additions worth mentioning:
**Marketing calendar.** A full calendar view for scheduling social media posts across LinkedIn, Twitter, and Reddit. Drag posts between dates, toggle statuses with a click, link posts to blog articles. Built it in a single session.
**Admin notes system.** As an admin, I can leave notes on any page of the site. Sticky notes attached to URLs, basically. I browse the site, spot something that needs fixing or an idea for improvement, and drop a note right there. Later I export all notes, feed them to Claude Code, and work through them. It's how these very updates to this article happened.
**News aggregation.** An RSS-based system that pulls industry news from sources I curate, clusters related articles, and helps me stay on top of trends relevant to my writing.
Each took an afternoon with Claude Code, but only because I reviewed the output and corrected it as we went.
## What I'd Do Differently
**Set up the design token system from day one.** I started with ad-hoc CSS values and had to retrofit tokens later. Painful. If you're building a custom design system, define your tokens first.
**Shorter sessions.** Long Claude Code sessions led to context drift and inconsistency. Focused sessions (one feature, one PR, done) worked much better.
**Rules files earlier.** I created them after discovering inconsistencies. Should have started with a basic set from the beginning.
**Automate cache busting sooner.** Manual asset versioning was tedious. The build script handles it now, but I should have built that in week one.
**Budget time to understand what Claude builds.** This one caught me off guard. In a typical 30-45 minute session, Claude would build more than I asked for. Not in a bad way. It would see logical next steps and implement them. A service layer would come with cache invalidation I hadn't mentioned. A controller would include rate limiting I hadn't requested. Good additions, but I'd end up spending more time reading and understanding the code than it took Claude to write it.
Then I'd need to document the patterns in my rules files so Claude would stay consistent. Which took even longer.
> The writing was fast. The learning and documenting is what ate the time.
If you're using Claude Code for anything serious, accept that you need to understand what it's doing, how it's doing it, and why. You still own quality, documentation, and the decisions the next session needs to understand.
If you're considering building something with Claude Code, my one-sentence takeaway:
> Claude Code takes the tedious parts off your plate. Deciding what to build is still your job.
If you want a more structured walkthrough, I've put together a [Claude Code Guide](/guides/claude-code-guide) that covers a simpler path to a similar outcome.
---
# Claude Code and the context window on bigger projects
**Author:** Ivan Misic
**Published:** 2026-02-01
**URL:** https://ivanmisic.net/blog/ai-tools/claude-code-context-window
**In plain English**
On a large project, give each Claude Code session one task, name the likely files, and keep the project instructions current.
- Use `/context` to see what fills the window, `/clear` when the task changes, and `/compact` when the same long task must continue
- Name the file and visible problem so Claude starts in the right area instead of reading unrelated code
- Turn repeated review or maintenance instructions into project skills under `.claude/skills/`
- Break a large feature into small build and review steps, and use subagents only for independent analysis with a clear expected result
- Rename, move, or consolidate the source when repeated confusion shows the project structure itself is the problem
My website is now close to a thousand files, so I no longer ask Claude Code to "fix the page." I give each session one task and name the files involved, as similar components now exist in several folders.
## Context Management: Fresh Sessions
My first rule is to start a fresh session for each new task.
A new session loads the project instructions without the assumptions from the previous task. I use `/clear` when I want to reset the conversation in the same terminal. If the task must continue, `/compact` keeps a shorter version of the context. I choose a fresh session when the work changes, because old context can point Claude toward the wrong files or decisions.
Before deciding which of those I need, I run `/context`. It shows what is actually filling the window, and the answer is often one large file read rather than the conversation itself, which is a different problem with a different fix. In Claude Code v2.1.221 or later, `/autocompact` sets how many tokens to reserve before automatic compaction.
## Be Specific About Files
With five files, "fix the header" probably means one thing. With fifty files, it could mean any of ten different headers.
I name the file and the visible problem:
```text
In pages/contact.html, fix the header spacing. The heading is
too close to the navigation bar.
```
Not:
```text
Fix the header spacing.
```
Claude can search the project, but naming the likely file gives it a better starting point and avoids reading unrelated code.
## Reusable Skills Pay Off at Scale
I turn repeated project checks into skills, as I do not want the review criteria to change between sessions. For example:
- **review** runs the same code-review checklist
- **check-links** checks navigation and links
- **mobile** checks each page at mobile width
Put a repeated checklist in a project skill so the team can run the same review each time. Existing `.claude/commands` files still work, but new reusable workflows belong in `.claude/skills//SKILL.md`.
## Break Big Tasks into Steps
"Add a blog section to the website" is a big ask. It involves creating templates, styling, navigation updates, content, and possibly restructuring your project.
Break it into pieces:
```
Step 1: Create a blog listing page at blog/index.html that shows
a list of post titles and dates. Use the same style as the rest
of the site. No actual posts yet, just the listing page structure.
```
Review the first result before asking for the next part. Then continue with the second task:
```
Step 2: Create a template for individual blog posts at
blog/post-template.html. It should have the post title, date,
content area, and a back link to the blog listing.
```
Review that result, then continue with the next small task.
Each step is small enough to review thoroughly. If something goes wrong, you know exactly where it happened. If you need to undo, you only lose one step, not the whole thing.
## Agents for Big Analysis
When you need to analyze or check something across many files, tell Claude to use parallel agents (Module 2, Chapter 7):
```text
Use parallel agents to check all HTML pages for:
- Missing page titles
- Missing meta descriptions
- Broken image paths
- Links that don't go anywhere
Work through all files and give me one combined report.
```
Use separate subagents for independent checks, then combine their findings in the main session. They can run concurrently, but each uses its own context and increases token usage. Do not split work that needs the same files or a shared decision.
For a large change that can be split into independent units, `/batch` can plan 5 to 30 units and run each in its own Git worktree. It requires Git and gives each unit its own pull request, so I would not use it to rename one class. A normal search-and-replace is enough for that.
If a project grows past one repository, or into a monorepo, Anthropic's [guide for large codebases](https://code.claude.com/docs/en/large-codebases) covers how to lay out instructions and rules so the right ones load in the right place.
## CLAUDE.md Grows With Your Project
Small project CLAUDE.md:
```
Personal portfolio website. Dark theme. Four pages.
```
Bigger project CLAUDE.md:
```bash
# Portfolio & Blog
## Structure
- pages/ - Static pages (home, about, projects, contact)
- blog/ - Blog listing and posts
- css/ - Stylesheets (main.css, blog.css)
- images/ - All images
- js/ - JavaScript (if any)
## Design
- Dark theme (#0f172a background)
- Accent: #38bdf8
- Font: Inter
- Max width: 900px
## Important
- Blog posts use blog/post-template.html as the base
- Navigation is consistent across all pages
- New pages must include meta title and description
- All images go in images/ with descriptive names
```
Update `CLAUDE.md` when the structure or project rules change, so Claude starts each session with the current information.
## Signs Your Project Needs Structure Cleanup
I update the project structure when the same confusion appears more than once:
- Claude edits the wrong file because similar files have unclear names.
- I cannot find a file without searching several folders.
- The same style is defined in several places.
- `CLAUDE.md` no longer matches the current structure.
At that point I rename, move, or consolidate the source before adding more instructions.
When you notice these, ask Claude to help:
```
Audit the project structure. Are there files in the wrong places?
Duplicate styles? Anything that would confuse someone seeing
this project for the first time? Suggest improvements.
```
## How I Work on a Big Project
I also break every big feature into small tasks. "Add a tools section" becomes: create the model, create the controller, create the listing view, create the detail view, add the routes, update navigation. Each task gets its own session.
I no longer try to cover the whole project in one session. One task per session works, provided the project instructions are current.
## Frequently Asked Questions
### How do I see what is filling Claude Code's context window?
Run `/context`. It shows what is taking up the window. Often it is one large file, not the conversation, so the fix is different.
### What is the difference between /clear and /compact?
`/clear` gives you an empty context and saves the previous conversation so you can resume it later. Project instructions load again. `/compact` keeps a shorter version of the current context, which is what you want when the same long task has to continue. I use `/clear` when the work changes.
### Does Claude Code read every file in my project?
No. It searches and reads the files the current task needs, which is why naming the likely file gives it a better starting point than a general description of the problem.
### How do I stop Claude Code from editing the wrong file?
Name the file and the visible problem in the same sentence. On a project with fifty files, "in pages/contact.html, fix the header spacing, the heading is too close to the navigation bar" leaves far less room for interpretation than "fix the header spacing."
### When are subagents worth using?
Use them for independent checks that can run at the same time, then combine the findings in the main session. Each subagent carries its own context and adds token usage, so do not split work that needs the same files or a shared decision.
## Sources
- [Commands](https://code.claude.com/docs/en/commands), Anthropic. Documents `/context`, `/clear`, `/compact`, `/autocompact`, and the Git, worktree, and unit requirements of `/batch`.
- [Explore the context window](https://code.claude.com/docs/en/context-window), Anthropic. Explains what enters context, automatic compaction, and what survives compaction.
- [Create custom subagents](https://code.claude.com/docs/en/sub-agents), Anthropic. Supports separate subagent context windows and the return of summarized results to the main session.
- [Set up Claude Code in a monorepo or large codebase](https://code.claude.com/docs/en/large-codebases), Anthropic. Supports structuring project instructions and rules for large repositories and monorepos.
---
# Saving your work with Git and going live
**Author:** Ivan Misic
**Published:** 2026-01-31
**URL:** https://ivanmisic.net/blog/ai-tools/saving-work-going-live
**In plain English**
Keep a recoverable copy before publishing, then choose a hosting route after checking its current plan, repository support, domain setup, and build behavior.
- A dated zip stored off the computer is enough for the first restore point; open it once to prove the backup works
- Use Git when you want named history, inspectable changes, and reliable rollback
- Repository-based hosts can deploy after a push when that integration is configured; traditional hosting uses manual uploads
- Provider pricing, free-plan limits, custom-domain costs, and deployment times change, so verify them before choosing
- Inspect the exact public files, then test the deployed URL in a private browser window and click every page
Two problems to solve. First: don't lose your work. Second: let other people see it.
Before publishing, keep a copy you can restore. A deleted folder, failed disk, or bad Claude edit should not send you back to the beginning.
## The Simple Way: Zip Backups
Create a dated zip before a large change so you can restore the project quickly:
```text
Create a zip file of this entire project called
my-portfolio-backup-2026-08-12.zip. Save one copy outside this
computer, such as an external drive or a cloud folder.
```
Replace the date with today's date. Now you have a snapshot. If something goes wrong, you can extract the zip and start fresh from that point.
If you keep forgetting the backup, ask Claude to make the command repeatable:
```text
Create a simple backup script that zips this project with today's
date in the filename. Ask me where the off-device backup should go,
then make the script easy to run again.
```
Run the script once and confirm that the archive opens. A backup you have never tested is only a promise.
## When to Back Up
Create a backup:
- Before making big design changes
- After each page is finished
- When everything looks good and you want to lock it in
- At the end of every work session
For a small site, keep a few dated versions that you know work. Delete old duplicates after the important versions also exist somewhere outside this computer.
## When Git is worth it
Git records named versions of your project and shows exactly what changed between them. You can compare commits or restore an earlier version when an experiment fails.
Git and GitHub are different things:
- **Git** is a tool that runs on your computer. It tracks changes locally.
- **GitHub** is a website where you store your Git history in the cloud.
Git creates the history on your computer. GitHub stores a remote copy and can share or publish it.
### Key Terms (Just Four)
| Term | What It Means |
|------|--------------|
| **Repository** | Your project folder, tracked by Git. Often called a "repo." |
| **Commit** | A snapshot you choose to record, with a message explaining the change. |
| **Push** | Upload your commits from your computer to GitHub. |
| **Pull** | Download commits from GitHub to your computer. |
Those four terms are enough for this workflow.
### Setting It Up
If you want to use Git:
```text
Help me set up Git for this project. Walk me through:
1. Initializing a Git repository
2. Making my first commit
3. Creating a GitHub account if I don't have one
4. Pushing my project to GitHub
```
You will have a local Git history and a remote copy on GitHub. Check whether the repository is public or private, review the files before the first push, and never push credentials or personal data.
### Why Bother?
For a first experiment, I would start with a zip. Git becomes worth learning when you want a clear history or automatic deployment:
1. **Repository-based hosting.** GitHub Pages, Netlify, and Vercel can publish a static site from a Git repository. Plan limits and repository requirements vary.
2. **Safer experiments.** Make a commit before a redesign. If it fails, restore that version instead of guessing which zip still works.
## Going Live: Putting Your Site on the Internet
For a static site, I would compare GitHub Pages, Netlify, and Vercel before paying for traditional hosting.
### Repository-Based Hosting
GitHub Pages, Netlify, and Vercel can publish a static site from a Git repository. Free-plan limits, private-repository support, build times, and custom-domain features change, so check the current plan before choosing.
```text
Help me deploy my website to Netlify using my GitHub repository.
Walk me through connecting my repo and getting a live URL.
```
### Custom Domains
If you want `yourname.com` instead of `yourname.netlify.app`, you need two things:
1. **A domain name.** Prices vary by extension, registrar, and renewal year.
2. **Hosting with custom-domain support.** Check the current plan before choosing.
Traditional shared hosting may bundle a domain, email, and file hosting. I would compare the renewal price and current plan before choosing it.
### Which Should You Choose?
| Situation | Recommendation |
|-----------|----------------|
| Just want something live quickly | Compare GitHub Pages, Netlify, and Vercel for your repository |
| Want a custom domain, minimal fuss | Buy the domain separately and connect it to a supported host |
| Want traditional hosting with email | Shared hosting (Hostinger, etc.) |
| Already have a domain somewhere | Connect it to whichever host you prefer |
When you're ready:
```text
Help me put my website on the internet. I want [your preference].
Walk me through the steps.
```
Before accepting Claude's steps, check the provider's current plan and deployment documentation.
## Keeping Your Site Updated
After your site is live, the update workflow depends on your setup:
### If using GitHub with Netlify or Vercel
1. Make changes locally
2. Test in your browser
3. Commit and push to GitHub
4. Wait for the provider's deployment to finish, then test the public URL
### If using traditional hosting
1. Make changes locally
2. Test in your browser
3. Upload changed files via FTP or your host's file manager
I would use repository-based deployment once Git is set up. Traditional hosting avoids Git, but every update stays a manual upload.
Open the public URL in a private browser window, click every page, and confirm that no private file was published.
> Next: the habits that keep Claude Code from doing damage in the first place.
## Sources
- [Git: Recording Changes to the Repository](https://git-scm.com/book/en/v2/Git-Basics-Recording-Changes-to-the-Repository), Git project. Explains staging and recording project snapshots as commits.
- [What is GitHub Pages?](https://docs.github.com/en/pages/getting-started-with-github-pages/what-is-github-pages), GitHub. Supports publishing a static HTML, CSS, and JavaScript site from a GitHub repository.
- [Create deploys](https://docs.netlify.com/deploy/create-deploys/), Netlify. Supports linking a Git repository and creating deploys from pushes or manual uploads.
- [Deploying Git Repositories with Vercel](https://vercel.com/docs/git), Vercel. Supports connected Git repositories and automatic preview and production deployments from pushes and merges.
---
# Making it look good (and fixing what doesn't)
**Author:** Ivan Misic
**Published:** 2026-01-31
**URL:** https://ivanmisic.net/blog/ai-tools/making-it-look-good
**In plain English**
On this site, building the page structure was the short part. I spent much longer refining the colors, type, spacing, content, and interaction details. Change one visible problem at a time, keep the written design rules updated, and check the page on a phone as well as a desktop. Stop when you can share the link without explaining unfinished work, then improve it later.
A working site is not a finished design. Once the pages and navigation worked, I started refining how the content was read.
On this site, the first structure took a few days. I spent the next couple of weeks refining color, type, spacing, and the details that made it feel like mine.
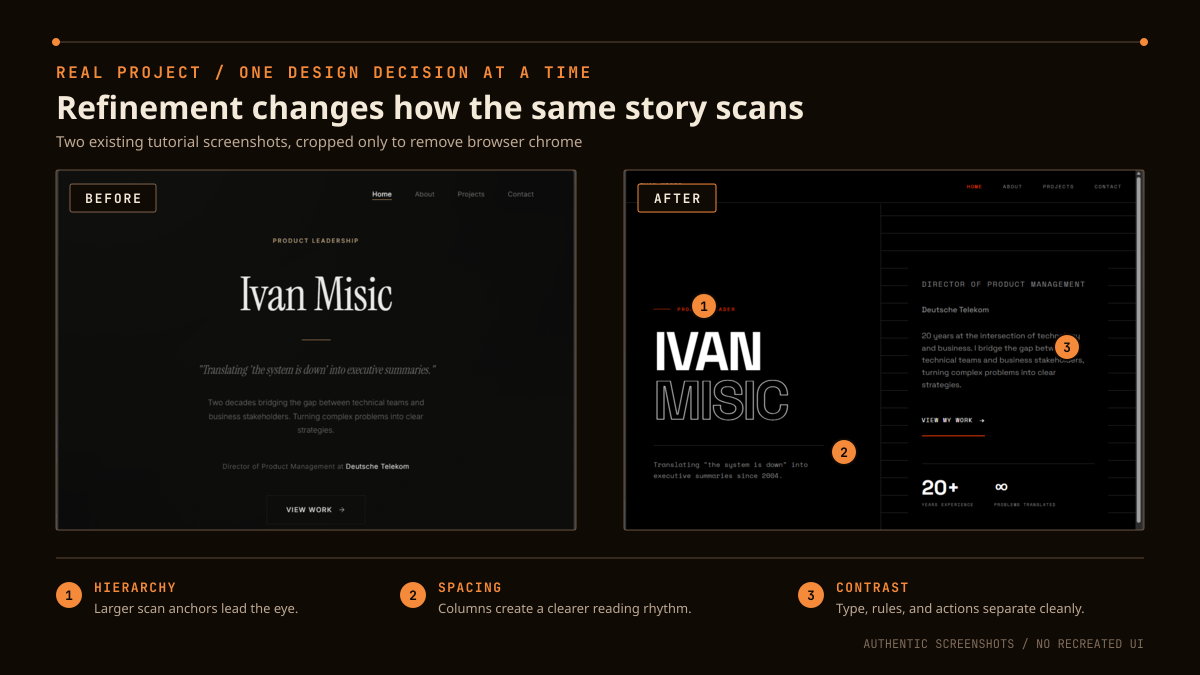
These are two real versions of the same portfolio homepage. Refinement strengthened the scan hierarchy with scale, separated the story into clearer columns, and reserved brighter contrast for structure and action. The content did not need reinvention; its reading order needed sharpening.
## Check Your Design Rules First
Before making changes, remind yourself what you already decided. You created `.claude/rules/css.md` in the previous chapter. Open it. Those are your standards.
When you want to change something, ask yourself: does this fit the rules, or am I starting fresh?
If you're refining within your existing design system, tell Claude:
```text
Following our design rules in .claude/rules/css.md, make the
heading text bolder and add more space between sections.
```
If you're deliberately changing the rules, update the rules file too:
```text
Change the accent color from #ff6b35 to #38bdf8 on all pages.
Then update .claude/rules/css.md to reflect this change.
```
This keeps your design consistent as you refine.
## Colors
Choose exact colors before making more page-level changes, so Claude applies the same system everywhere.
Tell Claude what you're going for:
```text
Update the color scheme across all pages:
- Background: #0f172a (very dark blue)
- Main text: #e2e8f0 (light gray)
- Headings: #ffffff (white)
- Accent/links: #38bdf8 (sky blue)
- Muted text: #94a3b8 (medium gray)
Update .claude/rules/css.md with these colors.
```
Specific hex codes (those # numbers) give you exact control. If you don't know hex codes, describe the colors and let Claude pick:
```text
I want a dark theme. Navy blue background, not black. Warm white
text, not harsh white. Accent color should be a calm blue.
```
Claude will choose appropriate hex codes. If they're not quite right, adjust: "The accent blue is too bright, make it softer."
## Typography
For a first site, I would choose either one hosted font or the system font stack:
**Option 1: Use Google Fonts (free)**
```text
Use the Inter font for everything. Load it from Google Fonts.
Headings should be bold, body text regular weight.
```
**Option 2: Use system fonts (no loading required)**
```text
Use the system font stack for everything. That means the site uses
whatever font the visitor's computer has. Fast and clean.
```
Either works. Google Fonts gives you more control over the exact look. System fonts require no font download and use the type already available on the visitor's device.
Specific typography instructions that make a difference:
```text
Update the typography:
- Headings: uppercase, bold, slightly wider letter spacing
- Body text: 18px size, 1.7 line height (space between lines)
- Navigation links: small, uppercase, medium weight
```
## Spacing
When a page feels cramped, I check the spacing before changing the layout. It is often the smaller fix.
Common spacing fixes:
```text
Add more space between sections. Right now they feel too close together.
Each section should have at least 80px of space above and below it.
```
```text
The navigation feels crowded. Add more space between the links
and more padding around the entire nav bar.
```
```text
The text in the about section is too close to the edges.
Add more padding on the left and right, especially on mobile.
```
If spacing does not help, check the hierarchy and copy before rebuilding the layout.
## Real Content Polish
Now that the design is taking shape, look at your actual content:
- **Is the text too long?** Read each page as a visitor looking for one answer. Shorten the parts that delay it, and use bullets only when the content is a real list.
- **Is the text too short?** A three-word "About" section looks incomplete. Add enough to give visitors a real sense of who you are.
- **Does the tone match the design?** A playful design with corporate text (or vice versa) feels off.
You can ask Claude to help:
```text
The about page text is too formal. Rewrite it to sound more
conversational and approachable while keeping the same information.
```
But don't outsource everything. The content that sounds like you is the content you write (or at least heavily edit).
## Details That Matter
After the hierarchy, type, color, and spacing work, check the interaction details:
Add hover states to links and buttons:
```text
When I hover over navigation links, they should change to the accent
color with a smooth transition. Same for buttons.
```
Mark the current page in the navigation:
```text
In the navigation, the link for the current page should look different.
Maybe underlined or in the accent color, so visitors know where they are.
```
If the site needs contact, legal, or secondary links on every page, put them in a consistent footer:
```text
Add a simple footer at the bottom of every page with my name,
the year, and links to my social profiles.
```
A favicon is the small icon in the browser tab:
```text
Create a simple favicon. Just my initials in the accent color
on a dark background. Save it as favicon.ico in the root folder.
```
## When to Stop
Stopping is harder than starting. My rule is simple: **ship when I would not be embarrassed to share the link.**
It does not need to be perfect. It needs to be good enough that I would send the URL without explaining what is still unfinished.
Signs you should stop tweaking and move on:
- You're adjusting the same thing back and forth ("make it bigger, no smaller, no back to bigger")
- Changes are getting smaller (2px adjustments)
- You've been working on the same page for more than an hour
- You start thinking "I should redesign everything from scratch"
So stop and ship it. You can improve it later.
## How I Refined This Site
I spent a few days building the first version of this website (including the backend, CMS, and all the infrastructure) and a couple of weeks refining it. I'm still tweaking things on weekends. "Increase the gap between the nav and the hero section by 20px." "Make the footer links slightly brighter." "Reduce the border thickness on cards from 3px to 2px."
Claude can make a CSS change in seconds or minutes. Deciding whether it looks right takes me longer, and I still review the result on different screen sizes.
> Next: what to do when something breaks, and how to fix it without going in circles.
---
# Claude Code permissions: what to allow and what to block
**Author:** Ivan Misic
**Published:** 2026-01-27
**URL:** https://ivanmisic.net/blog/ai-tools/claude-code-permissions
**In plain English**
Claude Code can edit real files and run commands, so limit what it can reach and keep a way to undo mistakes. Stay in Manual mode while learning, and use Plan mode to inspect larger changes before editing. Use deny rules, hooks, a sandbox, or operating-system permissions when an action must be blocked, because instructions in `CLAUDE.md` are guidance rather than a hard barrier. Before I publish, I inspect the changed and staged files, test the result, and keep three ways back: checkpoints for tracked session edits, Git for history, and an off-device backup for disk loss.
Trust Claude. But verify the important stuff.
Claude Code can read files, edit them, and run commands in the environment you give it. That is why it is useful, and why a good prompt is not your safety control.
My project instructions say never to commit `.env` files. I still check before publishing. I also save a checkpoint before structural changes. It costs me seconds and has saved me hours.
My rule is simple. Limit the scope, check the change, test it, and keep a way back.
## Check the permission mode first
The permission mode decides how often Claude stops to ask. It is the first thing to check, because it changes what a careless prompt can do.
| Mode | Runs without asking | Use it for |
|---|---|---|
| Manual (`default`) | Reads only | Learning, and anything sensitive |
| `acceptEdits` | Reads, file edits, common file commands | Iterating on changes you are reviewing |
| `plan` | Reads and exploration commands; source edits stay blocked until you approve a plan | Exploring before you change anything |
| `auto` | Everything, with background safety checks | Long tasks, when you accept less oversight |
| `dontAsk` | Only tools you pre-approved | Scripted and locked-down runs |
| `bypassPermissions` | Everything | Isolated containers and virtual machines only |
`Shift+Tab` cycles Manual, `acceptEdits`, and `plan` in the CLI, plus any other mode you have enabled. The status line under the input shows which one is active. Other Claude Code surfaces use a mode selector.
Stay in Manual mode while you are learning. The last two rows are not beginner settings, and `bypassPermissions` belongs on a machine you would not mind rebuilding.
For a structural change, enter Plan mode with `/plan` or cycle to it with `Shift+Tab`. Plan mode lets Claude inspect the project and propose an approach without editing source files.
I use it when the task touches several files or changes the project structure. My prompt is usually close to this:
```text
Explain the approach, files you expect to change, risks, and checks.
Do not edit anything yet.
```
Review the proposal before switching to an editing mode. A sensible plan does not guarantee a safe implementation, but it catches a wrong direction before files move.
Anthropic documents the current behavior in [Claude Code permission modes](https://code.claude.com/docs/en/permission-modes).
## Instructions are not enforcement
Put project rules in `CLAUDE.md` so Claude sees your intent. For example:
```markdown
## Sensitive files
- Never read, display, edit, or commit .env files
- Never put credentials or customer data in source files
- Ask before changing authentication or deployment configuration
```
This helps Claude follow the rules, but it does not protect the files. Instructions are context, and context can lose an argument with a confident plan.
When something must never happen, use a control the client enforces rather than one Claude interprets:
- **Deny rules** in your settings block a tool, command, or path outright, in every mode. This is the real answer to the `.env` example above.
- **[Hooks](https://code.claude.com/docs/en/hooks)** run your own shell command at a fixed point, such as before every tool call, and can refuse the action regardless of what Claude decided.
- **[`/security-review`](https://support.claude.com/en/articles/11932705-automated-security-reviews-in-claude-code)** checks the current changes for vulnerabilities before you ship them. Worth running on anything that handles input, authentication, or money.
Rules in `CLAUDE.md` express intent. Deny rules and hooks express a limit. Use the first for the hundred small conventions and the second for the two or three things that would actually hurt.
Keep secrets outside the repository, ignore local configuration, and limit which credentials are available to the session. Before a push, inspect the exact staged files:
```bash
git diff --cached
```
Confirm that `.env`, local settings, exported data, and generated credentials are not included. Use secret scanning or repository push protection when available.
If a real credential was already pushed, rotate or revoke it first. Removing the text from Git history does not make the old credential safe. GitHub's [sensitive-data guidance](https://docs.github.com/en/authentication/keeping-your-account-and-data-secure/removing-sensitive-data-from-a-repository) covers the recovery order.
## Let the operating system hold the boundary
Approving each command works while you are learning, but it wears thin. Claude Code has a [sandbox for the Bash tool](https://code.claude.com/docs/en/sandboxing) that changes the deal: instead of approving commands one at a time, you configure which files and network domains sandboxed Bash commands may touch, and the operating system enforces it for every command and anything it starts.
Open it with:
```text
/sandbox
```
The panel tells you what is available on your machine and what is missing. It runs on macOS, Linux, and WSL2. Native Windows is not supported, so on Windows this means running Claude Code inside WSL2.
What you gain is a boundary that stops depending on you reading every command carefully at the end of a long session. Fewer prompts is the side effect.
## Review the change, not the promise
When Claude says a task is complete, inspect what changed.
For a small visual adjustment, open the page at the relevant width. For a code change, run the existing tests and read the diff. For a configuration change, confirm the exact keys and environment it affects.
If you do not understand part of the diff, ask:
```text
Explain this change in plain English, including what could break.
Do not make another edit.
```
The explanation can help, but you still need to test the change.
Specificity reduces the chance that Claude changes the wrong thing. It does not make a change safe. “Remove the gap between the footer links and copyright text” is better than “clean up the footer,” but I still review the diff and open the page.
## Keep separate recovery layers
Save a local checkpoint before a risky edit, commit a known-good version when using Git, and keep an off-device copy for disk loss. Each one protects you from a different problem.
A [checkpoint](https://code.claude.com/docs/en/checkpointing) can rewind file edits tracked in the current session; it does not replace Git or cover every Bash, subagent, or external change. Git explains what changed across versions. An off-device copy protects you when the computer or disk is gone.
One backup file beside the project does not cover all three.
## Start a fresh session when the task changes
Long conversations collect decisions, failed attempts, and instructions from earlier work. When the task changes, that context can pull the next answer in the wrong direction.
I use one task per session as a default. A new session reloads project instructions and drops the previous conversation. Claude then searches and reads the files needed for the new task. It does not scan every file in the project automatically.
The current instruction-loading behavior is documented in [Claude Code memory](https://code.claude.com/docs/en/memory).
Start a new session when:
- you move to an unrelated task
- Claude keeps repeating an approach you rejected
- old requirements conflict with the current work
- you want a clean review of the result
## Review what you publish
The `.claude` directory is not automatically secret. Shared project rules may be safe and useful to publish. Local settings, hooks, prompts, and examples can still reveal home-directory paths, internal systems, or client details.
Review it like any other directory. Before publishing, I check the exact staged files. The folder name and Claude's confirmation are not enough.
## When Claude is wrong
Test the behavior first. If it fails, give Claude the exact result, error, and reproduction step. If the same approach keeps failing, restore the known-good state and start a new session with the evidence you now have.
Do not let five speculative fixes accumulate. One change, one check. That keeps the failure understandable.
Claude's capability and your judgment work well together. Remove the review and recovery layer, and you are only making mistakes faster.
## Frequently Asked Questions
### Does Claude Code ask permission before every change?
That depends on the permission mode. Manual mode runs reads on its own and asks before other actions unless a permission rule already decides them. `acceptEdits` also approves file edits and common file commands. `bypassPermissions` skips most prompts, but explicit ask rules and a few safety checks still apply. The status line under the input shows which mode is active, so check it before you start.
### Which permission mode should I use?
Stay in Manual while you are learning, and switch to Plan mode when the task touches several files or changes the project structure. Reserve `bypassPermissions` for an isolated container or virtual machine you would not mind rebuilding.
### Can CLAUDE.md stop Claude Code from touching my .env file?
No. Project instructions tell Claude what you want, but they are not enforcement. A deny rule or a hook can block matching tool calls. If every subprocess must be unable to reach `.env`, use the sandbox or operating-system permissions, because path rules do not cover every program Claude can run.
### How do I check that Claude Code has not staged a secret?
Run `git diff --cached` before you push and read the exact list of staged files. If a real credential has already been pushed, rotate or revoke it first, because removing the text from Git history does not make the old credential safe.
### Is the .claude directory safe to publish?
Not automatically. Shared project rules are often fine to publish, while local settings, hooks, and prompts can expose home-directory paths, internal systems, or client details. Review it like any other directory before it goes public.
## Sources
- [Choose a permission mode](https://code.claude.com/docs/en/permission-modes), Anthropic. Defines the current permission modes, mode switching, and the fact that deny rules still apply in bypass mode.
- [Configure the sandboxed Bash tool](https://code.claude.com/docs/en/sandboxing), Anthropic. Documents the sandbox's filesystem and network boundaries, platform support, and Bash-only scope.
- [Hooks reference](https://code.claude.com/docs/en/hooks), Anthropic. Documents `PreToolUse` decisions that allow, deny, or ask before a tool call runs.
- [Checkpointing](https://code.claude.com/docs/en/checkpointing), Anthropic. Defines what checkpoints capture, how long they remain available, and what they do not cover.
- [How Claude remembers your project](https://code.claude.com/docs/en/memory), Anthropic. Explains how `CLAUDE.md` and memory are loaded as context rather than hard enforcement.
- [Automated Security Reviews in Claude Code](https://support.claude.com/en/articles/11932705-automated-security-reviews-in-claude-code), Anthropic. Documents `/security-review` and says it complements rather than replaces manual review.
---
# Fixing bugs with Claude Code (without losing your mind)
**Author:** Ivan Misic
**Published:** 2026-01-27
**URL:** https://ivanmisic.net/blog/ai-tools/fixing-bugs-without-losing-mind
**In plain English**
Give Claude Code a reproducible bug: what you did, what you expected, and what happened. Let it inspect the relevant files and explain the proposed change, then test the same case again.
- For a visual problem, include the page, viewport, expected result, and a screenshot
- For a behavior problem, reproduce it in the browser console and copy only the relevant error and surrounding lines
- Remove tokens, email addresses, personal data, and private URLs before sharing logs
- Review the proposed cause and diff, then test the original case and nearby behavior after each change
- If the same approach fails twice, stop patching, ask for a new diagnosis, and keep a checkpoint, backup, or Git restore point before larger changes
When the navigation on my site overlapped the content on mobile, I pasted a screenshot into Claude Code and described what should happen instead. Claude found the CSS rule, but I still reviewed the change and tested several screen widths. I use the same loop for most bugs.
## The Bug-Fixing Workflow
My debugging loop has five steps:
1. **Describe** what's wrong
2. **Show** the problem (screenshot if visual)
3. **Let Claude investigate** and propose a fix
4. **Review** the proposed change
5. **Test** the fix
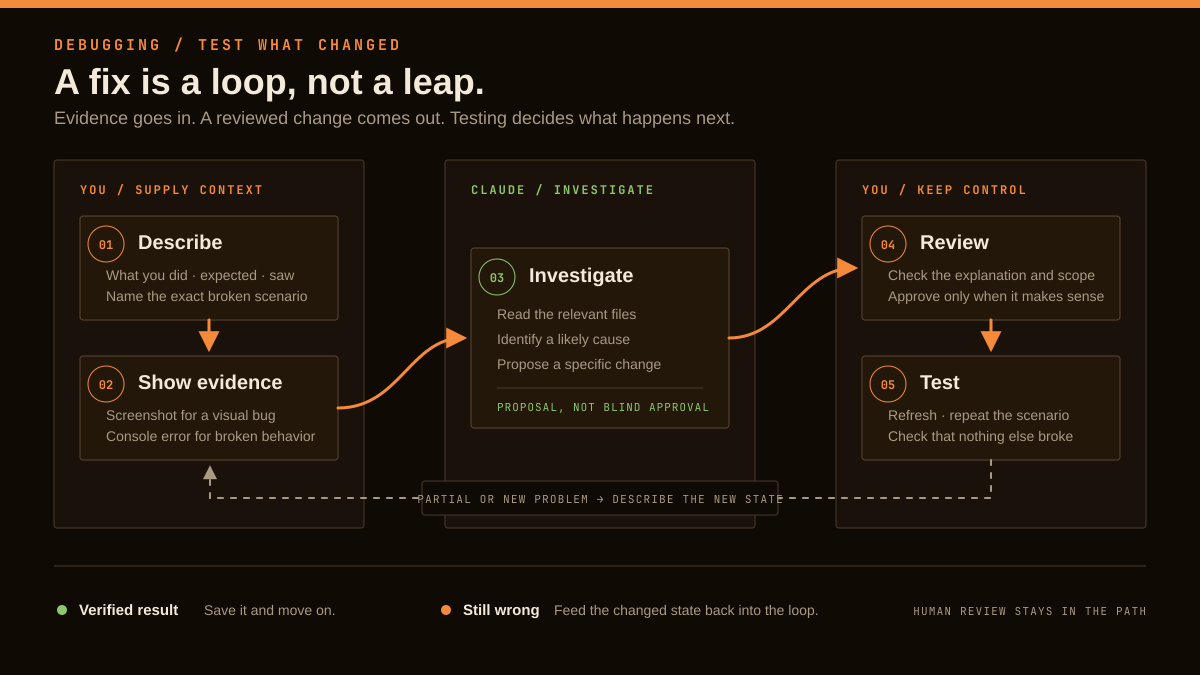
The important split is responsibility. You supply the observed behavior and decide what to approve; Claude investigates and proposes. Testing closes the loop. If the result is partial, the changed state becomes the next bug report.
Start with the broken state.
## Step 1: Describe What's Wrong
A good bug description has three parts:
- **What you did:** "I opened the about page on my phone"
- **What you expected:** "The text should be readable and properly spaced"
- **What actually happened:** "The heading overlaps the navigation and the text runs off the side of the screen"
Give all three. Claude can work with less, but more context means a faster fix.
### A useful description
```text
On the about page, when I view it on my phone (or narrow the browser
to phone width), the heading text is too big and overlaps the
navigation bar. The body text also runs off the right side of the screen.
```
### A vague description
```text
The about page is broken on mobile.
```
The first description gives Claude a reproducible case. The second makes it guess what "broken" means, so investigation usually takes longer.
## Step 2: Show the Problem
For visual bugs, take a screenshot of the broken page and paste it into Claude Code using the shortcut shown for your terminal:
```text
[pasted screenshot]
This is what the about page looks like on my phone. See how the
heading overlaps the nav? And the text goes off-screen on the right?
Fix this.
```
Add the page, viewport, expected result, and what looks wrong. The image reduces ambiguity, but Claude still needs to inspect the relevant HTML and CSS, and you still need to test the change.
## Step 3: Let Claude Investigate
Ask Claude to inspect the relevant files, explain the likely cause, and propose a change before editing. You may see something like:
```text
The issue is in css/styles.css. The heading font size is set to 4rem
which is too large for small screens. There's also no max-width on
the text container, so it can overflow.
I'll fix both issues:
1. Add a responsive font size for the heading on small screens
2. Add overflow handling to the text container
Allow changes to css/styles.css? [y/n]
```
Review what Claude wants to change. Does it make sense? If you're not sure, ask:
```text
Before you make the change, explain what this fix does in
plain English.
```
## Step 4: Test the Fix
After Claude makes the change, check it yourself:
- Refresh the browser
- Test the specific scenario that was broken
- Check that nothing else broke in the process
If the result is partial or creates another problem, report the new state before Claude makes another change:
```text
The heading is fixed but now the body text has too much space
on the left side. There's a big gap between the text and the
edge of the screen.
```
Another round. Describe what's still wrong. Claude adjusts. Test again.
## The Browser Console Trick
Sometimes bugs aren't visual. A button doesn't work. A form doesn't submit. Something that should happen when you click doesn't.
Your browser has a built-in error log called the Console. Open the browser's developer tools, choose Console, and reproduce the bug. Copy the relevant error and a few surrounding lines. Remove tokens, email addresses, personal data, and private URLs before pasting the log into Claude Code:
```text
When I click the submit button on the contact form, nothing happens.
Here's the error from the browser console:
[paste the relevant console error here]
Fix this.
```
The console error gives Claude a starting point. Ask it to trace the error to the code, explain the proposed change in plain English, and show how to test that the bug is gone.
## Common Bug Categories
Most bugs fall into predictable categories:
| Symptom | Likely Cause | What to Tell Claude |
|---------|-------------|-------------------|
| Things overlap or look wrong | CSS/styling issue | Screenshot + "these elements should be [how you want them]" |
| Links go to wrong page | Wrong URL in the HTML | "The About link goes to contact.html instead of about.html" |
| Page looks different on phone | Missing responsive styles | "This page looks broken on mobile" + screenshot |
| Something doesn't work when clicked | JavaScript error | Console error + "this button should [what it should do]" |
| Page loads slowly or not at all | Missing file or wrong path | "The page shows [what you see] instead of [what you expect]" |
## When the Fix Doesn't Work
The first fix may be wrong, so test the same case after every change.
```
That didn't fix it. It looks like this now:
[new screenshot]
The heading is better but the text is still overflowing.
```
Give Claude the new state after each attempt. If the same approach fails twice, stop patching and ask it to explain the cause or propose a different fix.
If you're going in circles (fix, break, fix, break), try a different approach:
```
Let's take a different approach. Instead of fixing the current CSS,
show me a simple, clean layout for this page that works on all
screen sizes. Replace the current styles for this section.
```
If two changes fail for the same reason, I would stop patching and ask for a simpler replacement for that section.
## Recovery: Save Before Big Changes
A snapshot does not prevent the bug, but it limits the recovery cost.
Claude Code takes a checkpoint before each prompt you send, so a recent mistake is usually one `/rewind` away. Run it, or press `Esc` twice with an empty input, pick the prompt from before the problem, and choose whether to restore the code, the conversation, or both.
Claude Code keeps snapshots for the 100 most recent checkpoints in a session and saves them with the conversation for up to 30 days by default. Checkpointing still covers only direct file edits, not changes made by shell commands. Before a large change, ask for a copy you own:
```
Zip this project into a dated backup before we start the redesign.
```
The next chapter sets up Git for durable file history. It complements checkpoints and still does not replace an off-device backup.
Claude can search the code and propose a change, but I still decide what correct means and verify the result.
> Next up: save a version you can restore, then publish the site.
## Sources
- [Common workflows](https://code.claude.com/docs/en/tutorials), Anthropic. Documents adding screenshots through drag and drop, clipboard paste, or an image path.
- [Checkpointing](https://code.claude.com/docs/en/checkpointing), Anthropic. Supports per-prompt checkpoints, rewind actions, retention, and shell-command limitations.
- [Git: Recording Changes to the Repository](https://git-scm.com/book/en/v2/Git-Basics-Recording-Changes-to-the-Repository), Git project. Supports commits as durable, chosen snapshots in local version history.
---
# Adding pages to your website with Claude Code
**Author:** Ivan Misic
**Published:** 2026-01-25
**URL:** https://ivanmisic.net/blog/ai-tools/building-the-rest
**In plain English**
Use the reviewed home page, requirements, and CSS rules as references, then build one remaining page at a time. After each page, check its content, navigation, spacing, and mobile layout in the browser before creating the next one. Update the requirements when the plan changes, keep shared styles and components consistent, and test all pages at desktop and phone widths. Written rules reduce drift, but the rendered pages are the proof.
Build the remaining pages one at a time, using the home page and written design rules as the reference. Each page should be faster, but longer content and smaller screens can still expose a missing rule.
## Build Pages One at a Time
I would finish and review one page before creating the next, as each page can expose a missing design rule.
Give Claude the requirements, design rules, and an existing page to compare against:
```text
Create about.html based on:
- Page requirements from _docs/requirements.md
- Design rules from .claude/rules/css.md
- Same header and footer as index.html
```
The existing page gives Claude a concrete reference, but I would still check the content, navigation, spacing, and mobile layout.
## Building Each Page
Use the same prompt for each page, changing only the page name and any page-specific requirements:
```text
Create [page-name].html based on:
- Requirements from _docs/requirements.md
- Design rules from .claude/rules/css.md
- Same header and footer as index.html
```
After each page, open it in your browser. Does it match the home page style? If something looks off, run the iteration loop:
```text
The spacing on the about page is different from the home page.
Make the section padding match what we have on index.html.
```
If you realize your requirements were missing something, update `_docs/requirements.md` first, then tell Claude to rebuild the page with the updated requirements. Keep your documentation as the source of truth.
In this walkthrough, one creation prompt produced each remaining page. The pages still needed the review and correction loop below:
### Why This Went So Fast
The remaining pages were faster because they reused the home-page design. In this walkthrough, one prompt created each page, but I still reviewed and corrected the rendered result.
Karpathy's original "vibe coding" description involved letting the model write code without paying much attention to it. This workflow is more controlled: write down the outcome, review each page, test it, and correct the result.
The written files reduce repeated explanation. They are a reference for review, not proof that Claude followed every instruction.
If the project text already exists, include it in the prompt. Otherwise use temporary content, but review the layout again when the real text is added because its length will change the page.
## Navigation Should Work
After all pages exist, check the navigation. Click every link on every page. Each one should take you to the right page, and the navigation should appear consistently on all of them.
If a link doesn't work:
```text
The "About" link on the home page goes to the wrong URL.
It should link to about.html.
```
If the navigation looks different on different pages:
```text
The navigation on contact.html looks different from the other pages.
Make it match index.html exactly.
```
If navigation styling is inconsistent:
```text
Check all pages. The current page should be highlighted in
the navigation. On about.html, the "About" link should look
different to show it's the active page.
```
## Making It Work on Phones
Test every page at a narrow browser width. The home page can work while longer headings or content break another page.
If things look broken:
```text
The website looks broken when the browser is narrow (phone-sized).
Make the layout responsive:
- Navigation should collapse to a hamburger menu on small screens
- Headings should be smaller
- Sections should have less padding
- Images should scale down
- Nothing should go off-screen
```
"Responsive" means "works at different screen sizes." You do not need to write the responsive CSS yourself. You do need to describe what should happen, test every page at narrow widths, and understand the proposed change well enough to reject a bad result.
At narrow width, check the longest heading, navigation, images, and page-specific content instead of assuming the home-page test covers them.
## Replacing Placeholder Content
You still need to provide the real content, as Claude cannot decide what your experience and work should say.
For each page, write the actual text and tell Claude:
```text
Replace the placeholder text on the home page with this content:
Name: [Your Name]
Tagline: [What you do in one sentence]
Intro: [Your 2-3 sentence introduction]
```
Or paste your content directly:
```text
Here's the real content for my about page:
I started my career in finance but realized I was more interested
in building things than analyzing them. After teaching myself to
code, I transitioned into product development...
Update about.html with this content.
```
Real content also tests whether the layout works with your actual heading and paragraph lengths.
## Content Tips
If you're stuck writing content, Claude can help:
```text
I need to write my "about me" section. Here's my background:
- Started in finance, moved to tech
- Now work as a product designer
- Care about accessibility and clean design
Write a friendly, professional 3-paragraph about section.
```
Or give Claude existing content to adapt:
```text
Here's my LinkedIn summary. Rewrite it for my personal website.
Make it more conversational and less corporate.
```
## A Consistency Check
Before moving to visual polish, compare the navigation, fonts, colours, spacing, and footer across every page:
```text
Review all pages in the project. Check that:
- Navigation looks identical on every page
- Fonts are consistent
- Colors match
- Spacing feels the same
- The footer appears on all pages
Fix any inconsistencies you find.
```
Claude can compare the project files and propose consistency fixes. Review the diff, then open every page because a file-level check cannot confirm the rendered result by itself.
## What You Have Now
Your project folder should look like:
```
my-portfolio/
CLAUDE.md
index.html
about.html
projects.html
contact.html
css/
styles.css
.claude/
rules/
css.md
_docs/
plan.md
requirements.md
archive/
home-v1.html
home-v3.html
```
Open every page at desktop and phone widths before moving to visual polish.
> Next up: Making it look even better with visual polish and refinements.
---
# Building your first web page with Claude Code
**Author:** Ivan Misic
**Published:** 2026-01-25
**URL:** https://ivanmisic.net/blog/ai-tools/building-your-first-page
**In plain English**
Build and review the home page before creating the rest of the site. It becomes the working reference for navigation, spacing, type, shared styles, and responsive behavior.
- Ask Claude for several distinct design directions, compare them in the browser, and use the closest one as `index.html`
- Change one visible problem at a time and describe the expected result precisely
- Record the chosen colors, type, spacing, header, and footer in `.claude/rules/css.md` so later sessions receive the same guidance
- Move reusable styles into `css/styles.css` and verify that the HTML keeps the expected class names
- Inspect the source, then test the rendered page at 375px, 768px, and desktop width; a rule file cannot prove the browser result
I would build and review the home page before creating the rest of the site. It gives you one working reference for navigation, spacing, type, and responsive behavior. The written requirements guide Claude, but the browser shows which decisions actually work.
## Ask for Design Options First
Ask for several design options before choosing one, as the first result may lock you into a direction you have not compared.
```text
Build me 3 design directions for the home page with the same content.
Make the layout, typography, and color choices clearly different.
Save them as home-v1.html, home-v2.html, home-v3.html.
```
Open all three in the browser and pick the one closest to your goal. If they look alike, ask Claude to explain what changed before generating another set.
Pick the option closest to your goal and use it as the starting point. It does not need to be final.
```text
I like v2 the best. Let's use that as our starting point.
Rename it to index.html and move the other versions to _docs/archive/.
```
## Review Your Selected Design
Open the selected `index.html` in a browser before changing it. Check the navigation, main heading, planned content, and overall structure against your requirements. Add anything missing in the next step. At this point you only need a usable reference, not a finished page.
## The Iteration Loop
I use a short review loop:
1. **Look at what Claude built:** Open the file in your browser
2. **Identify one thing to change:** Not everything. One thing.
3. **Tell Claude what's wrong:** "The hero text is too small" not "fix the design"
4. **Repeat**
Be specific. Compare:
❌ "Make it better"
✅ "Make the hero heading larger, at least 48px"
❌ "I don't like the colors"
✅ "Change the background to dark blue (#0a1628) and the accent color to a warm orange (#ff6b35)"
❌ "Fix the layout"
✅ "Center the navigation links horizontally and add more space between them"
Change one visible problem at a time until the page is good enough to reuse. The number of rounds depends on the first result and how specific your feedback is.
### Common First-Page Fixes
On a first page, I check spacing, text size, mobile layout, and contrast.
Spacing is usually the first thing that feels off:
```text
Add more padding around the hero section. It feels cramped.
The footer needs more space above it.
```
For text that's too small or too light:
```text
The body text is too small. Use 18px minimum.
Make headings bolder - use font-weight 700.
```
Always check a phone-sized screen:
```text
Check the site on a phone-sized screen. The navigation is broken.
Make sure text doesn't overflow on narrow screens.
```
If the colors aren't quite working:
```text
The contrast between text and background is too low.
Make the links more visible - they blend in too much.
```
## Lock In Your Design Standards
Once the home page works, record its design decisions before building another page. Otherwise Claude may choose different spacing, navigation, or type on the next result.
Tell Claude to capture everything from your home page into a rules file:
```text
Create .claude/rules/css.md from the decisions already present in
index.html and css/styles.css. Record the actual colors, type sizes,
spacing, header, footer, and responsive behavior. Do not invent values.
Treat the working home page as the reference for later pages.
```
Review the generated file before using it. A short rule can be enough:
```markdown
# Design System Rules
- Use the header and footer from index.html as the reference.
- Keep shared styles in css/styles.css.
- Record only colors, sizes, spacing, and breakpoints found in the files.
- Compare each new page with index.html and correct visible drift.
```
Treat this file as the shared reference for later pages. Claude Code loads project rules as context, not as enforced configuration, so compare every new page with the working home page and correct any drift you see.
### Why This Matters
Without a shared reference, one page may have five navigation links while the next adds a sixth or changes the header. After four pages, you can end up maintaining four versions of the same component.
The rules file gives Claude a reference for the shared parts. It does not remove the need to compare the rendered pages.
### Extract Inline Styles (If Needed)
Claude may create the first options with CSS inside the HTML. If the chosen design will become the reference, move those styles into `css/styles.css` so later pages can reuse them.
If Claude does not propose that change, tell it:
```text
Extract all the inline CSS from index.html into css/styles.css.
The HTML should only have class names, no style attributes or